 niklaslenz
ViC305's TWOMODELS-ONESPARK recipe: Qwen3.8-Flash-Next (EXL3 3.05 bpw) next to MiniCPM 4.7
1x NVIDIA DGX Spark (GB10, 128 GB unified memory), one box. Two models are loaded at the same time.

Overall score as of 25 Oct 2026. Scores are relative to the best run in the class today; a better model later moves older runs down.
How the overall score is calculated
| Part | This run | Best in class | Relative | Weight | Points |
|---|---|---|---|---|---|
| Speed, one request | decode 56.2 tok/s | best 56.2 tok/s | 100.0 % | 17.5 % | 17.5 |
| Speed, 8 at once | total 41.5 tok/s | best 125.2 tok/s | 33.2 % | 17.5 % | 5.8 |
| Quality | mean of 7 tests: 66.2 % | best mean 70.8 % | 93.5 % | 25 % | 23.4 |
| Browser check | 8.5 of 10 | 85.0 % | 5 % | 4.3 | |
| My rating | 2 of 10 | 20.0 % | 35 % | 7.0 | |
| Overall | 100 % | 57.9 |
The seven quality tests: MMLU-Pro 68.3 · GPQA 49.0 · IFEval 86.0 · LiveCodeBench 62.5 · long text 8K 67.5 · long text 32K 60.0 · GPQA 30 with thinking 70.0.
The speed part is half the decode speed with one request and half the total speed with 8 requests at once, each relative to the best run of this class; a run without a total for 8 requests at once gets the better of its decode speed alone and the mix with its highest measured total. Quality is relative to the best run of this class, the browser check and my rating are out of 10. The parts are rounded one by one. sparkDash, the memory test and speculative-decoding numbers are not part of it. How the score is made, and the assumption behind it.
What it builds as an agent
Task: Voxel world (3D scene, one HTML file). One attempt, no help. Counted: the final file counts.
The exact promptcopy it and try it yourself↓
This is the task prompt word for word, as we handed it to the agent harness. The harness adds its own system prompt and tools, and some harnesses add short context notes of their own. Qwen Code 0.25.2 also put a space before six of the seven “@” signs in the library addresses of the import map (for example “three @0.170.0”), so the model got the prompt in that form. A run that goes past 90 minutes also gets a short “finish now” message, as the prompt says. To try it yourself, give it to your own coding agent: it needs a shell and a working folder.
Design and create the most impressive, creative, elaborate and detailed
voxel art world you are capable of. The theme and style are ENTIRELY your
choice — pick whatever world you can execute best and push it as far as
you can: scale, variety, detail, color, animation, atmosphere, life.
Surprise me.

Hard requirements:
- Everything ends up in ONE single self-contained HTML file (game.html in
  the current working directory) that opens and runs directly in Chrome.
  Use WebGL and whatever libraries you like, but embed everything —
  no internet access at view time, no external files.
- The scene must present itself: include an automatic slow cinematic
  camera tour (orbiting the world, occasionally zooming in on highlights)
  that starts on load, plus mouse controls (orbit/zoom) for manual viewing.
- All user-facing text (UI, HUD, titles, descriptions, hints) must be in
  ENGLISH, regardless of the language of any project files you encounter.

When finished, verify your HTML actually loads and renders without
console errors, then state DONE with the absolute path of game.html.
Do not ask questions.

How you work (same for every model):
- You work alone in the folder /work (this is the current working directory). Nobody will answer questions. Aim to finish in about 60 minutes. After 90 minutes you will get a message to finish; then you have at most 30 more minutes. Hard stop after 120 minutes.
- Tools on this machine: shell, files, python3 with numpy and Pillow, ffmpeg, node, and `shot.sh game.html` (opens the page in a headless browser, saves a screenshot and prints console errors). There is no internet and no access to other machines.
- Keep a working /work/game.html at all times. If you are stopped, the last version that loaded without errors counts.
- JavaScript libraries available offline in the test browser, through an import map with these exact URLs: "three": "https://cdn.jsdelivr.net/npm/three@0.170.0/build/three.module.js", "three/addons/": "https://cdn.jsdelivr.net/npm/three@0.170.0/examples/jsm/", "simplex-noise": "https://cdn.jsdelivr.net/npm/simplex-noise@4.0.3/dist/esm/simplex-noise.js", "@tweenjs/tween.js": "https://cdn.jsdelivr.net/npm/@tweenjs/tween.js@25.0.0/dist/tween.esm.js", "cannon-es": "https://cdn.jsdelivr.net/npm/cannon-es@0.20.0/dist/cannon-es.js". No other external resources.
- After the scene is built, set `window.scene` to the Three.js scene (if you use Three.js) and `window.ready = true`.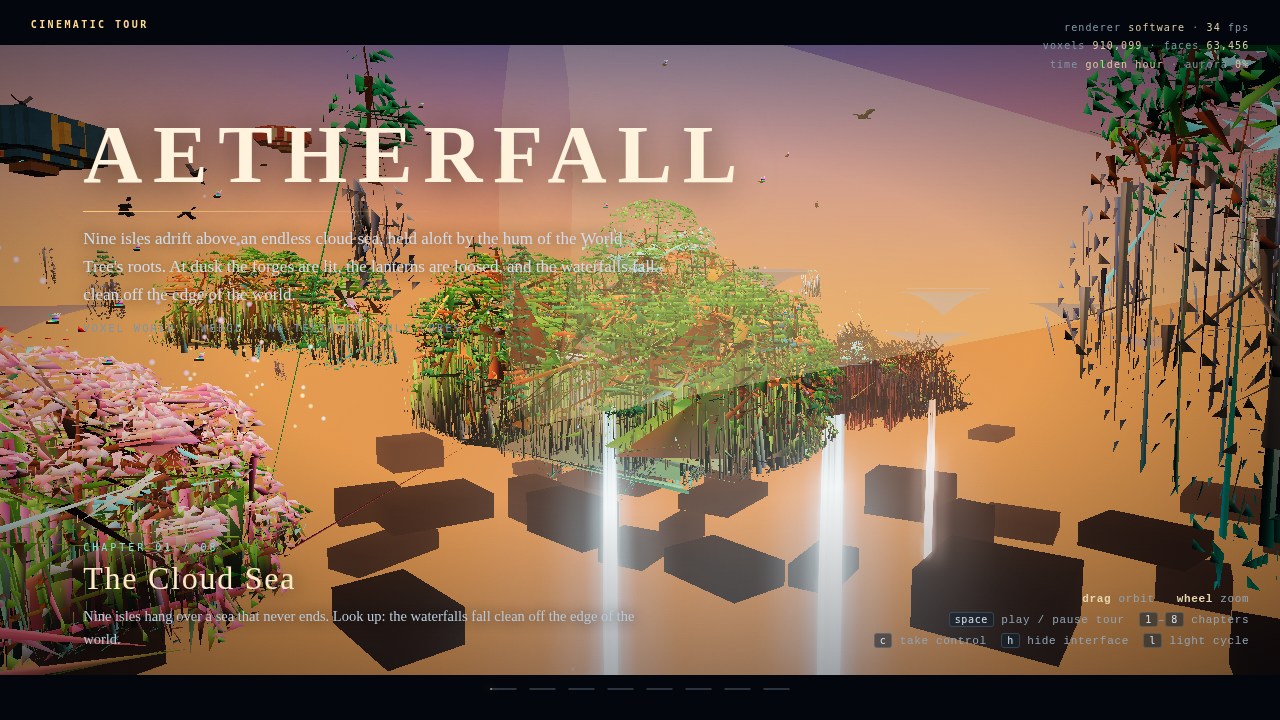
Play it yourself
Open full screenAI-generated The page this setup built, running live in your browser: click into it and use the controls it shows itself (usually drag to look around, scroll to zoom). It needs WebGL and can be slow on a weak graphics card.
The browser check
- page loads without page error1 / 1
- window.ready === true within 30 s1 / 1
- no console errors (whole session)1 / 1
- frame is not blank1 / 1
- frame rate in software GL (rAF over 5 s)0.5 / 1
- world: scene size 0.5 (parts >= 80 or >= 20000 triangles; canvas fallback), visible text English if any 0.51 / 1
- automatic camera tour: the view changes on its own in two successive ~5 s windows (1 each)2 / 2
- animation in the world (nodes / instances / particles moving besides the camera)1 / 1
- OrbitControls: drag and wheel change the picture beyond the animation baseline0 / 1
Measured 2026-10-25. Raw files: check · run info · command · final choice · contract · sampling · gate stats · screenshot · web.mp4 · web-poster.jpg.
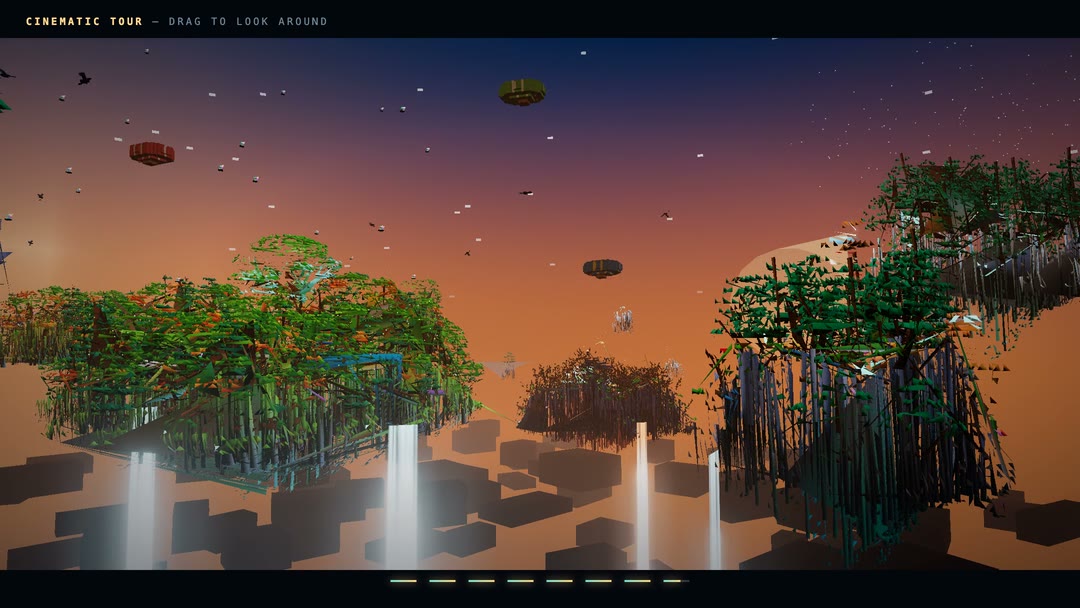
The run's own headless check browser, which renders the page the model built, used up to 999 % CPU. The load monitor counted it as another process. Browser check 8.5 out of 10 (voxel-world task): the page loads without a page error, is ready after 1.9 s, has no console errors, is not blank, shows a world (386 parts, 190,146 triangles, English text), flies the automatic camera tour (the picture changes in both windows) and animates (119 animated nodes). The 1.5 lost points are the frame rate (13.9 frames per second in software rendering without a GPU; 10 give half a point and 20 the full point; here it counts 0.5) and the orbit-controls test (0 of 1: the mouse drag and the mouse wheel changed the picture less than the check needs). The agent (Qwen Code 0.25.2) took 60.9 minutes, one try, no help; the “Time is up. Finish now” message (from 90 minutes) was not needed. 131 requests, no error, none blocked (16,768,492 prompt tokens, 136,555 answer tokens, largest prompt 192,570 of 262,144 tokens; the proxy cut the answer limit to the free context in 37 requests). 19 versions of the page were seen on the way; the first 8 did not load cleanly, the last 11 did, the first clean one came after 39.5 minutes, and the last one counts. Thinking was on with the card's sampling (temperature 1.0, top_p 0.95, top_k 20), answer limit 262,144 tokens. What it built: AETHERFALL, “The Floating Isles of Vharn”, nine voxel islands above a cloud sea (a world tree with a village, a shrine, a smithy, a lighthouse, a snow isle and more), with airships, birds, particle effects, a day and night cycle and an 8-chapter camera tour. My own view in the browser: the check measures that the page runs, not how it looks; I rate this world 2 of 10. In my recording of the tour (recorded with a GPU, seed 42) the trees and bushes are spiky shards, the ground under them shows as dark flat slabs floating over the cloud sea, and the camera often flies through foliage. The load monitor named a headless check browser (up to 999 % CPU) as foreign load during the run; it is the run's own check.
Exact command we measured withfor reproducing↓
You do not need this to run the model. It is the exact command of our measurement, so anyone can repeat the result.
run_showcase.sh --harness qwen-code --task VX --upstream http://127.0.0.1:43537/v1 --model Qwen3.8-Flash-Next-EXL3 --sampling-file $RUN/sampling-show.json --out $RUN/raw/nacht-2410-show-r5/show --limit-s 7200 --inject-after-s 5400 --poll-s 20 --ctx 262144It also built this
Task: Airship dock (3D scene, one HTML file). One attempt, no help. Counted: the final file counts. This extra build test is shown for the full picture; it is not part of the ranking.
The exact promptcopy it and try it yourself↓
This is the task prompt word for word, as we handed it to the agent harness. The harness adds its own system prompt and tools, and some harnesses add short context notes of their own. Qwen Code 0.25.2 also put a space before six of the seven “@” signs in the library addresses of the import map (for example “three @0.170.0”), so the model got the prompt in that form. A run that goes past 90 minutes also gets a short “finish now” message, as the prompt says. To try it yourself, give it to your own coding agent: it needs a shell and a working folder.
Design and build the most impressive, creative, elaborate and detailed steampunk airship dock voxel world you are capable of. Theme: a steampunk airship dock. Everything else (style, story, extra details) is your choice.

How you work:
- You work alone in the folder /work. Nobody will answer questions. Aim to finish in about 60 minutes. After 90 minutes you will get a message to finish; then you have at most 30 more minutes. Hard stop after 120 minutes. Spend the time where it shows in the result.
- Tools on this machine: shell, files, python3 with numpy and Pillow, ffmpeg, node, and `shot.sh index.html` (opens the page in a headless browser, saves a screenshot and prints console errors). There is no internet and no access to other machines.
- You may create your own assets locally with these tools (textures, sky, sounds, music) and embed them in the file as data URIs. Do not download anything.
- Keep a working /work/index.html at all times: write a first working version early, then improve it step by step. If you are stopped, the last version that loaded without errors counts.
- Check your work with `shot.sh` as often as you like, fix every error, and keep improving until you are satisfied. Then stop.

Deliverable: ONE self-contained file /work/index.html that opens and runs in Chrome.
- JavaScript libraries: only these, through an import map with these exact URLs (they work offline in the test browser). Use whatever helps, including all Three.js addons (post-processing, sky, water, noise and so on):
  - "three": "https://cdn.jsdelivr.net/npm/three@0.170.0/build/three.module.js"
  - "three/addons/": "https://cdn.jsdelivr.net/npm/three@0.170.0/examples/jsm/"
  - "simplex-noise": "https://cdn.jsdelivr.net/npm/simplex-noise@4.0.3/dist/esm/simplex-noise.js"
  - "@tweenjs/tween.js": "https://cdn.jsdelivr.net/npm/@tweenjs/tween.js@25.0.0/dist/tween.esm.js"
  - "cannon-es": "https://cdn.jsdelivr.net/npm/cannon-es@0.20.0/dist/cannon-es.js"
- No other external resources. Build every object from cubes (voxels); InstancedMesh is allowed.
- The page fills the whole window and resizes with it. All visible text is in English.
- After the scene is built, set `window.scene` to the Three.js scene and `window.ready = true`.
- An automatic slow cinematic camera tour starts on load. Mouse input switches to OrbitControls (drag to rotate, scroll to zoom).
- Sound, if any, starts only after the first click (browsers block autoplay).
- A small label in the top-left corner: "Steampunk Airship Dock".

Minimum content (go far beyond it):
1. A tall iron docking tower with platforms, stairs or ladders, and a mooring arm at the top.
2. At least two airships, each with a balloon envelope, a gondola and propellers.
3. Big brass gears on the tower or the buildings.
4. Pipes and at least three chimneys that emit rising steam particles.
5. At least one crane and a stack of cargo crates.
6. A ground area with a workshop building and a small rail track.
7. Propellers and gears rotate, steam rises and fades, and one airship slowly approaches the tower, docks, waits and leaves again, in a loop.
8. Warm sunset lighting with shadows.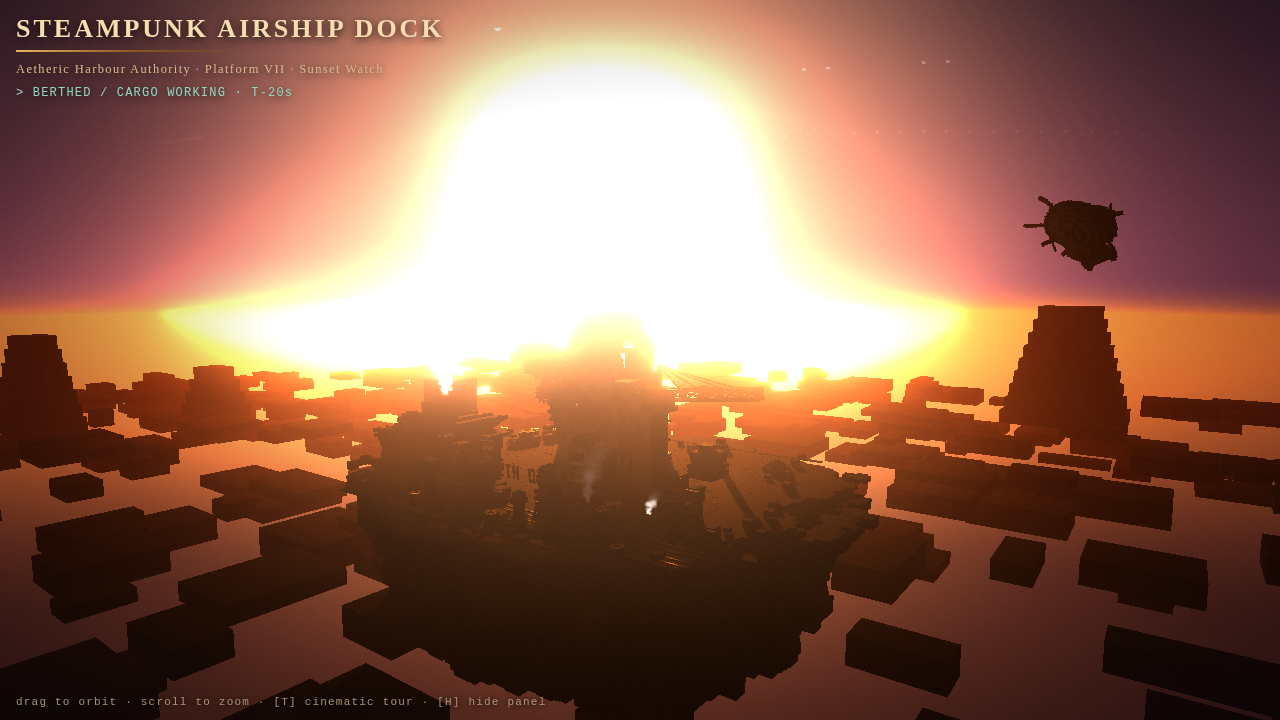
Play it yourself
Open full screenAI-generated The page this setup built, running live in your browser: click into it and use the controls it shows itself (usually drag to look around, scroll to zoom). It needs WebGL and can be slow on a weak graphics card.
The browser check
- page loads without page error1 / 1
- window.ready === true within 30 s1 / 1
- no console errors (whole session)1 / 1
- frame is not blank1 / 1
- frame rate in software GL (rAF over 5 s)0 / 1
- required objects (voxel mass, >=3 steam emitters, >=2 airships, label)1.5 / 2
- motion: pixel diff 0.5, >=3 rotating nodes 0.5, large group translating 12 / 2
- OrbitControls: drag and wheel change the picture beyond the animation baseline0.5 / 1
Measured 2026-10-25. Raw files: check · run info · command · final choice · contract · sampling · gate stats · screenshot · clip.mp4.
The run's own headless check browser, which renders the page the model built, used up to 1420 % CPU. The load monitor counted it as another process. Extra build, not part of the score. This run used the airship-dock prompt (the one the 16 GB and 32 GB classes use), not the voxel-world prompt this page is ranked on. Same box, same server setup, same agent and limits as the voxel-world run above; only the prompt differs. My rating of this extra world: 2.5 of 10 (it does not count in the score). The agent finished by itself after 44.9 minutes, one try, no help; the “finish now” message was not needed. 19 versions of the page were seen on the way, 9 loaded without errors, and the last one counts. Browser check 8.0 out of 10: the frame rate lost its point (0.58 frames per second in software rendering), the check for the required objects gave 1.5 of 2 (no visible label found in the top left; 4 airships and 5 steam emitters found by the check's own heuristic), and the orbit test gave half a point. 54 requests, no error, none blocked (4,800,734 prompt tokens, 91,463 answer tokens, largest prompt 150,010 of 262,144 tokens, the proxy cut the answer limit twice). Answer limit 262,144 tokens, context 262,144 tokens, thinking on with the card's sampling.
Exact command we measured withfor reproducing↓
You do not need this to run the model. It is the exact command of our measurement, so anyone can repeat the result.
run_showcase.sh --harness qwen-code --task K1 --upstream http://127.0.0.1:44679/v1 --model Qwen3.8-Flash-Next-EXL3 --sampling-file $RUN/sampling-show.json --out $RUN/raw/nacht-2410-xdock-show-r0/show --limit-s 7200 --inject-after-s 5400 --poll-s 20 --ctx 262144How fast it runs
| Measurement | Result |
|---|---|
| Decode | 56.2 tok/s |
| Words per second | 39.8 words/s |
| Characters per second | 280.7 chars/s |
| Decode, code prompt | 58.4 tok/s |
| Decode, prose prompt | 54.0 tok/s |
| Spread of the decode runs (CV) | 0.7 % |
| Spread of the code runs (CV) | 0.7 % |
| Spread of the prose runs (CV) | 0.5 % |
| Decode, window 1 | 57.5 tok/s |
| Prefill at 2K | 369.1 tok/s |
| Prefill at 8K | 575.0 tok/s |
| Prefill at 32K | 661.7 tok/s |
| Time to first token at 2K | 6.3 s |
| Time to first token at 8K | 16.0 s |
| Time to first token at 32K | 53.6 s |
| Draft acceptance rate | 63.4 % |
| 1 request at once (total) | 36.9 tok/s |
| 2 at once (total) | 38.7 tok/s |
| 4 at once (total) | 42.3 tok/s |
| 8 at once (total) | 41.5 tok/s |
| 1 request at once (per request) | 36.9 tok/s |
| 2 at once (per request) | 25.2 tok/s |
| 4 at once (per request) | 16.0 tok/s |
| 8 at once (per request) | 9.0 tok/s |
| Server slots (from the recipe) | 1 slots |
| Long answer, wall time | 146.9 s |
Method: code+prose; 2 run(s) each; 512 tokens; 1 warm-up(s); median; requests at once: C1,C2,C4,C8 at once; 2 rounds each; 512 tokens per request; prose prompt; total = all tokens / wall time, per request = tokens / end-to-end time; median over the rounds. Measured 2026-10-25. Raw files: speed result · speed contract · log · long answer.
Requests at once: the server has 1 slot (from the author's recipe). C2, C4, C8 exceed the slots: the extra requests wait in the queue, and they were measured anyway. The speed test ran ViC305's recipe as it starts (vcruz305/TWOMODELS-ONESPARK-Qwen3.8-Flash-Next-and-MiniCPM-V-4.7-EXL3 at commit 0fc9145, bin/up.sh): MiniCPM-V 4.7 first on port 8898 (loaded, idle), then the main model Qwen3.8-Flash-Next EXL3 3.05 bpw on port 8899 with ExLlamaV3 (vcruz305 fork, master e43b0740) and TabbyAPI (vcruz305, main 880e6b8b), single profile (1 job at a time), context 262,144 tokens, Q8 KV cache, MTP with 5 dynamic draft tokens, nothing overridden. The recipe pins no engine commit; the two commits named here were the heads on 24 Oct 2026, the day the recipe was built on this box. Only the Qwen model on port 8899 is measured; MiniCPM stays loaded and idle, so the memory situation is the one of the recipe. The recipe's own agent test with Hermes was not run. Sampling is the non-thinking sampling of the Qwen3.8-Flash-Next card (temperature 0.7, top_p 0.8, top_k 20, presence penalty 1.5), seed 42. The headline 56.15 tok/s is the mean of the code prompt (58.36) and the prose prompt (53.95), medians of two runs each (spread 0.7 % and 0.5 %). The draft acceptance was 63.4 %. The recipe's README names higher figures from its own test: 88.6 tok/s for code and 55.9 tok/s for prose (a 400-token test with MiniCPM idle). Speed v2 gives 58.36 for code and 53.95 for prose (512 tokens, a different prompt). The prose figure is close to the author's, the code figure is well below it. I did not find out why (not diagnosed), so the figures on this page are the ones measured. Requests at once: the recipe's single profile has one slot (bin/env.sh:26 to serve.sh:19), so C2, C4 and C8 exceed it and the extra requests wait in a queue; the totals count the wait for the first token and are therefore below the single-request decode speed. Prefill is slow on short prompts (369 tok/s at 2K) and rises with size (662 tok/s at 32K).
Exact command we measured withfor reproducing↓
You do not need this to run the model. It is the exact command of our measurement, so anyone can repeat the result.
python3 speed2.py --base-url http://127.0.0.1:44069/v1 --label run-speed-r0 --prompts $BENCH/repos/rigmark-v2/prompts-v2.json --output $RUN/raw/nacht-2410-speed-r0/work/speed2 --contract $RUN/raw/nacht-2410-speed-r0/work/speed2/speed-contract.json --parts decode,prefill,conc,l1 --prefill-depths 2048,8192,32768 --prompt-ids code,prose --runs 2 --max-tokens 512 --warmups 1 --prefill-runs 3 --conc-levels 1,2,4,8 --conc-rounds 2 --conc-max-tokens 512 --conc-prompt prose --tokenizer-json $HOME/models-2410/Qwen3.8-Flash-Next-EXL3/tokenizer.json --sampling {"temperature": 0.7, "top_p": 0.8, "top_k": 20, "min_p": 0.0, "presence_penalty": 1.5} --sampling-source Qwen/Qwen3.8-Flash-Next README.md:343 (Instruct/non-thinking) and :342 (Thinking), local copy not published; generation_config.json (1.0/20/0.95) = thinking default only, not used for instruct --model Qwen3.8-Flash-Next-EXL3 --no-cache-prompt --server-log $RUN/logs/server-A.log --engine-version-file $RUN/logs/engine-version.txt --server-slots 1 --server-slots-source vcruz305/TWOMODELS-ONESPARK-...@0fc9145 bin/env.sh:26 (QWEN_PROFILE single) -> Qwen3.8-Flash-Next-EXL3-DGX-Spark-recipe@49850ef exllamav3-tabby/serve.sh:19 (single: MAX_BATCH_SIZE 1, CACHE_SIZE 262144); README.md:59 ('1 job'). The recipe's other profile 'concurrent' (serve.sh:18, batch 4, pool 1,048,576) is NOT the two-model setup: its larger KV pool is not budgeted in the two-model memory table (README.md:9-12, :63-65).How well it answers
| Test | Result95 % margin | Right | Cut offcount as wrong | Raw files | |
|---|---|---|---|---|---|
| MMLU-Pro 400 fixed questions, letter only | 68.3 % ± 4.5 pts | 273 / 400 | 1 | answers · summary · log · contract | command |
| GPQA Diamond 198 questions, letter only | 49.0 % ± 6.9 pts | 97 / 198 | 0 | answers · summary · log · contract | command |
| IFEval 200 fixed prompts, strict | 86.0 % ± 4.8 pts | 172 / 200 | 0 | summary · log · contract | command |
| LiveCodeBench 40 newest tasks, the code runs | 62.5 % ± 14.4 pts | 25 / 40 | 0 | summary · log · contract | command |
| Long text 8K 4 tasks x 10 at 8192 tokens | 67.5 % ± 14.0 pts | 27 / 40 | 0 | log · contract · answers · summary | command |
| Long text 32K 4 tasks x 10 at 32768 tokens | 60.0 % ± 14.5 pts | 24 / 40 | 0 | log · contract · answers · summary | command |
| GPQA 30, thinking on 30 questions, limit 16,384 tokens | 70.0 % ± 15.6 pts median 4,646 tokens, 84.0 s per question | 21 / 30 | 8 | log · contract · summary | command |
Thinking off, except the last test. Seed 42. Sampling from the model card. A cut-off answer counts as wrong. Measured 2026-10-25.
Note from the run: Quality ran on the same server setup as the speed test, one question at a time (the recipe has one slot; same questions, limits and seed 42 for every question); the median time per question of the thinking test (84.0 s) was measured under that setup. MMLU-Pro and GPQA Diamond ran with a short answer limit (the answer is one letter); IFEval and LiveCodeBench with longer limits. Answers cut off at their limit count as wrong: 1 of the 400 MMLU-Pro answers (limit 48 tokens) and 8 of the 30 GPQA answers with thinking (limit 16,384 tokens); no GPQA Diamond, IFEval, long-text or LiveCodeBench answer was cut. Two answer files of this run are not published: ifeval.jsonl (the first quality run) and gpqa_think.jsonl (the thinking run). The filter for public files drops a file when a word in an answer text looks like a banned one (here a common English verb in IFEval answers that the filter reads as an internal host name, and longitude values with a trailing letter in the GPQA thinking text, which look like a unit figure). Their summary files are online. (The register row for the count of cut answers carries only the LiveCodeBench run; the MMLU-Pro cut answer is in the raw files of the first quality run, inst-r1.) LiveCodeBench ran a second time: my first try (row inst-r3, 05:00) did not start, because the box's own quiet check saw a foreign process (containerd at 32 % CPU) and refused to measure; nothing was sent to the server. The value on this page is the rerun (row inst-r6, 40 questions, 62.5 %). No other test was repeated. GPQA Diamond ran from the public mirror fingertap/GPQA-Diamond (198 questions), because the original is gated and I had no access token. Sampling: instruct tests with the Qwen3.8-Flash-Next card's non-thinking values (temperature 0.7, top_p 0.8, top_k 20, presence penalty 1.5), GPQA with thinking with the thinking values (temperature 1.0, top_p 0.95, top_k 20).
Exact commands we measured withfor reproducing↓
You do not need this to run the model. It is the exact command of our measurement, so anyone can repeat the result.
bash tools/quality2/measure_all.sh tools/quality2/cards/qwen38-flashnext-exl3-3.05bpw-twomodels-minicpm47-vcruz305-0fc9145-1x.json --parts mmlupro --job nacht-2410bash tools/quality2/measure_all.sh tools/quality2/cards/qwen38-flashnext-exl3-3.05bpw-twomodels-minicpm47-vcruz305-0fc9145-1x.json --parts gpqa --job nacht-2410bash tools/quality2/measure_all.sh tools/quality2/cards/qwen38-flashnext-exl3-3.05bpw-twomodels-minicpm47-vcruz305-0fc9145-1x.json --parts ifeval --job nacht-2410bash tools/quality2/measure_all.sh tools/quality2/cards/qwen38-flashnext-exl3-3.05bpw-twomodels-minicpm47-vcruz305-0fc9145-1x.json --parts lcb --job nacht-2410bash tools/quality2/measure_all.sh tools/quality2/cards/qwen38-flashnext-exl3-3.05bpw-twomodels-minicpm47-vcruz305-0fc9145-1x.json --parts ruler --job nacht-2410bash tools/quality2/measure_all.sh tools/quality2/cards/qwen38-flashnext-exl3-3.05bpw-twomodels-minicpm47-vcruz305-0fc9145-1x.json --parts ruler --job nacht-2410bash tools/quality2/measure_all.sh tools/quality2/cards/qwen38-flashnext-exl3-3.05bpw-twomodels-minicpm47-vcruz305-0fc9145-1x.json --parts think --job nacht-2410How much context fits
| Context size | Prompttokens | Filled | First token | Prefilltok/s, as the server reports it | Decodetok/s | Peak memoryGiB | Result |
|---|---|---|---|---|---|---|---|
| 4K 4,096 tokens | 3,798 | 92.7 % | 5.1 s | 751 | 27.4 | 85.86 | answered (stop) |
| 8K 8,192 tokens | 7,750 | 94.6 % | 8.8 s | 883 | 48.3 | 85.26 | answered (stop) |
| 16K 16,384 tokens | 15,798 | 96.4 % | 16.6 s | 955 | 51.0 | 85.49 | answered (stop) |
| 32K 32,768 tokens | 31,604 | 96.4 % | 28.9 s | 1,093 | 55.6 | 85.91 | answered (stop) |
| 64K 65,536 tokens | 62,733 | 95.7 % | 52.8 s | 1,189 | 51.7 | 86.32 | answered (stop) |
| 128K 131,072 tokens | 125,892 | 96.0 % | 103.7 s | 1,214 | 54.3 | 87.00 | answered (stop) |
Memory test. The recipe fixes the context (262,144 tokens), so the server is started once with the recipe's own command and reserves its memory up front. Then, for each size (4K, 8K, 16K ... up to the largest size tested), one prompt that fills about 95 % of that size is sent, and the model must answer. The largest size that answered counts; it is the highest size tested, not a limit of the setup. Decode speed is measured on every answer. Peak memory is, on each of the one boxes, the rise of used memory (MemTotal - MemAvailable) over the idle value before the step; the table and the number show the highest of the one boxes. Unified memory, so GPU and CPU share it. Measured 2026-10-25. Raw files: result of every step · log · contract.
Note from the run: fit memory per node, highest rise over idle: local 87.0 GiB The recipe fixes the context at 262,144 tokens (MAX_SEQ_LEN, bin/env.sh:34), so the server was started once with the card's command and the sizes are prompt sizes: 4K, 8K, 16K, 32K, 64K and 128K tokens. For each size one prompt that fills about 95 % of it was sent, and the model answered at every size (the largest prompt was 125,892 tokens). The test did not go beyond 128K; the server context of 262,144 tokens was not filled. The memory number is the rise of used memory over the idle value of the GB10 box (unified memory, GPU and CPU share it) with both models loaded: 85.86 GiB at a 4,096-token context step, 87.0 GiB at the largest prompt. The decode speed at the largest prompt was 54.31 tok/s (one request).
Exact command we measured withfor reproducing↓
You do not need this to run the model. It is the exact command of our measurement, so anyone can repeat the result.
bash tools/quality2/measure_all.sh tools/quality2/cards/qwen38-flashnext-exl3-3.05bpw-twomodels-minicpm47-vcruz305-0fc9145-1x.json --parts fit --job nacht-2410Also made this possible
- EXL3 quant of Qwen3.8-Flash-Next and ExLlamaV3 engine
 turboderp@turboderp_ Hugging Face GitHub
- Base model (Qwen3.8-Flash-Next)
 QwenHugging Face @Alibaba_Qwen GitHub Website
Run it yourself
What you need and how to start it, step by step. The results below come from exactly this setup.
What you need
- Hardware
- 1x NVIDIA DGX Spark (GB10, 128 GB unified memory), one box. Two models are loaded at the same time.
- Model
- Qwen3.8-Flash-Next EXL3 3.05 bpw (turboderp, branch 3.05bpw_h5_ng5 @69e33439), main agent of TWOMODELS-ONESPARK next to MiniCPM-V 4.7 35B-A3B SAGE EXL3 3.74 bpw (idle)
- EXL3 quant of Qwen3.8-Flash-Next and ExLlamaV3 engine
- huggingface.co/turboderp/Qwen3.8-Flash-Next-exl3
- Base model (Qwen3.8-Flash-Next)
- huggingface.co/Qwen/Qwen3.8-Flash-Next
- Engine
- ExLlamaV3 + TabbyAPI on one DGX Spark, Qwen as the main model with MTP drafts, MiniCPM-V 4.7 loaded beside it, context 262,144 tokens — the program that loads the model and answers requests
- Recipe (TWOMODELS-ONESPARK), MiniCPM quant, engine forks
- github.com/vcruz305/TWOMODELS-ONESPARK-Qwen3.8-Flash-Next-and-MiniCPM-V-4.7-EXL3 by ViC305 (Victor Cruz)
Steps
Get the recipe and the model files from the list above. The list has no link for the engine (ExLlamaV3 + TabbyAPI on one DGX Spark, Qwen as the main model with MTP drafts, MiniCPM-V 4.7 loaded beside it, context 262,144 tokens).
Start the server with this command. It loads the model into memory.
bash bin/setup.sh && bash bin/download.sh && bash bin/up.sh
Exact command we measured withfor reproducing↓
You do not need this to run the model. It is the start text exactly as our run recorded it, with the engine build in front, so anyone can repeat the result.
ExLlamaV3 (vcruz305 fork master e43b0740) + TabbyAPI (vcruz305 main 880e6b8b), MTP 5 draft tokens dynamic, Q8 KV, profile single; recipe vcruz305/TWOMODELS-ONESPARK @0fc91457; bash bin/setup.sh && bash bin/download.sh && bash bin/up.sh Context and sampling: 262,144 tokens (recipe, README.md:59), Q8 KV cache, 1 job (one request at a time), MTP with 5 dynamic draft tokens (serve.sh:26-27), n-gram table streamed from NVMe (QWEN_NGRAM_RAM false, bin/env.sh:27); MiniCPM loaded and idle (Q4 KV, 1,048,576 pool, 8 jobs); seed 42. Sampling from the Qwen3.8-Flash-Next card, per part: instruct tests with the non-thinking values (temperature 0.7, top_p 0.8, top_k 20, presence penalty 1.5); GPQA with thinking and the build tests with the thinking values (temperature 1.0, top_p 0.95, top_k 20). The answer limit for the build tests was 262,144 tokens (Qwen README: 262,144 tokens for the reasoning part, 131,072 for the final answer); the test proxy cut it to the free context per request. Agent for the build tests: Qwen Code 0.25.2, the agent of the Qwen family; the recipe's own agent (Hermes) was not used. Hardware: 1x NVIDIA DGX Spark (GB10, 128 GB unified memory), one box. Two models are loaded at the same time.. All raw files of this setup: raw/v2/qwen38-flash-next-1spark-twomodels-exl3.
Mia's own benchmark, run unchanged
This is Mia's own benchmark tool (commit 21a3511), run unchanged. It has its own section on this page, and it is never mixed with my numbers. A cut-off answer counts as wrong here, so a value can differ from sparkDash's own screen.
| Test | Result95 % margin | Right | Cut offcount as wrong | Raw files | |
|---|---|---|---|---|---|
| Quality QA 150 questions | 90.0 % ± 4.8 pts | 135 / 150 | 0 | summary | command |
| Quality MMLU 285 questions | 89.8 % ± 3.5 pts | 256 / 285 sparkDash's own screen counts 257 right | 9 | summary | command |
| Tool Eval Quick 15 scenarios, tool use | 87 / 100 | 13 / 15 passed | — | tool eval result · tool eval report · tool eval command · summary | command |
| Decode, 1 request at once first token 525 ms | 103.0 tok/s | — | — | decode result · summary | command |
| Prefill at 4K first token 6.5 s | 644.6 tok/s | — | — | prefill result · summary | command |
| Prefill at 8K first token 10.5 s | 792.3 tok/s | — | — | prefill result · summary | command |
| Prefill at 16K first token 17.0 s | 976.0 tok/s | — | — | prefill result · summary | command |
| Prefill at 32K first token 34.4 s | 957.8 tok/s | — | — | prefill result · summary | command |
Seed 1234 applies to the two quality tests; decode, prefill and tool eval send no seed. The benchmark client ran on a separate machine that is never part of the measured group. Measured 2026-10-25. Version 2.50.0, commit 21a3511.
QA. Quality QA, 150 items, seed 1234, temperature 0, thinking off, 4 requests at once (Mia's default). An answer cut off at the token limit counts as wrong. ± is the 95 % margin (Wilson).
MMLU. Quality MMLU, 285 items (5 for each of 57 subjects, 4 answers), seed 1234, temperature 0, thinking off. An answer cut off at the token limit counts as wrong. ± is the 95 % margin (Wilson).
Decode. Decode bench, 1 request at once, 400 tokens, prompt type structured, temperature 0, thinking off. No seed is sent.
Prefill. Prefill bench at 4K, 8K, 16K and 32K tokens. sparkDash skips a size that does not fit into the context. No seed is sent.
Tool Eval Quick. Tool Eval Quick: tool-eval-bench (SeraphimSerapis, commit c61319b), 15 core scenarios (--short), --no-think, --timeout 120. Score 0 to 100. No seed is sent.
Note from the run: sparkDash runs its own tests (its own QA and MMLU questions at temperature 0, thinking off, a cut-off answer counts as wrong; no QA answer and 9 of the 285 MMLU answers were cut off at the answer limit and count as wrong), so its decode and prefill values are not comparable with Speed v2 above: its decode test uses a structured prompt (103 tok/s, which the recipe's n-gram table likes), Speed v2 a code and a prose prompt. The sparkDash client ran on another machine and was never part of the measured group. sparkDash's quality.json (the item list behind the 285 MMLU answers) is not published: the filter for public files dropped it because the word "power" appears in one answer text. Its summary.json is online (257 of 285 right as sparkDash counts; 256 here, because one of the 257 was cut off at the answer limit and counts as wrong).
Exact commands we measured withfor reproducing↓
You do not need this to run the model. It is the exact command of our measurement, so anyone can repeat the result.
python3 tools/quality2/sparkdash_client.py tools/quality2/cards/qwen38-flashnext-exl3-3.05bpw-twomodels-minicpm47-vcruz305-0fc9145-1x.json <box> --client <client machine> --job nacht-2410 --out $RUNtool-eval-bench --base-url http://127.0.0.1:<port> --model Qwen3.8-Flash-Next-EXL3 --short --no-think --timeout 120 --json-file $BENCH/sparkdash-client/runs/work/tooleval/result.json --no-live