 niklaslenz
Mia's one-click kit: Qwen3.8-27B, EXL3 3.0 bpw + MTP
1x RTX 5060 Ti 16 GB

Overall score as of 20 Oct 2026. This is the only complete run in the class so far, so it is rank 1. Scores are relative to the best run in the class today; a better model later moves older runs down.
How the overall score is calculated
| Part | This run | Best in class | Relative | Weight | Points |
|---|---|---|---|---|---|
| Speed | decode 52.9 tok/s | best 52.9 tok/s | 100.0 % | 45 % | 45.0 |
| Quality | mean of 7 tests: 66.1 % | best mean 66.1 % | 100.0 % | 30 % | 30.0 |
| Browser check | 7 of 10 | 70.0 % | 5 % | 3.5 | |
| My rating | 4 of 10 | 40.0 % | 20 % | 8.0 | |
| Overall | 100 % | 86.5 |
The seven quality tests: MMLU-Pro 59.8 · GPQA 43.4 · IFEval 81.5 · LiveCodeBench 47.5 · long text 8K 80.0 · long text 32K 77.5 · GPQA 30 with thinking 73.3.
Speed and quality are relative to the best run of this class, the browser check and my rating are out of 10. The parts are rounded one by one. sparkDash, the memory test and speculative-decoding numbers are not part of it. How the score is made, and the assumption behind it.
What it builds as an agent
Task: Airship dock (3D scene, one HTML file). One attempt, no help. Counted: the final file counts.
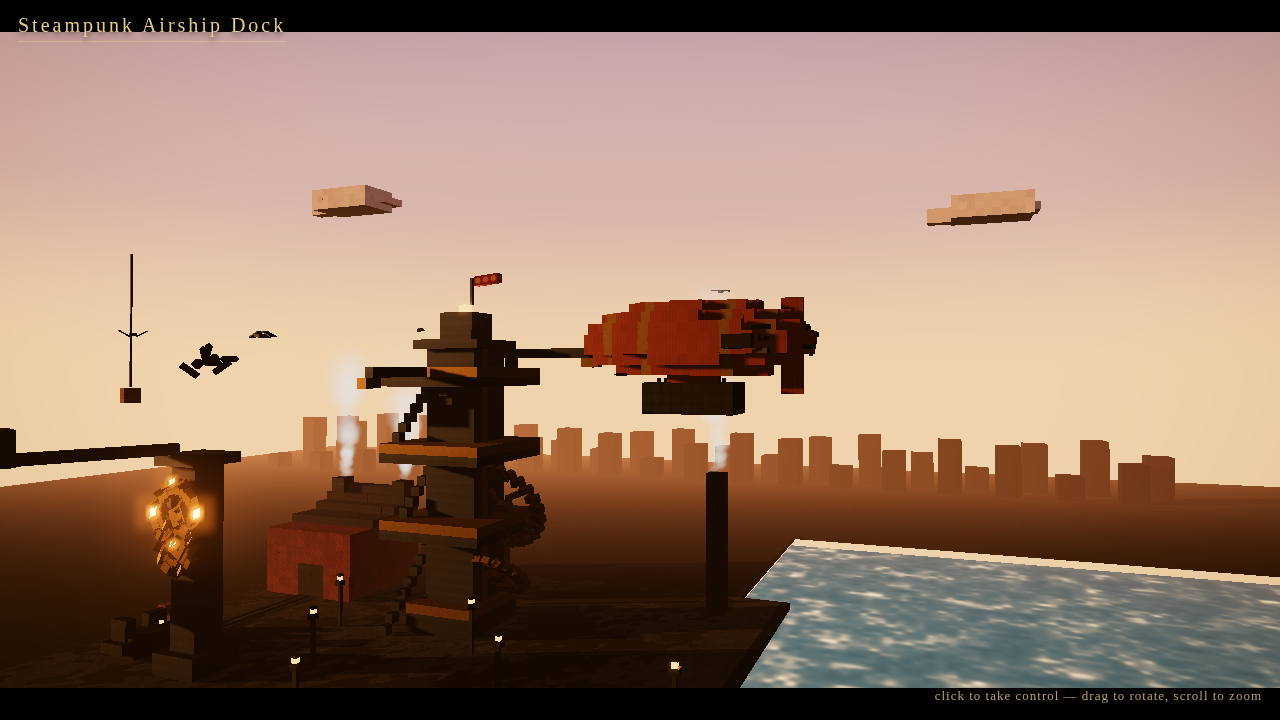
Play it yourself
Open full screenAI-generated The page this setup built, running live in your browser: click into it and use the controls it shows itself (usually drag to look around, scroll to zoom). It needs WebGL and can be slow on a weak graphics card.
The browser check
- page loads without page error1 / 1
- window.ready === true within 30 s1 / 1
- no console errors (whole session)1 / 1
- frame is not blank1 / 1
- frame rate in software GL (rAF over 5 s)0 / 1
- required objects (voxel mass, >=3 steam emitters, >=2 airships, label)1 / 2
- motion: pixel diff 0.5, >=3 rotating nodes 0.5, large group translating 12 / 2
- OrbitControls: drag and wheel change the picture beyond the animation baseline0 / 1
Measured 2026-10-20. Raw files: check · run info · command · final choice · contract · sampling · screenshot · clip.mp4.
The run's own headless check browser, which renders the page the model built, used up to 1497 % CPU. The load monitor counted it as another process. Hard stop: the agent was still working when the time limit of 120 minutes was reached (7,202 s, 106 requests, 89,206 tokens written), so the harness was stopped. The last version of the page that loaded without errors counts: the final file (99,761 bytes), which also loaded cleanly in the check. Browser check 7.0 out of 10: the page loads, runs without console errors, is not blank, shows the label and animates. The three lost points: frame rate (3.7 frames per second in software rendering without a GPU), required objects (the check found the voxel mass and the label but counted no steam emitters and no airships; the count is a heuristic and can miss them) and mouse control (drag and wheel changed the picture less than the check requires). Earlier attempts on this setup scored 0 of 10 because of faults in our test chain (thinking temperature 0.6 instead of the model card's 1.0; the harness gave up after 300 s of silence from the server) and are not shown. The test gate between harness and server sent an empty keepalive every 30 s while the server was silent; the harness ignores it, model, prompt, settings and time limits are unchanged. Thinking sampling is the model card's (temperature 1.0 / top_p 0.95 / top_k 20), not the kit's default 0.6. The answer limit is the model card's 262,144 tokens (the kit's own harness default is 65,536); with a context of 117,760 the real ceiling per answer is the room left in the context, and the gate and the kit server clamp each request to it.
Exact command we measured withfor reproducing↓
You do not need this to run the model. It is the exact command of our measurement, so anyone can repeat the result.
run_showcase.sh --harness dsh-a2 --task K1 --upstream http://127.0.0.1:38605/v1 --model qwen3.8-27b-exl3-3.0bpw --sampling-file $RUN/sampling-show.json --out $RUN/raw/plan-2010-show-r2/show --limit-s 7200 --inject-after-s 5400 --poll-s 20 --ctx 117760How fast it runs
| Measurement | Result |
|---|---|
| Decode | 52.9 tok/s |
| Words per second | 37.0 words/s |
| Characters per second | 243.3 chars/s |
| Spread of the decode runs (CV) | 7.4 % |
| Decode, window 1 | 52.7 tok/s |
| Prefill at 2K | 997.5 tok/s |
| Prefill at 8K | 1026.6 tok/s |
| Prefill at 32K | 917.7 tok/s |
| Time to first token at 2K | 2.1 s |
| Time to first token at 8K | 8.0 s |
| Time to first token at 32K | 35.7 s |
| 1 request at once (total) | 47.8 tok/s |
| Long answer, wall time | 101.0 s |
| Decode, code prompt | 53.6 tok/s |
| Decode, prose prompt | 52.1 tok/s |
| Spread of the code runs (CV) | 7.4 % |
| Spread of the prose runs (CV) | 0.0 % |
Method: code+prose; 2 run(s) each; 512 tokens; 1 warm-up(s); median. Measured 2026-10-20. Raw files: speed result · speed contract · log · long answer.
Exact command we measured withfor reproducing↓
You do not need this to run the model. It is the exact command of our measurement, so anyone can repeat the result.
python3 speed2.py --base-url http://127.0.0.1:41285/v1 --label run-speed-r5 --prompts $BENCH/repos/rigmark-v2/prompts-v2.json --output $RUN/raw/plan-2010-speed-r5/work/speed2 --contract $RUN/raw/plan-2010-speed-r5/work/speed2/speed-contract.json --parts decode,prefill,conc,l1 --prefill-depths 2048,8192,32768 --prompt-ids code,prose --runs 2 --max-tokens 512 --warmups 1 --prefill-runs 3 --tokenizer-json $HOME/tp2-bench/models/Qwen3.8-27B-EXL3-4.0bpw/tokenizer.json --tokenizer-python $BENCH/venv/bin/python --sampling {"temperature": 0.7, "top_p": 0.8, "top_k": 20, "min_p": 0.0, "presence_penalty": 1.5} --sampling-source thinking = Mia kit server defaults: MiaAI-Lab/Qwen3.8-27B-16gb-NVIDIA-GPUs-one-click-install@bbb11db:README.md:497 ("Defaults: temperature 0.6, top-p 0.95, top-k 20, thinking on") and tools/serve_openai.py:961-963 (request values win; min_p and presence_penalty are not read by the kit server, 0.0 = Qwen model card). instruct (speed2 etc., thinking off) = Qwen model card as in the card box-5-qwen38-27b-exl3-3.0bpw-kit-5060ti: https://huggingface.co/Qwen/Qwen3.8-27B README.md line 253. --model qwen3.8-27b-exl3-3.0bpw --no-cache-prompt --server-log $RUN/logs/server-A.log --engine-version-file $RUN/logs/engine-version.txtHow well it answers
| Test | Result95 % margin | Right | Cut offcount as wrong | Raw files | |
|---|---|---|---|---|---|
| MMLU-Pro 400 fixed questions, letter only | 59.8 % ± 4.8 pts | 239 / 400 | 0 | answers · summary · log · contract | command |
| GPQA Diamond 198 questions, letter only | 43.4 % ± 6.8 pts | 86 / 198 | 0 | answers · summary · log · contract | command |
| IFEval 200 fixed prompts, strict | 81.5 % ± 5.4 pts | 163 / 200 | 0 | answers · summary · log · contract | command |
| LiveCodeBench 40 newest tasks, the code runs | 47.5 % ± 14.8 pts | 19 / 40 | 3 | answers · summary · log · contract | command |
| Long text 8K 4 tasks x 10 at 8192 tokens | 80.0 % ± 12.1 pts | 32 / 40 | 0 | log · contract · answers · summary | command |
| Long text 32K 4 tasks x 10 at 32768 tokens | 77.5 % ± 12.6 pts | 31 / 40 | 0 | log · contract · answers · summary | command |
| GPQA 30, thinking on 30 questions, limit 16,384 tokens | 73.3 % ± 15.1 pts median 6,740 tokens, 122.4 s per question | 22 / 30 | 7 | log · contract · answers · summary | command |
Thinking off, except the last test. Seed 42. Sampling from the model card. A cut-off answer counts as wrong. Measured 2026-10-20.
Exact commands we measured withfor reproducing↓
You do not need this to run the model. It is the exact command of our measurement, so anyone can repeat the result.
bash tools/quality2/measure_all.sh tools/quality2/cards/qwen38-27b-exl3-3.0bpw-kit-dsh-5060ti.json --parts mmlupro --job plan-2010bash tools/quality2/measure_all.sh tools/quality2/cards/qwen38-27b-exl3-3.0bpw-kit-dsh-5060ti.json --parts gpqa --job plan-2010bash tools/quality2/measure_all.sh tools/quality2/cards/qwen38-27b-exl3-3.0bpw-kit-dsh-5060ti.json --parts ifeval --job plan-2010bash tools/quality2/measure_all.sh tools/quality2/cards/qwen38-27b-exl3-3.0bpw-kit-dsh-5060ti.json --parts lcb --job plan-2010bash tools/quality2/measure_all.sh tools/quality2/cards/qwen38-27b-exl3-3.0bpw-kit-dsh-5060ti.json --parts ruler --job plan-2010bash tools/quality2/measure_all.sh tools/quality2/cards/qwen38-27b-exl3-3.0bpw-kit-dsh-5060ti.json --parts ruler --job plan-2010bash tools/quality2/measure_all.sh tools/quality2/cards/qwen38-27b-exl3-3.0bpw-kit-dsh-5060ti.json --parts think --job plan-2010How much context fits
| Context size | Prompttokens | Filled | First token | Prefilltok/s, as the server reports it | Decodetok/s | Peak memoryGiB | Result |
|---|---|---|---|---|---|---|---|
| 4K 4,096 tokens | 3,798 | 92.7 % | 2.3 s | 1,663 | 45.1 | 12.75 | answered (stop) |
| 8K 8,192 tokens | 7,750 | 94.6 % | 4.4 s | 1,768 | 47.3 | 12.92 | answered (stop) |
| 16K 16,384 tokens | 15,798 | 96.4 % | 12.7 s | 1,242 | 50.0 | 13.01 | answered (stop) |
| 32K 32,768 tokens | 31,604 | 96.4 % | 31.1 s | 1,016 | 51.2 | 13.31 | answered (stop) |
| 64K 65,536 tokens | 62,733 | 95.7 % | 76.4 s | 821 | 47.7 | 14.04 | answered (stop) |
| 115K 117,760 tokens | 113,268 | 96.2 % | 179.1 s | 633 | 38.8 | 15.19 | answered (stop) |
Memory test. For each context size (4K, 8K, 16K ... up to the largest size tested for the setup) the server is started again with that context, one prompt that fills about 95 % of the context is sent, and the model must answer. The largest size that loaded and answered counts. Decode speed is measured on that answer at the largest size. Peak memory is the GPU memory in use (nvidia-smi); the GPU was empty before each start. Measured 2026-10-20. Raw files: result of every step · log · contract.
Note from the run: Highest TESTED step is 117760 tokens = the context of the kit's 3.0 bpw profile (steps 4096 to 117760 all loaded and answered, first_failure none); a larger context was not tested, so 117760 is the profile, not a proven hardware limit. Prompt filled to 96.19 % (113268 tokens). Peak 15.19 GiB (nvidia-smi, GPU 1) at the largest step; decode 38.78 tok/s at that fill (at 4K-32K fill: 45.1-51.2 tok/s). The list of sizes ends at 117,760 tokens, which is the context of the kit's 3.0 bpw profile (all steps from 4,096 to 117,760 loaded and answered), so this is the profile's size, not a proven hardware limit; a larger context was not tested. Decode speed at this fill is 38.8 tok/s (45 to 51 tok/s at 4K to 32K).
Exact command we measured withfor reproducing↓
You do not need this to run the model. It is the exact command of our measurement, so anyone can repeat the result.
bash tools/quality2/measure_all.sh tools/quality2/cards/qwen38-27b-exl3-3.0bpw-kit-dsh-5060ti.json --parts fit --job plan-2010Also made this possible
- Model
 QwenHugging Face @Alibaba_Qwen GitHub Website
- Quant (EXL3)
 turboderp@turboderp_ Hugging Face GitHub
Run it yourself
What you need and how to start it, step by step. The results below come from exactly this setup.
What you need
- Hardware
- 1x RTX 5060 Ti 16 GB
- System
- Linux (we used the Linux start script)
- Model
- turboderp/Qwen3.8-27B-exl3 3.00bpw
- Quant (EXL3)
- huggingface.co/turboderp/Qwen3.8-27B-exl3
- Engine
- ExLlamaV3 1.6.0 — the program that loads the model and answers requestsBuild and settings we used: ExLlamaV3 1.6.0 (Mia one-click kit bbb11db), MTP
- Recipe (one-click kit)
- github.com/MiaAI-Lab/Qwen3.8-27B-16gb-NVIDIA-GPUs-one-click-install by Mia (MiaAI-Lab)
Steps
Get the recipe and the model files from the list above. We ran the engine, ExLlamaV3 1.6.0, with the recipe (Mia one-click kit bbb11db).
Put these settings into the recipe's
.envfile. One setting per line.MODEL_DIR=Qwen3.8-27B-EXL3-3.0bpw CONTEXT_SIZE=117760 CACHE_QUANT=4 GPU_MEM_GB=14.7 DRAFT=mtp PROFILE=3.0bpw-118kStart the server with this command. It loads the model into memory.
CUDA_DEVICE_ORDER=PCI_BUS_ID \
  CUDA_VISIBLE_DEVICES=1 bash linux/start.sh \
  --no-harness \
  --no-pick
What the parts mean
CUDA_DEVICE_ORDER=PCI_BUS_IDcounts the GPUs in slot order, the same order nvidia-smi showsCUDA_VISIBLE_DEVICES=1which NVIDIA GPU the program may use: the number of the GPU in our machine (with one GPU it is 0)MODEL_DIR=Qwen3.8-27B-EXL3-3.0bpwthe folder with the model filesCONTEXT_SIZE=117760the context window in tokens: how much text the model can see at onceDRAFT=mtpMTP (multi-token prediction): the model guesses several tokens ahead and checks them, which makes answers fasterCACHE_QUANT=4keeps the context memory (KV cache) in 4 bits, which uses less GPU memoryGPU_MEM_GB=14.7how much GPU memory, in GB, the kit plans withPROFILE=3.0bpw-118kthe name of the kit profile these settings belong to; the name gives the bits per weight and the context size
Exact command we measured withfor reproducing↓
You do not need this to run the model. It is the start text exactly as our run recorded it, with the engine build in front, so anyone can repeat the result.
ExLlamaV3 1.6.0 (Mia one-click kit bbb11db), MTP; CUDA_DEVICE_ORDER=PCI_BUS_ID CUDA_VISIBLE_DEVICES=1 bash linux/start.sh --no-harness --no-pick (.env: MODEL_DIR=Qwen3.8-27B-EXL3-3.0bpw CONTEXT_SIZE=117760 CACHE_QUANT=4 GPU_MEM_GB=14.7 DRAFT=mtp PROFILE=3.0bpw-118k)Context and sampling: 117,760 tokens (KV int4, 3.0 bpw profile), seed 42, cache_prompt false (kit: not available). Sampling per part: speed and quality tests with thinking off and the Qwen model-card instruct sampling (temp 0.7 / top_p 0.8 / top_k 20 / min_p 0.0 / presence 1.5); GPQA 30 with thinking on and the kit's own sampling (temp 0.6 / top_p 0.95 / top_k 20, kit README.md:497); build test with thinking on and the model-card thinking sampling (temp 1.0 / top_p 0.95 / top_k 20 / min_p 0.0 / presence 0.0), in the agent harness the kit ships, DeepSeek Harness 0.1.3-alpha.2. Hardware: 1x RTX 5060 Ti 16 GB. All raw files of this setup: raw/v2/qwen38-27b-exl3-3-0bpw-mtp-5060ti.
Mia's own benchmark, run unchanged
This is Mia's own benchmark tool (commit 21a3511), run unchanged. It has its own section here and its own column on the class page, and it is never mixed with my numbers. A cut-off answer counts as wrong here, so a value can differ from sparkDash's own screen.
| Test | Result95 % margin | Right | Cut offcount as wrong | Raw files | |
|---|---|---|---|---|---|
| Quality QA 150 questions | 78.7 % ± 6.5 pts | 118 / 150 | 0 | summary | command |
| Quality MMLU 285 questions | 84.6 % ± 4.2 pts | 241 / 285 | 15 | summary | command |
| Tool Eval Quick 15 scenarios, tool use | 90 / 100 | 13 / 15 passed | — | tool eval result · tool eval report · tool eval command · summary | command |
| Decode, 1 request at once first token 333 ms | 91.1 tok/s | — | — | decode result · summary | command |
| Prefill at 4K first token 4.0 s | 1107.4 tok/s | — | — | prefill result · summary | command |
| Prefill at 8K first token 8.0 s | 1070.9 tok/s | — | — | prefill result · summary | command |
| Prefill at 16K first token 16.5 s | 1015.2 tok/s | — | — | prefill result · summary | command |
| Prefill at 32K first token 35.8 s | 924.0 tok/s | — | — | prefill result · summary | command |
Seed 1234 applies to the two quality tests; decode, prefill and tool eval send no seed. The benchmark client ran on a separate machine that is never part of the measured group. Measured 2026-10-20. Version 2.50.0, commit 21a3511.
QA. Quality QA, 150 items, seed 1234, temperature 0, thinking off, 4 requests at once (Mia's default). An answer cut off at the token limit counts as wrong. ± is the 95 % margin (Wilson).
MMLU. Quality MMLU, 285 items (5 for each of 57 subjects, 4 answers), seed 1234, temperature 0, thinking off. An answer cut off at the token limit counts as wrong. ± is the 95 % margin (Wilson).
Decode. Decode bench, 1 request at once, 400 tokens, prompt type structured, temperature 0, thinking off. No seed is sent.
Prefill. Prefill bench at 4K, 8K, 16K and 32K tokens. sparkDash skips a size that does not fit into the context. No seed is sent.
Tool Eval Quick. Tool Eval Quick: tool-eval-bench (SeraphimSerapis, commit c61319b), 15 core scenarios (--short), --no-think, --timeout 120. Score 0 to 100. No seed is sent.
Note from the run: sparkDash 2.50.0 (@21a3511) on a client machine (never in the measured group), Quality: seed 1234, temperature 0, thinking off, a truncated answer counts as wrong; decode, prefill and tool eval send no seed; own row, never mixed with quality-v2.
Exact commands we measured withfor reproducing↓
You do not need this to run the model. It is the exact command of our measurement, so anyone can repeat the result.
python3 tools/quality2/sparkdash_client.py tools/quality2/cards/qwen38-27b-exl3-3.0bpw-kit-dsh-5060ti.json <box> --client <client machine> --job plan-2010 --out $RUNtool-eval-bench --base-url http://127.0.0.1:<port> --model qwen3.8-27b-exl3-3.0bpw --short --no-think --timeout 120 --json-file $BENCH/sparkdash-client/runs/work/tooleval/result.json --no-live