 niklaslenz
antirez's ds4 recipe: DeepSeek-V4.1-Flash-1017 (Q2 GGUF)
Mac Studio M5 Ultra 256 GB

Overall score as of 23 Oct 2026. Scores are relative to the best run in the class today; a better model later moves older runs down.
How the overall score is calculated
| Part | This run | Best in class | Relative | Weight | Points |
|---|---|---|---|---|---|
| Speed, one request | decode 54.5 tok/s | best 152.5 tok/s | 35.7 % | 17.5 % | 6.3 |
| Speed, 8 at once | total 50.5 tok/s | best 112.7 tok/s | 44.9 % | 17.5 % | 7.9 |
| Quality | mean of 7 tests: 69.7 % | best mean 69.7 % | 100.0 % | 25 % | 25.0 |
| Browser check | 8.5 of 10 | 85.0 % | 5 % | 4.3 | |
| My rating | 3.5 of 10 | 35.0 % | 35 % | 12.3 | |
| Overall | 100 % | 55.6 |
The seven quality tests: MMLU-Pro 72.3 · GPQA 49.0 · IFEval 87.5 · LiveCodeBench 67.5 · long text 8K 72.5 · long text 32K 62.5 · GPQA 30 with thinking 76.7.
The speed part is half the decode speed with one request and half the total speed with 8 requests at once, each relative to the best run of this class; a run without a total for 8 requests at once gets the better of its decode speed alone and the mix with its highest measured total. Quality is relative to the best run of this class, the browser check and my rating are out of 10. The parts are rounded one by one. sparkDash, the memory test and speculative-decoding numbers are not part of it. How the score is made, and the assumption behind it.
What it builds as an agent
Task: Voxel world (3D scene, one HTML file). One attempt, no help. Counted: the final file counts.
The exact promptcopy it and try it yourself↓
This is the task prompt word for word, as we handed it to the agent harness. The harness adds its own system prompt and tools, and some harnesses add short context notes of their own. A run that goes past 90 minutes also gets a short “finish now” message, as the prompt says. To try it yourself, give it to your own coding agent: it needs a shell and a working folder.
Design and create the most impressive, creative, elaborate and detailed
voxel art world you are capable of. The theme and style are ENTIRELY your
choice — pick whatever world you can execute best and push it as far as
you can: scale, variety, detail, color, animation, atmosphere, life.
Surprise me.

Hard requirements:
- Everything ends up in ONE single self-contained HTML file (game.html in
  the current working directory) that opens and runs directly in Chrome.
  Use WebGL and whatever libraries you like, but embed everything —
  no internet access at view time, no external files.
- The scene must present itself: include an automatic slow cinematic
  camera tour (orbiting the world, occasionally zooming in on highlights)
  that starts on load, plus mouse controls (orbit/zoom) for manual viewing.
- All user-facing text (UI, HUD, titles, descriptions, hints) must be in
  ENGLISH, regardless of the language of any project files you encounter.

When finished, verify your HTML actually loads and renders without
console errors, then state DONE with the absolute path of game.html.
Do not ask questions.

How you work (same for every model):
- You work alone in the folder /work (this is the current working directory). Nobody will answer questions. Aim to finish in about 60 minutes. After 90 minutes you will get a message to finish; then you have at most 30 more minutes. Hard stop after 120 minutes.
- Tools on this machine: shell, files, python3 with numpy and Pillow, ffmpeg, node, and `shot.sh game.html` (opens the page in a headless browser, saves a screenshot and prints console errors). There is no internet and no access to other machines.
- Keep a working /work/game.html at all times. If you are stopped, the last version that loaded without errors counts.
- JavaScript libraries available offline in the test browser, through an import map with these exact URLs: "three": "https://cdn.jsdelivr.net/npm/three@0.170.0/build/three.module.js", "three/addons/": "https://cdn.jsdelivr.net/npm/three@0.170.0/examples/jsm/", "simplex-noise": "https://cdn.jsdelivr.net/npm/simplex-noise@4.0.3/dist/esm/simplex-noise.js", "@tweenjs/tween.js": "https://cdn.jsdelivr.net/npm/@tweenjs/tween.js@25.0.0/dist/tween.esm.js", "cannon-es": "https://cdn.jsdelivr.net/npm/cannon-es@0.20.0/dist/cannon-es.js". No other external resources.
- After the scene is built, set `window.scene` to the Three.js scene (if you use Three.js) and `window.ready = true`.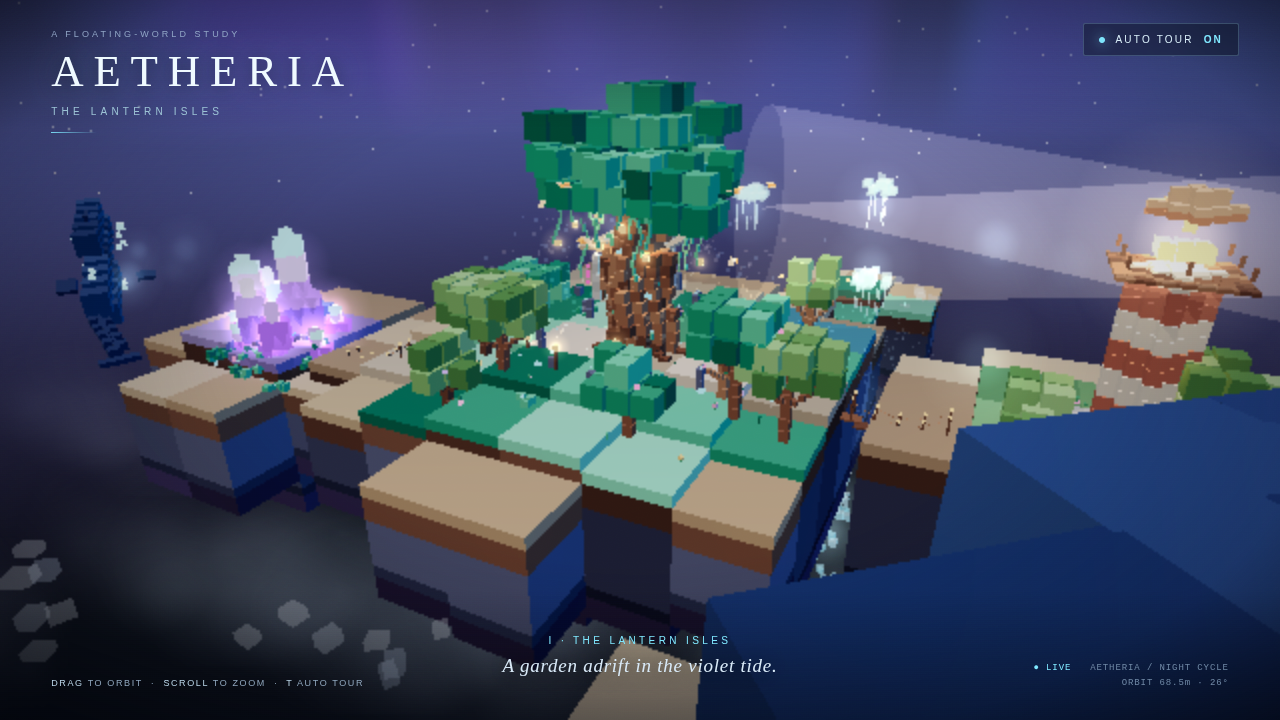
Play it yourself
Open full screenAI-generated The page this setup built, running live in your browser: click into it and use the controls it shows itself (usually drag to look around, scroll to zoom). It needs WebGL and can be slow on a weak graphics card.
The browser check
- page loads without page error1 / 1
- window.ready === true within 30 s1 / 1
- no console errors (whole session)1 / 1
- frame is not blank1 / 1
- frame rate in software GL (rAF over 5 s)0.5 / 1
- world: scene size 0.5 (parts >= 80 or >= 20000 triangles; canvas fallback), visible text English if any 0.51 / 1
- automatic camera tour: the view changes on its own in two successive ~5 s windows (1 each)2 / 2
- animation in the world (nodes / instances / particles moving besides the camera)1 / 1
- OrbitControls: drag and wheel change the picture beyond the animation baseline0 / 1
Measured 2026-10-23. Raw files: run info · command · final choice · contract · sampling · gate stats · check · check · screenshot · clip.mp4.
Other processes used up to 401 % CPU during the run. Browser check 8.5 out of 10 (voxel-world task), measured on a second machine: the check that ran together with the agent run did not start, because the Docker VM on the Mac has 4 CPU cores and the check needs 16, so the run's own contract lists no score. I re-ran the same check on a Linux box with 16 or more cores from a copy of the run's final index.html (same sha256, checked by the tool) and took over only its score; its check.json is the evidence. The page loads, runs without console errors, is not blank, shows a world (about 4,466 parts, 54,842 triangles, English text), flies an automatic camera tour in both windows and animates (136 animated nodes); the 1.5 lost points are the frame rate (13.51 frames per second in software rendering without a GPU, 20 are needed: half a point) and the orbit check (mouse drag and wheel changed the picture, but less than the check needs: 44.6 and 54.8 against 60.8, 1 point). The score depends a little on the box: the same file scored 9.5 out of 10 on a second Linux box (the check does not start with fewer than 16 CPUs), where the orbit check passed (evidence in check-second-box/check.json). I show the first result, 8.5. The agent (DeepSeek Harness 0.2.1-rc.2, the harness DeepSeek ships) finished by itself after 72.9 minutes, one try, no help; the “finish now” message (from 90 minutes) was not needed. 21 versions of the page were seen, 17 loaded without errors, and the last one counts. 100 requests, none blocked (4,936,431 prompt tokens, 132,976 answer tokens); the longest answer had 25,166 tokens and none ended at the limit. The limit per answer was 393,216 tokens, the default of the ds4 server (the DeepSeek model card asks for at least 262,144 tokens). Thinking was on, sampling temperature 1.0 and top_p 1.0.
Exact command we measured withfor reproducing↓
You do not need this to run the model. It is the exact command of our measurement, so anyone can repeat the result.
run_showcase.sh --harness dsh-021 --task VX --upstream http://127.0.0.1:54708/v1 --model deepseek-v4-flash --sampling-file $HOME/quality2-runs/quality-v2-261022-mac-ds41-1017-q2-ds4-kernelpool-72ccf36/sampling-show.json --out $RUN/quality-v2-261022-mac-ds41-1017-q2-ds4-kernelpool-72ccf36-show-r2/show --limit-s 7200 --inject-after-s 5400 --poll-s 20 --ctx 524288How fast it runs
| Measurement | Result |
|---|---|
| Decode | 54.5 tok/s |
| Words per second | 37.9 words/s |
| Characters per second | 245.0 chars/s |
| Decode, code prompt | 54.5 tok/s |
| Decode, prose prompt | 54.5 tok/s |
| Spread of the decode runs (CV) | 0.3 % |
| Spread of the code runs (CV) | 0.3 % |
| Spread of the prose runs (CV) | 0.2 % |
| Decode, window 1 | 54.5 tok/s |
| Prefill at 2K | 1000.5 tok/s |
| Prefill at 8K | 1450.2 tok/s |
| Prefill at 32K | 1475.2 tok/s |
| Time to first token at 2K | 2.0 s |
| Time to first token at 8K | 5.6 s |
| Time to first token at 32K | 22.2 s |
| 1 request at once (total) | 45.7 tok/s |
| 2 at once (total) | 55.8 tok/s |
| 4 at once (total) | 56.2 tok/s |
| 8 at once (total) | 50.5 tok/s |
| 1 request at once (per request) | 45.7 tok/s |
| 2 at once (per request) | 27.9 tok/s |
| 4 at once (per request) | 14.2 tok/s |
| 8 at once (per request) | 8.7 tok/s |
| Server slots (from the recipe) | 5 slots |
| Long answer, wall time | 144.3 s |
Method: code+prose; 2 run(s) each; 512 tokens; 1 warm-up(s); median; requests at once: C1,C2,C4,C8 at once; 2 rounds each; 512 tokens per request; prose prompt; total = all tokens / wall time, per request = tokens / end-to-end time; median over the rounds. Measured 2026-10-23. Raw files: speed result · speed contract · log · long answer.
Requests at once: the server has 5 slots (from the author's recipe). C8 exceeds the slots: the extra requests wait in the queue, and they were measured anyway. The speed test ran with the setup of the engine author's documentation for a big Mac: antirez's Q2 GGUF (IQ2_XXS experts with Q2_K, imatrix) in kernelpool's fork of ds4 (branch ds41-perf, commit 72ccf36) on Metal, in ds4's batched mode with 5 sessions (--batched-session 5: the most that ds4's start check accepts at a context of 524,288 tokens per session, which is my setting), no speculation or drafting was used (ds4's speculative decoding for V4.1, DSpark, needs a separate drafter file, and ds4 does not use it with batched sessions). Sampling is the DeepSeek model card's: temperature 1.0 and top_p 1.0 (ds4's own min_p 0.05 default stays), seed 42, the request flag for no thinking. The headline 54.47 tok/s is the mean of the code prompt (54.45) and the prose prompt (54.49), medians of two runs each (spread 0.32 % and 0.17 %). The server has 5 slots, so 8 requests at once exceed them: three requests wait for a free slot, and I measured the 8-at-once level anyway (total 50.5 tok/s, 2 to 4 at once give about 56). The “1 request at once” total (45.66 tok/s) is lower than the decode headline because that test counts the whole answer time, including the wait for the first token.
Exact command we measured withfor reproducing↓
You do not need this to run the model. It is the exact command of our measurement, so anyone can repeat the result.
python3 speed2.py --base-url http://127.0.0.1:50374/v1 --label quality-v2-261022-mac-ds41-1017-q2-ds4-kernelpool-72ccf36-speed-r0 --prompts $BENCH/repos/rigmark-v2/prompts-v2.json --output $RUN/quality-v2-261022-mac-ds41-1017-q2-ds4-kernelpool-72ccf36-speed-r0/quality-v2-261022-mac-ds41-1017-q2-ds4-kernelpool-72ccf36-speed-r0/speed2 --contract $RUN/quality-v2-261022-mac-ds41-1017-q2-ds4-kernelpool-72ccf36-speed-r0/quality-v2-261022-mac-ds41-1017-q2-ds4-kernelpool-72ccf36-speed-r0/speed2/speed-contract.json --parts decode,prefill,conc,l1 --prefill-depths 2048,8192,32768 --prompt-ids code,prose --runs 2 --max-tokens 512 --warmups 1 --prefill-runs 3 --conc-levels 1,2,4,8 --conc-rounds 2 --conc-max-tokens 512 --conc-prompt prose --tokenizer-json $HOME/models/ds41-1017-lsq3-g128-mlx/tokenizer.json --tokenizer-python $HOME/not published --sampling {"temperature": 1.0, "top_p": 1.0} --sampling-source DeepSeek-V4.1-Flash-1017 model card (deepseek-ai, rev 1bae0e10, README 'Recommended sampling parameters' temperature 1.0, top_p 1.0, max_tokens >= 256K). ds4 README (copy $HOME/engines/ds4-kernelpool-2210/author-files/README.md) names server defaults 'temperature 1, top-p 1, and min-p 0.05': min_p is not sent by us, the ds4 default 0.05 applies and is logged. --model deepseek-v4-flash --no-cache-prompt --server-log $RUN/server-A.log --engine-version-file $RUN/engine-version.txt --server-slots 5 --server-slots-source kernelpool/ds4 @72ccf363 docs/SERVER.md:55 (--batched-session N) and :72 'Metal, resident V4.1 Flash | Native decoding for 2-8 sessions' (copy $HOME/engines/ds4-kernelpool-2210/author-files/SERVER.md); option ds4_server.c:15681. N = 5 = the largest N that ds4's own startup check accepts at ctx 524288 (full residency): 1-5 start, 6 needs 234.99 GiB, 7 248.52, 8 262.06 > safe budget 224.00 GiB (table: $HOME/engines/ds4-kernelpool-2210/diag-2210/, start logs). Page note: the author's batched mode (--batched-session), 5 sessions is the most that fits 512K context per session on 256 GB.How well it answers
| Test | Result95 % margin | Right | Cut offcount as wrong | Raw files | |
|---|---|---|---|---|---|
| MMLU-Pro 400 fixed questions, letter only | 72.3 % ± 4.4 pts | 289 / 400 | 2 | summary · log · contract | command |
| GPQA Diamond 198 questions, letter only | 49.0 % ± 6.9 pts | 97 / 198 | 15 | answers · summary · log · contract | command |
| IFEval 200 fixed prompts, strict | 87.5 % ± 4.6 pts | 175 / 200 | 0 | answers · summary · log · contract | command |
| LiveCodeBench 40 newest tasks, the code runs | 67.5 % ± 14.0 pts | 27 / 40 | 9 | summary · summary · answers · log · contract | command |
| Long text 8K 4 tasks x 10 at 8192 tokens | 72.5 % ± 13.4 pts | 29 / 40 | 3 | log · contract · answers · summary | command |
| Long text 32K 4 tasks x 10 at 32768 tokens | 62.5 % ± 14.4 pts | 25 / 40 | 3 | log · contract · answers · summary | command |
| GPQA 30, thinking on 30 questions, limit 16,384 tokens | 76.7 % ± 14.6 pts median 2,425 tokens, 137.9 s per question | 23 / 30 | 4 | log · contract · answers · summary | command |
Thinking off, except the last test. Seed 42. Sampling from the model card. A cut-off answer counts as wrong. Measured 2026-10-23.
Note from the run: MMLU-Pro and GPQA Diamond ran with an answer limit of 1,024 tokens. The model sometimes explains before it gives the letter: in my first run with the usual 48-token limit, 20 of 400 MMLU-Pro answers and 22 of 198 GPQA answers were cut off and counted as wrong (67.75 % and 46.46 %). I ran both tests again with 1,024 tokens (same questions, seed 42, same sampling and setup). This page shows only the 1,024-token values and never mixes them with the 48-token run. Even at 1,024 tokens, 2 of 400 MMLU-Pro answers and 15 of 198 GPQA answers were cut off and count as wrong. 6 of the 80 long-text answers and 4 of 30 GPQA answers with thinking (limit 16,384 tokens) were cut off too. LiveCodeBench: in the original run the code sandbox did not start for 30 of the 40 answers, because the Docker VM on the Mac was not reachable. My tool counted them as failed and printed 0.0 %. That is a fault of my test setup, not of the model. I ran the 30 stored answers again through the same sandbox program on a DGX Spark (same code and tests, no new model answers): 27 passed and 3 failed (abc399_e, abc400_d, arc196_a), so 27 of 40 = 67.5 %. 9 answers cut off at the 32,768-token limit and 1 answer without code count as wrong. The register rows of this value say “regraded on box-2”; the original result (0 of 40, infra_error_n 30) is in lcb.summary.json, the re-graded one in lcb.regraded.summary.json, and the re-run of the 30 answers in lcb/regrade-sandbox-only.jsonl.
Exact commands we measured withfor reproducing↓
You do not need this to run the model. It is the exact command of our measurement, so anyone can repeat the result.
bash tools/quality2/measure_all.sh tools/quality2/cards/ds41-1017-q2-ds4-kernelpool-72ccf36.json --parts mmlupro --job quality-v2-261023-mac-ds4-mcq1024bash tools/quality2/measure_all.sh tools/quality2/cards/ds41-1017-q2-ds4-kernelpool-72ccf36.json --parts gpqa --job quality-v2-261023-mac-ds4-mcq1024bash tools/quality2/measure_all.sh tools/quality2/cards/ds41-1017-q2-ds4-kernelpool-72ccf36.json --parts ifeval --job quality-v2-261023-mac-ds41-1017-q2-ds4-kernelpool-72ccf36bash tools/quality2/measure_all.sh tools/quality2/cards/ds41-1017-q2-ds4-kernelpool-72ccf36.json --parts lcb --job quality-v2-261023-mac-ds41-1017-q2-ds4-kernelpool-72ccf36bash tools/quality2/measure_all.sh tools/quality2/cards/ds41-1017-q2-ds4-kernelpool-72ccf36.json --parts ruler --job quality-v2-261023-mac-ds41-1017-q2-ds4-kernelpool-72ccf36bash tools/quality2/measure_all.sh tools/quality2/cards/ds41-1017-q2-ds4-kernelpool-72ccf36.json --parts ruler --job quality-v2-261023-mac-ds41-1017-q2-ds4-kernelpool-72ccf36bash tools/quality2/measure_all.sh tools/quality2/cards/ds41-1017-q2-ds4-kernelpool-72ccf36.json --parts think --job quality-v2-261023-mac-ds41-1017-q2-ds4-kernelpool-72ccf36How much context fits
| Context size | Prompttokens | Filled | First token | Prefilltok/s, as the server reports it | Decodetok/s | Peak memoryGiB | Result |
|---|---|---|---|---|---|---|---|
| 4K 4,096 tokens | 3,892 | 95.0 % | — | — | — | 147.04 | answered (length) |
| 8K 8,192 tokens | 7,783 | 95.0 % | — | — | — | 151.63 | answered (length) |
| 16K 16,384 tokens | 15,565 | 95.0 % | — | — | — | 154.68 | answered (length) |
| 32K 32,768 tokens | 31,129 | 95.0 % | — | — | — | 157.85 | answered (stop) |
| 64K 65,536 tokens | 62,259 | 95.0 % | — | — | — | 158.92 | answered (stop) |
| 128K 131,072 tokens | 124,515 | 95.0 % | — | — | — | 162.53 | answered (length) |
Memory test. For each context size (4K, 8K, 16K ... up to the largest size tested for the setup) the server is started again with that context, one prompt that fills about 95 % of the context is sent, and the model must answer. The largest size that loaded and answered counts. Decode speed is measured on that answer at the largest size. Peak memory is the rise of used memory over the idle value before each server start (unified memory, so GPU and CPU share it). Measured 2026-10-23. Raw files: result of every step · log · contract.
Note from the run: The idle memory before the steps was not constant: 33.4 GiB before the first step, 28.7 GiB before the last one. Each peak is counted over the idle value before its own step. Each size from 4K to 128K started the server fresh with that context, loaded and answered; the largest size tested is 131,072 tokens. The setup's own context is 524,288 tokens per session (my setting), which this test did not fill, so 131,072 is the largest size tested, not the largest the setup can load. The memory number is the highest rise of used memory over the idle value (unified memory), 162.53 GiB at the largest step. The main weights (151.77 GiB) stay in memory; the Engram tables (188.83 GiB) are read from the SSD. ds4 reports no timings, so the decode speed at each size is not available.
Exact command we measured withfor reproducing↓
You do not need this to run the model. It is the exact command of our measurement, so anyone can repeat the result.
bash tools/quality2/measure_all.sh tools/quality2/cards/ds41-1017-q2-ds4-kernelpool-72ccf36.json --parts fit --job quality-v2-261022-mac-ds41-1017-q2-ds4-kernelpool-72ccf36Also made this possible
- Model
 DeepSeekHugging Face @deepseek_ai GitHub Website
- Engine fork ds41-perf (commit 72ccf36)
 kernelpool (Tarjei Mandt)@kernelpool GitHub
- Q2 GGUF weightsAantirez/deepseek-v4.1-flash-ggufHugging Face
Run it yourself
What you need and how to start it, step by step. The results below come from exactly this setup.
What you need
- Hardware
- Mac Studio M5 Ultra 256 GB
- System
- macOS (the Mac above)
- Model
- DeepSeek-V4.1-Flash-1017 (antirez/deepseek-v4.1-flash-gguf @9dcee516, DwarfStar calibrated GGUF)
- Q2 GGUF weights
- huggingface.co/antirez/deepseek-v4.1-flash-gguf
- Engine
- ds4 (DwarfStar, kernelpool fork, commit 72ccf36) on a Mac Studio, Q2 GGUF, 5 sessions in batched mode — the program that loads the model and answers requests · github.com/antirez/ds4Build and settings we used: ds4 / DwarfStar kernelpool fork ds41-perf @72ccf363 (Metal, source build Oct 22, 2026)
Steps
Get the engine and the model files from the list above.
Start the server with this command. It loads the model into memory. When the model has loaded, the server waits for requests on port 8888, only from this computer.
ds4-server \
  -m DeepSeek-V4.1-Flash-1017-IQ2_XXS-Q2_K-imatrix.gguf \
  --ctx 524288 \
  --batched-session 5 \
  --host 127.0.0.1 \
  --port 8888 \
  --chdir src
The file names are the ones we used. Run the command in the folder that holds them, or put the full path in front of each name.
What the parts mean
-m DeepSeek-V4.1-Flash-1017-IQ2_XXS-Q2_K-imatrix.ggufthe model file it loads--host 127.0.0.1who can connect: only this computer--port 8888the network port the server listens on
Exact command we measured withfor reproducing↓
You do not need this to run the model. It is the start text exactly as our run recorded it, with the engine build in front, so anyone can repeat the result.
ds4 / DwarfStar kernelpool fork ds41-perf @72ccf363 (Metal, source build Oct 22, 2026); ds4-server -m $HOME/models/ds41f-q2-1017-antirez-9dcee516/DeepSeek-V4.1-Flash-1017-IQ2_XXS-Q2_K-imatrix.gguf --ctx 524288 --batched-session 5 --host 127.0.0.1 --port 8888 --chdir $HOME/engines/ds4-kernelpool-2210/src (via not published start)Context and sampling: 524,288 tokens per session (--ctx, my setting; 5 sessions is the most that ds4's start check accepts at this size on 256 GB), the author's batched mode with 5 sessions (docs/SERVER.md:55 and :72), seed 42, requests ask for no prompt cache. Sampling as the DeepSeek model card gives it: temperature 1.0, top_p 1.0 (ds4's own min_p 0.05 default stays, README.md:206), the same with thinking on and off. The main weights (151.77 GiB) stay in memory, the Engram tables (188.83 GiB) are read from the SSD. Speed and quality tests with thinking off; GPQA 30 and the build test with thinking on. Build test: DeepSeek Harness 0.2.1-rc.2, answer limit 393,216 tokens (the ds4 server default). No speculation or drafting was used (see the speed note); vision was not used (text only). Hardware: Mac Studio M5 Ultra 256 GB. All raw files of this setup: raw/v2/deepseek-v41-flash-mac-q2-ds4.
Mia's own benchmark, run unchanged
This is Mia's own benchmark tool (commit 21a3511), run unchanged. It has its own section on this page, and it is never mixed with my numbers. A cut-off answer counts as wrong here, so a value can differ from sparkDash's own screen.
| Test | Result95 % margin | Right | Cut offcount as wrong | Raw files | |
|---|---|---|---|---|---|
| Quality QA 150 questions | 90.0 % ± 4.8 pts | 135 / 150 | 1 | summary | command |
| Quality MMLU 285 questions | 93.3 % ± 2.9 pts | 266 / 285 | 1 | summary | command |
| Tool Eval Quick 15 scenarios, tool use | 90 / 100 | 13 / 15 passed | — | tool eval result · tool eval report · tool eval command · summary | command |
| Decode, 1 request at once first token 270 ms | 50.8 tok/s | — | — | decode result · summary | command |
| Prefill at 4K first token 4.1 s | 1091.4 tok/s | — | — | prefill result · summary | command |
| Prefill at 8K first token 6.9 s | 1248.2 tok/s | — | — | prefill result · summary | command |
| Prefill at 16K first token 13.4 s | 1256.2 tok/s | — | — | prefill result · summary | command |
| Prefill at 32K first token 25.7 s | 1293.8 tok/s | — | — | prefill result · summary | command |
Seed 1234 applies to the two quality tests; decode, prefill and tool eval send no seed. The benchmark client ran on a separate machine that is never part of the measured group. Measured 2026-10-23. Version 2.50.0, commit 21a3511.
QA. Quality QA, 150 items, seed 1234, temperature 0, thinking off, 4 requests at once (Mia's default). An answer cut off at the token limit counts as wrong. ± is the 95 % margin (Wilson).
MMLU. Quality MMLU, 285 items (5 for each of 57 subjects, 4 answers), seed 1234, temperature 0, thinking off. An answer cut off at the token limit counts as wrong. ± is the 95 % margin (Wilson).
Decode. Decode bench, 1 request at once, 400 tokens, prompt type structured, temperature 0, thinking off. No seed is sent.
Prefill. Prefill bench at 4K, 8K, 16K and 32K tokens. sparkDash skips a size that does not fit into the context. No seed is sent.
Tool Eval Quick. Tool Eval Quick: tool-eval-bench (SeraphimSerapis, commit c61319b), 15 core scenarios (--short), --no-think, --timeout 120. Score 0 to 100. No seed is sent.
Note from the run: sparkDash runs its own tests (its own QA and MMLU questions at temperature 0, thinking off, a cut-off answer counts as wrong; 1 of the QA answers and 1 of the MMLU answers were cut off), so its decode and prefill values are not comparable with Speed v2 above. The sparkDash client ran on another machine and was never part of the measured group. A first sparkDash attempt was discarded: its Tool Eval part could not start because the request used a model name the server does not list (the server lists deepseek-v4.1-flash). This page shows the second attempt, which used the listed name and completed all parts; nothing else was changed.
Exact commands we measured withfor reproducing↓
You do not need this to run the model. It is the exact command of our measurement, so anyone can repeat the result.
python3 tools/quality2/sparkdash_client.py tools/quality2/cards/ds41-1017-q2-ds4-kernelpool-72ccf36.json <box> --client <client machine> --job quality-v2-261023-mac-ds4-sparkdash2 --out $RUNtool-eval-bench --base-url http://127.0.0.1:<port> --model deepseek-v4.1-flash --short --no-think --timeout 120 --json-file $BENCH/sparkdash-client/runs/quality-v2-261023-mac-ds4-sparkdash2-sparkdash-r0/tooleval/result.json --no-live