 niklaslenz
Mia's AI Lab recipe: DeepSeek-V4.1-Flash-1017 (TensorFold TP4)
4x NVIDIA DGX Spark class boxes (GB10), tensor parallel 4 over the recipe's own switchless CX7 ring (./start-switchless.sh, no switch, no diagonals): 2x ASUS Ascent GX10, 1x Gigabyte AI TOP ATOM, 1x Lenovo ThinkStation PGX. One box (an ASUS GX10) runs an older driver (580.173.02) and kernel (6.17.0-1031-nvidia) than the other three (580.178.04, 7.0.0-1019-nvidia). That is named openly.

Overall score as of 26 Oct 2026. Scores are relative to the best run in the class today; a better model later moves older runs down.
How the overall score is calculated
| Part | This run | Best in class | Relative | Weight | Points |
|---|---|---|---|---|---|
| Speed, one request | decode 69.9 tok/s | best 81.8 tok/s | 85.4 % | 17.5 % | 14.9 |
| Speed, 8 at once | total 139.0 tok/s | best 141.2 tok/s | 98.4 % | 17.5 % | 17.2 |
| Quality | mean of 7 tests: 65.8 % | best mean 66.7 % | 98.7 % | 25 % | 24.7 |
| Browser check | 8 of 10 | 80.0 % | 5 % | 4.0 | |
| My rating | 8.5 of 10 | 85.0 % | 35 % | 29.8 | |
| Overall | 100 % | 90.6 |
The seven quality tests: MMLU-Pro 65.0 · GPQA 38.9 · IFEval 90.0 · LiveCodeBench 70.0 · long text 8K 62.5 · long text 32K 57.5 · GPQA 30 with thinking 76.7.
The speed part is half the decode speed with one request and half the total speed with 8 requests at once, each relative to the best run of this class; a run without a total for 8 requests at once gets the better of its decode speed alone and the mix with its highest measured total. Quality is relative to the best run of this class, the browser check and my rating are out of 10. The parts are rounded one by one. sparkDash, the memory test and speculative-decoding numbers are not part of it. How the score is made, and the assumption behind it.
What it builds as an agent
Task: Voxel world (3D scene, one HTML file). One attempt, no help. Counted: the final file counts.
The exact promptcopy it and try it yourself↓
This is the task prompt word for word, as we handed it to the agent harness. The harness adds its own system prompt and tools, and some harnesses add short context notes of their own. A run that goes past 90 minutes also gets a short “finish now” message, as the prompt says. To try it yourself, give it to your own coding agent: it needs a shell and a working folder.
Design and create the most impressive, creative, elaborate and detailed
voxel art world you are capable of. The theme and style are ENTIRELY your
choice — pick whatever world you can execute best and push it as far as
you can: scale, variety, detail, color, animation, atmosphere, life.
Surprise me.

Hard requirements:
- Everything ends up in ONE single self-contained HTML file (game.html in
  the current working directory) that opens and runs directly in Chrome.
  Use WebGL and whatever libraries you like, but embed everything —
  no internet access at view time, no external files.
- The scene must present itself: include an automatic slow cinematic
  camera tour (orbiting the world, occasionally zooming in on highlights)
  that starts on load, plus mouse controls (orbit/zoom) for manual viewing.
- All user-facing text (UI, HUD, titles, descriptions, hints) must be in
  ENGLISH, regardless of the language of any project files you encounter.

When finished, verify your HTML actually loads and renders without
console errors, then state DONE with the absolute path of game.html.
Do not ask questions.

How you work (same for every model):
- You work alone in the folder /work (this is the current working directory). Nobody will answer questions. Aim to finish in about 60 minutes. After 90 minutes you will get a message to finish; then you have at most 30 more minutes. Hard stop after 120 minutes.
- Tools on this machine: shell, files, python3 with numpy and Pillow, ffmpeg, node, and `shot.sh game.html` (opens the page in a headless browser, saves a screenshot and prints console errors). There is no internet and no access to other machines.
- Keep a working /work/game.html at all times. If you are stopped, the last version that loaded without errors counts.
- JavaScript libraries available offline in the test browser, through an import map with these exact URLs: "three": "https://cdn.jsdelivr.net/npm/three@0.170.0/build/three.module.js", "three/addons/": "https://cdn.jsdelivr.net/npm/three@0.170.0/examples/jsm/", "simplex-noise": "https://cdn.jsdelivr.net/npm/simplex-noise@4.0.3/dist/esm/simplex-noise.js", "@tweenjs/tween.js": "https://cdn.jsdelivr.net/npm/@tweenjs/tween.js@25.0.0/dist/tween.esm.js", "cannon-es": "https://cdn.jsdelivr.net/npm/cannon-es@0.20.0/dist/cannon-es.js". No other external resources.
- After the scene is built, set `window.scene` to the Three.js scene (if you use Three.js) and `window.ready = true`.
Play it yourself
Open full screenAI-generated The page this setup built, running live in your browser: click into it and use the controls it shows itself (usually drag to look around, scroll to zoom). It needs WebGL and can be slow on a weak graphics card.
The browser check
- page loads without page error1 / 1
- window.ready === true within 30 s1 / 1
- no console errors (whole session)1 / 1
- frame is not blank1 / 1
- frame rate in software GL (rAF over 5 s)0 / 1
- world: scene size 0.5 (parts >= 80 or >= 20000 triangles; canvas fallback), visible text English if any 0.51 / 1
- automatic camera tour: the view changes on its own in two successive ~5 s windows (1 each)2 / 2
- animation in the world (nodes / instances / particles moving besides the camera)1 / 1
- OrbitControls: drag and wheel change the picture beyond the animation baseline0 / 1
Measured 2026-10-26. Raw files: check · run info · command · final choice · contract · sampling · gate stats · gate log · screenshot · clip.mp4 · web.mp4 · web-poster.jpg.
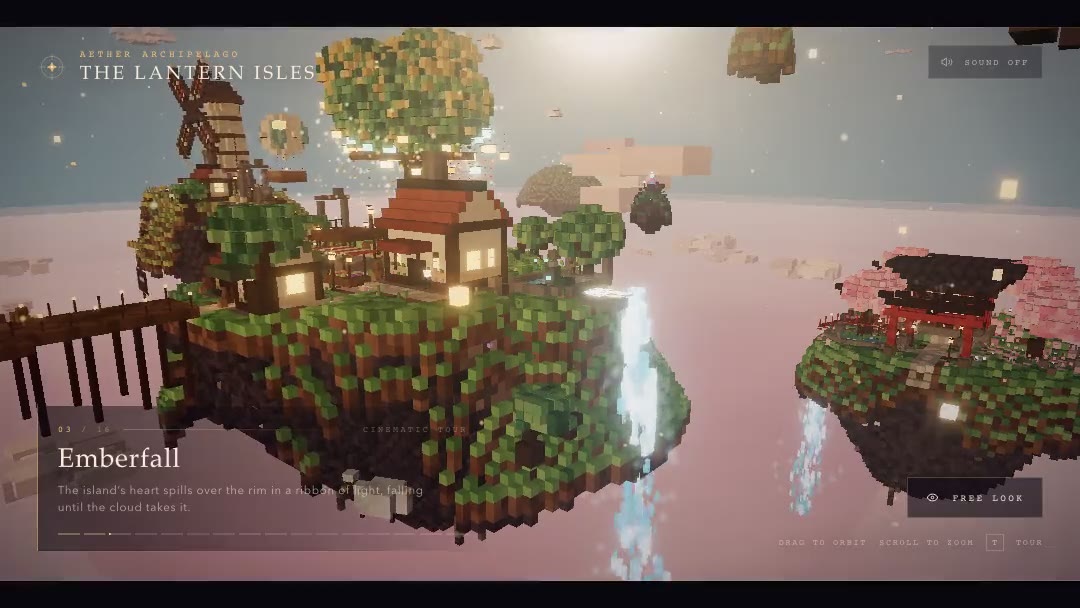
Browser check 8.0 out of 10: the page loads without a page error, is ready after 0.69 s, has no console errors, is not blank, shows a world (72,861 parts, 875,164 triangles, English text), flies the automatic camera tour in both windows and animates (150 animated nodes). The 2 lost points are the frame rate (0.92 frames per second in software rendering without a GPU; 10 give half a point and 20 the full point) and the orbit-controls test (the mouse drag and the mouse wheel changed the picture less than the check needs). The agent (DeepSeek Harness 0.2.1-rc.2, the harness DeepSeek ships) ran 93.5 minutes, one try, no help; the “finish now” message (from 90 minutes) was sent twice, the first time at 91.8 minutes. 52 requests, no error, no request blocked, 50 ended with a tool call and 2 with a normal stop, none at the limit (8,909,238 prompt tokens, 258,931 answer tokens, longest answer 38,742 tokens, largest prompt 321,502 of 1,048,576 tokens). 16 versions of the page were seen on the way and all 16 loaded without errors; the first one came after 38.4 minutes, the first one that was ready after 79.4 minutes, and the last one (after 90.4 minutes) counts. The limit per answer was 262,144 tokens, the value on the DeepSeek model card (README lines 77 to 84); the author's server default is 32,768 tokens and applies only when a request sets none, so I raised the limit for this test (the server setup is unchanged). Thinking was on with the recipe's sampling (temperature 1.0, top_p 1.0, top_k 20), the context was 1,048,576 tokens. The agent ran in a container on one GB10 box of the ring (limited to 1.25 GB of memory and 4 CPU cores), because the Mac could not be used as the host in time. What it built: THE LANTERN ISLES (Aether Archipelago), a voxel world of floating islands with a village, a great lantern tree, a mill, a shrine under falling petals and a crystal hollow, and a cinematic tour of 16 chapters that starts by itself.
Exact command we measured withfor reproducing↓
You do not need this to run the model. It is the exact command of our measurement, so anyone can repeat the result.
run_showcase.sh --harness dsh-021 --task VX --upstream http://127.0.0.1:18080/v1 --model DeepSeek-V4.1-Flash-1017 --sampling-file $RUN/mia-tp4-2510-sw8-show-r1/show.in/sampling-show.json --out $RUN/mia-tp4-2510-sw8-show-r1/show --limit-s 7200 --inject-after-s 5400 --poll-s 20 --ctx 1048576How fast it runs
| Measurement | Result |
|---|---|
| Decode | 69.9 tok/s |
| Words per second | 50.0 words/s |
| Characters per second | 316.6 chars/s |
| Decode, code prompt | 69.5 tok/s |
| Decode, prose prompt | 70.2 tok/s |
| Spread of the decode runs (CV) | 1.9 % |
| Spread of the code runs (CV) | 1.9 % |
| Spread of the prose runs (CV) | 0.1 % |
| Decode, window 1 | 71.1 tok/s |
| Prefill at 2K | 2580.1 tok/s |
| Prefill at 8K | 3460.6 tok/s |
| Prefill at 32K | 3742.5 tok/s |
| Time to first token at 2K | 0.8 s |
| Time to first token at 8K | 2.4 s |
| Time to first token at 32K | 8.8 s |
| Draft acceptance rate | 57.3 % |
| Mean accepted length | 2.3 tokens |
| 1 request at once (total) | 60.5 tok/s |
| 2 at once (total) | 87.3 tok/s |
| 4 at once (total) | 115.9 tok/s |
| 8 at once (total) | 139.0 tok/s |
| 1 request at once (per request) | 60.5 tok/s |
| 2 at once (per request) | 43.9 tok/s |
| 4 at once (per request) | 29.7 tok/s |
| 8 at once (per request) | 17.8 tok/s |
| Server slots (from the recipe) | 16 slots |
| Long answer, wall time | 62.1 s |
Method: code+prose; 2 run(s) each; 512 tokens; 1 warm-up(s); median; requests at once: C1,C2,C4,C8 at once; 2 rounds each; 512 tokens per request; prose prompt; total = all tokens / wall time, per request = tokens / end-to-end time; median over the rounds. Measured 2026-10-26. Raw files: speed result · speed contract · log · long answer.
Requests at once: the server has 16 slots (from the author's recipe). The speed test ran with the author's setup: Mia's AI Lab recipe MiaAI-Lab/DeepSeek-V4.1-Flash-1017-4x-DGX-Sparks-TensorFold at commit 6beaad9 (25 Oct 2026), started with its own ring script (./start-switchless.sh, the switchless mode the README's numbers are measured on), 16 streams (scripts/config.sh line 106), DSpark drafts on, CUDA graphs, side stream and L2 prefetch on, context 1,048,576 tokens, and a KV pool of 16,777,216 positions (README lines 25 to 29; the script default is 2,097,152, config.sh line 105). The eight opt-in switches that the README's patch table marks “on, this cluster” are on (TF_DS_PAIR_SUM, TF_DS_IDX_RB=2, TF_DS_QUARTER_HC, TF_DS_OWNER_GATHER, TF_DS_IDX_SHARD, TF_DS_SAMPLE_CAND, TF_DS_EXPERT_EXIT, TF_DS_PREFILL_YIELD; README lines 326 to 343, five of them also in scripts/local.sh.example lines 12 to 19), because the author's table marks them as on for her cluster; the install prompt on the recipe's page leaves them off. An earlier run of mine with the switches off (the prompt's defaults) is not part of this page and is not mixed in; it gave 65.6 / 87.8 / 114.4 / 134.4 tok/s in total at 1 / 2 / 4 / 8 requests at once and a decode of 71.41 tok/s, against 60.5 / 87.3 / 115.9 / 139.0 and 69.85 tok/s here. Sampling is the server's own and the model card's: temperature 1.0, top_p 1.0, top_k 20 (config.sh lines 116 to 118); thinking is off per request, seed 42, no prompt cache. The headline 69.85 tok/s is the mean of the code prompt (69.53) and the prose prompt (70.17), medians of two runs each (spread 1.9 % and 0.1 %). Drafts were accepted at a rate of 57.3 % (2.27 tokens per round). The recipe runs 16 streams, so 1, 2, 4 and 8 requests at once each get their own stream. The author's own numbers (README lines 78 to 128) come from a different method: prose at temperature 0.7 with thinking on, code greedy, median of three runs; the prompts are not published, measured from the first GB10 box of the ring. They are therefore not comparable with the fixed Speed v2 test. Prefill: the README lists 4,127 tok/s at 32K, this test measured 3,743 tok/s (first token after 8.76 s). All four GB10 boxes run with a GPU clock cap of 2200 MHz (the default application clock of the GB10 is 2418 MHz); the cap has been set on these boxes since 2 Oct 2026 and the speed test ran with it on. I lifted it only for a separate one-off prefill test afterwards (not part of this page) and put it back. Prefill is compute-bound and follows the clock. The ring: the link check before the run measured all eight links at 109 Gb/s. One of the four GB10 boxes (an ASUS GX10) runs an older driver (580.173.02) and kernel (6.17.0-1031) than the other three (580.178.04, 7.0.0-1019). The quiet check before and after the speed test found no foreign process (highest foreign load 3.4 % of one core, the kernel's memory reclaim thread).
Exact command we measured withfor reproducing↓
You do not need this to run the model. It is the exact command of our measurement, so anyone can repeat the result.
python3 speed2.py --base-url http://127.0.0.1:41833/v1 --label mia-tp4-2510-sw8-speed-r0 --prompts $BENCH/repos/rigmark-v2/prompts-v2.json --output $RUN/mia-tp4-2510-sw8-speed-r0/mia-tp4-2510-sw8-speed-r0/speed2 --contract $RUN/mia-tp4-2510-sw8-speed-r0/mia-tp4-2510-sw8-speed-r0/speed2/speed-contract.json --parts decode,prefill,conc,l1 --prefill-depths 2048,8192,32768 --prompt-ids code,prose --runs 2 --max-tokens 512 --warmups 1 --prefill-runs 3 --conc-levels 1,2,4,8 --conc-rounds 2 --conc-max-tokens 512 --conc-prompt prose --tokenizer-json $HOME/hf-tp4-2510/hub/models--deepseek-ai--DeepSeek-V4.1-Flash-1017/snapshots/1bae0e1088993b9b82de08f59de5be5a34e42170/tokenizer.json --tokenizer-python $HOME/not published --sampling {"temperature": 1.0, "top_p": 1.0, "top_k": 20} --sampling-source The author's server defaults: scripts/config.sh:116-118 (TEMPERATURE 1.0, TOP_P 1.0, TOP_K 20); equal to the model card (README.md:77-84: temperature 1.0, top_p 1.0); a request's own values win. Speed v2 runs thinking off (enable_thinking false per request), show/think thinking on (REASONING_EFFORT max is the server default, config.sh:112). --model DeepSeek-V4.1-Flash-1017 --no-cache-prompt --server-log $RUN/server-A.log --engine-version-file $RUN/engine-version.txt --server-slots 16 --server-slots-source MiaAI-Lab/DeepSeek-V4.1-Flash-1017-4x-DGX-Sparks-TensorFold@6beaad9 scripts/config.sh:106 (PARALLEL=16), start.sh:116 (TF_DS_STREAMS=$PARALLEL), README.md:298How well it answers
| Test | Result95 % margin | Right | Cut offcount as wrong | Raw files | |
|---|---|---|---|---|---|
| MMLU-Pro 400 fixed questions, letter only | 65.0 % ± 4.7 pts | 260 / 400 | 60 | summary · log · contract | command |
| GPQA Diamond 198 questions, letter only | 38.9 % ± 6.7 pts | 77 / 198 | 59 | answers · summary · log · contract | command |
| IFEval 200 fixed prompts, strict | 90.0 % ± 4.2 pts | 180 / 200 | 0 | answers · summary · log · contract | command |
| LiveCodeBench 40 newest tasks, the code runs | 70.0 % ± 13.7 pts | 28 / 40 | 0 | summary · log · contract | command |
| Long text 8K 4 tasks x 10 at 8192 tokens | 62.5 % ± 14.4 pts | 25 / 40 | 5 | log · contract · answers · summary | command |
| Long text 32K 4 tasks x 10 at 32768 tokens | 57.5 % ± 14.7 pts | 23 / 40 | 0 | log · contract · answers · summary | command |
| GPQA 30, thinking on 30 questions, limit 16,384 tokens | 76.7 % ± 14.6 pts median 5,459 tokens, 506.3 s per question | 23 / 30 | 6 | log · contract · summary | command |
Thinking off, except the last test. Seed 42. Sampling from the model card. A cut-off answer counts as wrong. Measured 2026-10-26.
Note from the run: Quality ran on this card in several blocks on 26 Oct 2026 (the multiple-choice, LiveCodeBench and long-text tests together, the thinking test alone). The questions ran 16 at a time, the recipe's stream count (same questions, limits and seed 42 for every question); the median time per question of the thinking test (506.3 s) was measured under that load. MMLU-Pro and GPQA Diamond ran with an answer limit of 48 tokens (the fixed method asks for the letter only), IFEval with 4,096, LiveCodeBench with 32,768, the long-text tests with 128 tokens. With thinking off the model often starts to explain step by step instead of giving the letter: 60 of the 400 MMLU-Pro answers and 59 of the 198 GPQA Diamond answers were cut off at the 48-token limit and count as wrong, as the method says, so both scores are lower than for a model that answers with the letter first. 5 of the 40 long-text answers at 8K were cut off at their limit of 128 tokens and count as wrong too; none of the 40 LiveCodeBench or 200 IFEval answers was cut off. GPQA Diamond ran from the public mirror fingertap/GPQA-Diamond (198 questions), because the original is gated. Sampling is the server's own and the model card's: temperature 1.0, top_p 1.0, top_k 20 in every test. Thinking was off in all tests except GPQA with thinking (30 questions, limit 16,384 tokens, 6 of the 30 answers ran into the limit and count as wrong). These are my own tests; no other run is mixed into the quality numbers on this page.
Exact commands we measured withfor reproducing↓
You do not need this to run the model. It is the exact command of our measurement, so anyone can repeat the result.
bash tools/quality2/measure_all.sh tools/quality2/cards/ds1017-mia-fp8-mxfp4-tp4-4x-6beaad9-vx.json --parts mmlupro --job mia-tp4-2510-sw8bash tools/quality2/measure_all.sh tools/quality2/cards/ds1017-mia-fp8-mxfp4-tp4-4x-6beaad9-vx.json --parts gpqa --job mia-tp4-2510-sw8bash tools/quality2/measure_all.sh tools/quality2/cards/ds1017-mia-fp8-mxfp4-tp4-4x-6beaad9-vx.json --parts ifeval --job mia-tp4-2510-sw8bash tools/quality2/measure_all.sh tools/quality2/cards/ds1017-mia-fp8-mxfp4-tp4-4x-6beaad9-vx.json --parts lcb --job mia-tp4-2510-sw8bash tools/quality2/measure_all.sh tools/quality2/cards/ds1017-mia-fp8-mxfp4-tp4-4x-6beaad9-vx.json --parts ruler --job mia-tp4-2510-sw8bash tools/quality2/measure_all.sh tools/quality2/cards/ds1017-mia-fp8-mxfp4-tp4-4x-6beaad9-vx.json --parts ruler --job mia-tp4-2510-sw8bash tools/quality2/measure_all.sh tools/quality2/cards/ds1017-mia-fp8-mxfp4-tp4-4x-6beaad9-vx.json --parts think --job mia-tp4-2510-sw8How much context fits
| Context size | Prompttokens | Filled | First token | Prefilltok/s, as the server reports it | Decodetok/s | Peak memoryGiB | Result |
|---|---|---|---|---|---|---|---|
| 4K 4,096 tokens | 3,891 | 95.0 % | — | — | — | 102.58 | answered (stop) |
| 8K 8,192 tokens | 7,782 | 95.0 % | — | — | — | 102.62 | answered (stop) |
| 16K 16,384 tokens | 15,564 | 95.0 % | — | — | — | 102.77 | answered (length) |
| 32K 32,768 tokens | 31,130 | 95.0 % | — | — | — | 102.92 | answered (length) |
| 64K 65,536 tokens | 62,259 | 95.0 % | — | — | — | 102.91 | answered (stop) |
| 128K 131,072 tokens | 124,518 | 95.0 % | — | — | — | 101.31 | answered (stop) |
Memory test. The recipe fixes the context (1,048,576 tokens), so the server is started once with the recipe's own command and reserves its memory up front. Then, for each size (4K, 8K, 16K ... up to the largest size tested), one prompt that fills about 95 % of that size is sent, and the model must answer. The largest size that answered counts; it is the highest size tested, not a limit of the setup. Decode speed at that size was not measured. Peak memory is, on each of the four boxes, the rise of used memory (MemTotal - MemAvailable) over the idle value before the step; the table and the number show the highest of the four boxes. Unified memory, so GPU and CPU share it. Measured 2026-10-26. Raw files: result of every step · log · contract.
Note from the run: fit memory per node, highest rise over idle: box-3 102.9 GiB, box-4 99.1 GiB, box-1 98.0 GiB, box-2 98.3 GiB The recipe fixes the context (1,048,576 tokens, config.sh line 104): the server was started once with the author's setting, then a prompt of about 95 % of each size from 4K up to 128K (131,072 tokens) was sent, and the model answered at every size. 128K is the largest size tested, not the largest size the setup can load. Decode speed at these sizes is not measured. The memory number is the rise of used memory over the idle value, so it includes the model weights; the numbers per GB10 box are in the remark of the measurement, the number shown is the highest of the four. The headline number is the peak of the largest step (128K, 101.31 GiB); the highest single step was 102.92 GiB at 32K.
Exact command we measured withfor reproducing↓
You do not need this to run the model. It is the exact command of our measurement, so anyone can repeat the result.
bash tools/quality2/measure_all.sh tools/quality2/cards/ds1017-mia-fp8-mxfp4-tp4-4x-6beaad9-vx.json --parts fit --job mia-tp4-2510-sw8Also made this possible
- Model
 DeepSeekHugging Face @deepseek_ai GitHub Website
- TensorFold fork with DeepSeek-V4.1 support (engine 5940208) and the TP4 kit (6033ea4)
 bertholomus@bertholomusai GitHub Hugging Face
- Engine (TensorFold)
 Ash Hart@ashxhart GitHub Hugging Face Website
Run it yourself
What you need and how to start it, step by step. The results below come from exactly this setup.
What you need
- Hardware
- 4x NVIDIA DGX Spark class boxes (GB10), tensor parallel 4 over the recipe's own switchless CX7 ring (./start-switchless.sh, no switch, no diagonals): 2x ASUS Ascent GX10, 1x Gigabyte AI TOP ATOM, 1x Lenovo ThinkStation PGX. One box (an ASUS GX10) runs an older driver (580.173.02) and kernel (6.17.0-1031-nvidia) than the other three (580.178.04, 7.0.0-1019-nvidia). That is named openly.
- Model
- deepseek-ai DeepSeek-V4.1-Flash-1017 (rev 1bae0e10, FP8 + MXFP4 as published) + checkpoint DSpark drafts
- Engine
- TensorFold, tensor parallel on 4 GB10 boxes (switchless ring), the official FP8/MXFP4 checkpoint with DSpark drafts, 1,048,576 tokens of context, 16 streams — the program that loads the model and answers requests · github.com/ashhart/TensorFold
- Recipe (TensorFold TP4 on 4 DGX Sparks), patches 0001 to 0025
- github.com/MiaAI-Lab/DeepSeek-V4.1-Flash-1017-4x-DGX-Sparks-TensorFold by Mia's AI Lab
Steps
Get the recipe and the engine from the list above. The list has no direct download link for the model file itself. The base model is huggingface.co/deepseek-ai/DeepSeek-V4.1-Flash-1017.
Start the server with this command. It loads the model into memory.
cd mia-tp4-2510/repo && ./start-switchless.sh (via spark-4x-ds1017-mia-ring.sh start); rank order box-3=0 box-4=1 box-1=2 box-2=3
Exact command we measured withfor reproducing↓
You do not need this to run the model. It is the start text exactly as our run recorded it, with the engine build in front, so anyone can repeat the result.
TensorFold native (Zig 0.17.0) bertholomus fork 5940208 + Mia's AI Lab patches 0001-0025, TP=4 2D split (parity), DSpark drafts, switchless ring (ORDER auto 0,1,3,2), kit 6033ea4; cd mia-tp4-2510/repo && ./start-switchless.sh (via spark-4x-ds1017-mia-ring.sh start); rank order box-3=0 box-4=1 box-1=2 box-2=3Context and sampling: 1,048,576 tokens (the recipe's CONTEXT, config.sh line 104, and the model window), a KV pool of 16,777,216 positions shared by 16 streams (POOL, README lines 25 to 29; the script default is 2,097,152), seed 42, no prompt cache. Sampling as the recipe's server and the model card: temperature 1.0, top_p 1.0, top_k 20, the same with thinking on and off. All eight TF_DS switches that the README's table marks “on, this cluster” are on (README lines 326 to 343); the recipe page's install prompt keeps them off. The engine image was built here from the same pinned sources as prepare.sh uses (TensorFold fork commit 5940208 with the 25 patches, kit 6033ea4, Zig 0.17.0 with its checksum checked, PyAV 18.1.0 copied from an installed wheel) because the internet on my GB10 boxes ran at about 60 KB/s while I set up; the sources are the same, only the way they came to the box differs. GPU clock cap 2200 MHz on all four GB10 boxes (default application clock 2418 MHz). The author's server default for one answer is 32,768 tokens (config.sh line 108); my requests set 262,144, the limit the model card names (named on this page). Agent for the build test: DeepSeek Harness 0.2.1-rc.2, headless, running in a container on one GB10 box of the measured set (limited to 1.25 GB of memory and 4 CPU cores).. Hardware: 4x NVIDIA DGX Spark class boxes (GB10), tensor parallel 4 over the recipe's own switchless CX7 ring (./start-switchless.sh, no switch, no diagonals): 2x ASUS Ascent GX10, 1x Gigabyte AI TOP ATOM, 1x Lenovo ThinkStation PGX. One box (an ASUS GX10) runs an older driver (580.173.02) and kernel (6.17.0-1031-nvidia) than the other three (580.178.04, 7.0.0-1019-nvidia). That is named openly.. All raw files of this setup: raw/v2/deepseek-v41-flash-4sparks-mia-tp4-1017.
Mia's own benchmark, run unchanged
This is Mia's own benchmark tool (commit 21a3511), run unchanged. It has its own section on this page, and it is never mixed with my numbers. A cut-off answer counts as wrong here, so a value can differ from sparkDash's own screen.
| Test | Result95 % margin | Right | Cut offcount as wrong | Raw files | |
|---|---|---|---|---|---|
| Quality QA 150 questions | 90.0 % ± 4.8 pts | 135 / 150 | 5 | summary | command |
| Quality MMLU 285 questions | 94.0 % ± 2.8 pts | 268 / 285 | 0 | summary | command |
| Tool Eval Quick 15 scenarios, tool use | 90 / 100 | 13 / 15 passed | — | tool eval result · tool eval report · tool eval command · summary | command |
| Decode, 1 request at once first token 113 ms | 159.1 tok/s | — | — | decode result · summary | command |
| Prefill at 4K first token 1.3 s | 3528.0 tok/s | — | — | prefill result · summary | command |
| Prefill at 8K first token 2.3 s | 3917.3 tok/s | — | — | prefill result · summary | command |
| Prefill at 16K first token 4.2 s | 4103.3 tok/s | — | — | prefill result · summary | command |
| Prefill at 32K first token 8.1 s | 4133.8 tok/s | — | — | prefill result · summary | command |
Seed 1234 applies to the two quality tests; decode, prefill and tool eval send no seed. The benchmark client ran on a separate machine that is never part of the measured group. Measured 2026-10-26. Version 2.50.0, commit 21a3511.
QA. Quality QA, 150 items, seed 1234, temperature 0, thinking off, 4 requests at once (Mia's default). An answer cut off at the token limit counts as wrong. ± is the 95 % margin (Wilson).
MMLU. Quality MMLU, 285 items (5 for each of 57 subjects, 4 answers), seed 1234, temperature 0, thinking off. An answer cut off at the token limit counts as wrong. ± is the 95 % margin (Wilson).
Decode. Decode bench, 1 request at once, 400 tokens, prompt type structured, temperature 0, thinking off. No seed is sent.
Prefill. Prefill bench at 4K, 8K, 16K and 32K tokens. sparkDash skips a size that does not fit into the context. No seed is sent.
Tool Eval Quick. Tool Eval Quick: tool-eval-bench (SeraphimSerapis, commit c61319b), 15 core scenarios (--short), --no-think, --timeout 120. Score 0 to 100. No seed is sent.
Note from the run: sparkDash runs its own tests (its own QA and MMLU questions at temperature 0, thinking off, a cut-off answer counts as wrong; 5 of the 150 QA answers were cut off), so its decode and prefill values are not comparable with Speed v2 above: its decode test sends a structured prompt for 400 tokens, one request at a time, Speed v2 a code and a prose prompt. Speed v2 and Quality v2 stay in their own columns; no sparkDash number is mixed into them or into the ranking. The sparkDash client ran on another machine and was never part of the measured group.
Exact commands we measured withfor reproducing↓
You do not need this to run the model. It is the exact command of our measurement, so anyone can repeat the result.
python3 tools/quality2/sparkdash_client.py tools/quality2/cards/ds1017-mia-fp8-mxfp4-tp4-4x-6beaad9-vx.json <box> --client <client machine> --job mia-tp4-2510-sw8-sd --out $RUNtool-eval-bench --base-url http://127.0.0.1:<port> --model DeepSeek-V4.1-Flash-1017 --short --no-think --timeout 120 --json-file $BENCH/sparkdash-client/runs/mia-tp4-2510-sw8-sd-sparkdash-r0/tooleval/result.json --no-live