 niklaslenz
Qwen-Image 2.1 Turbo (NVFP4) on a DGX Spark
Twenty 1024×1024 images at 8 steps with the NVFP4 files of Qwen-Image-2.1-Turbo in ComfyUI on one DGX Spark, measured twice from a fresh start.


Not ranked. Measured on this device only. Measured before the image test v2 protocol of 20 Oct 2026; shown separately and not ranked.
DGX Spark 128 GB · NVFP4 · 1024×1024 · 8 steps
one NVIDIA DGX Spark (GB10, 128 GB unified memory)
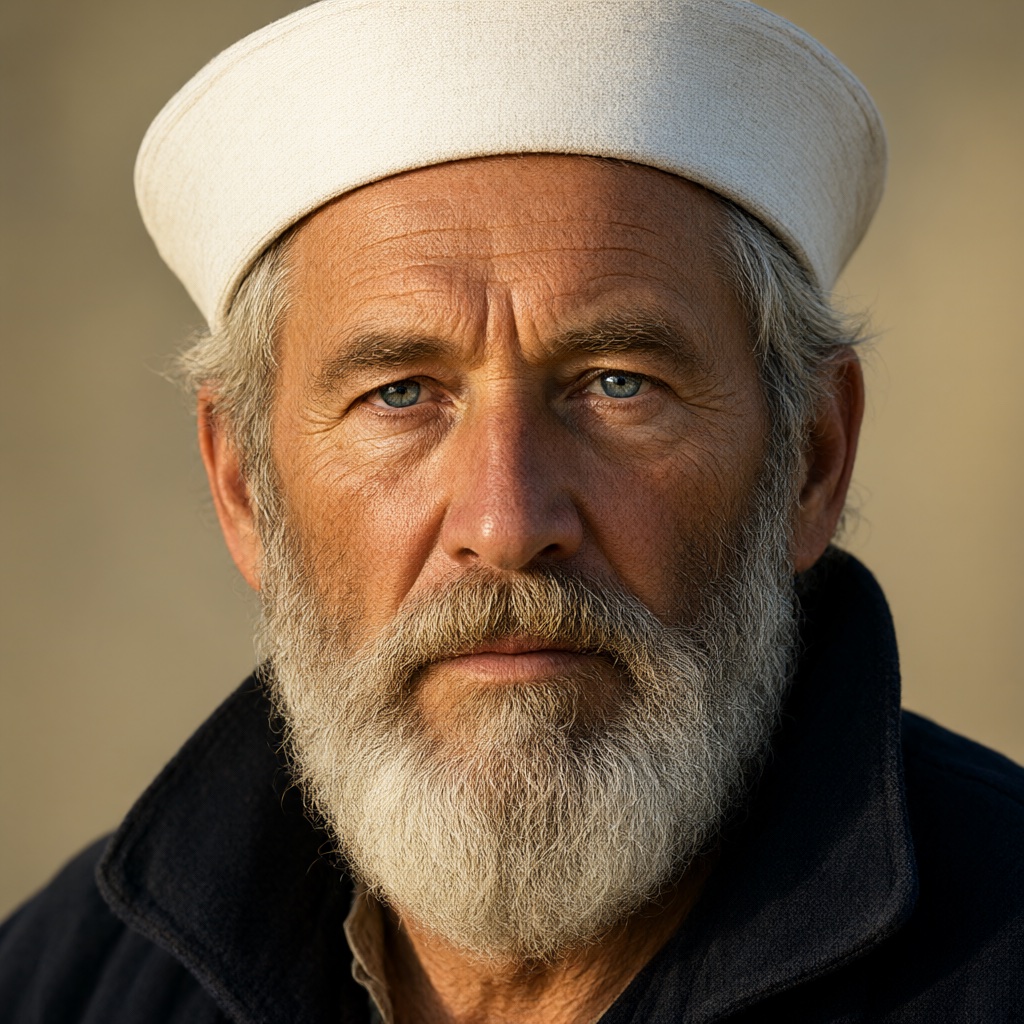
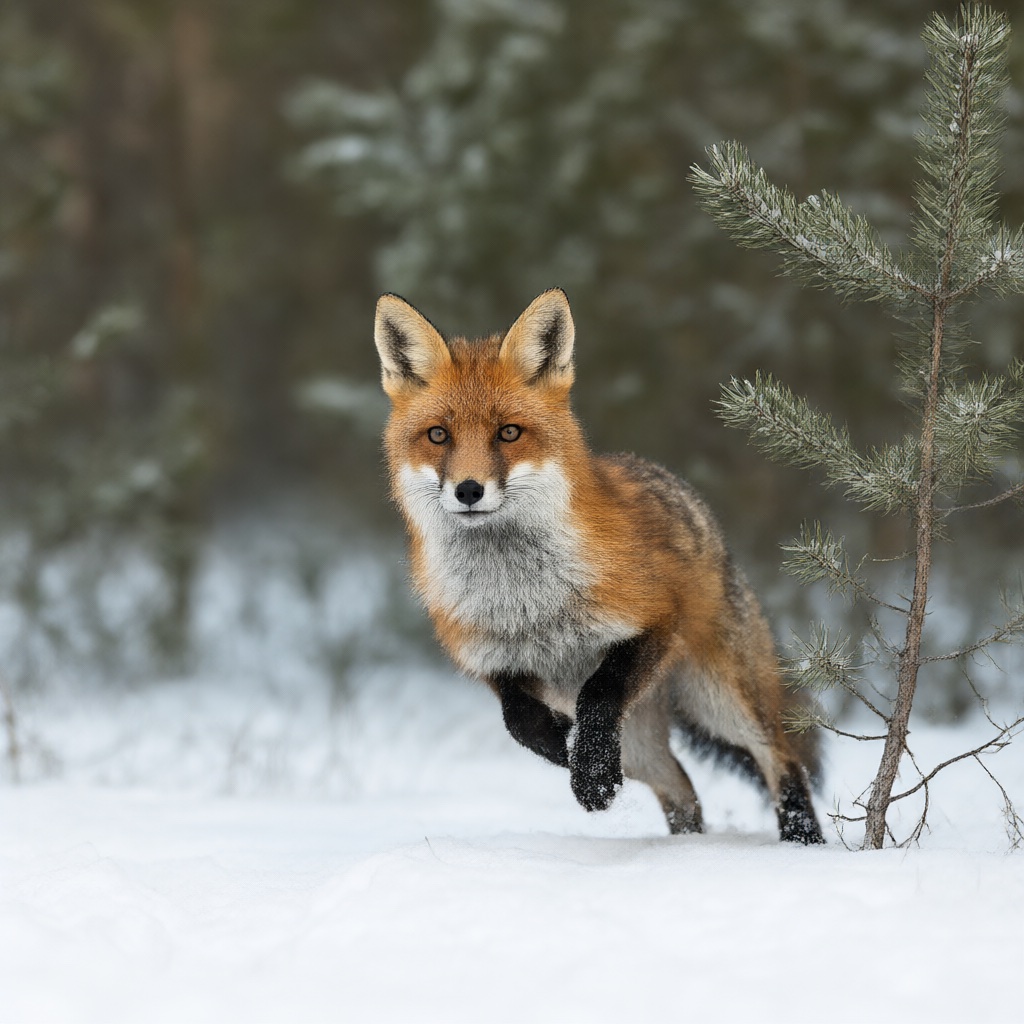
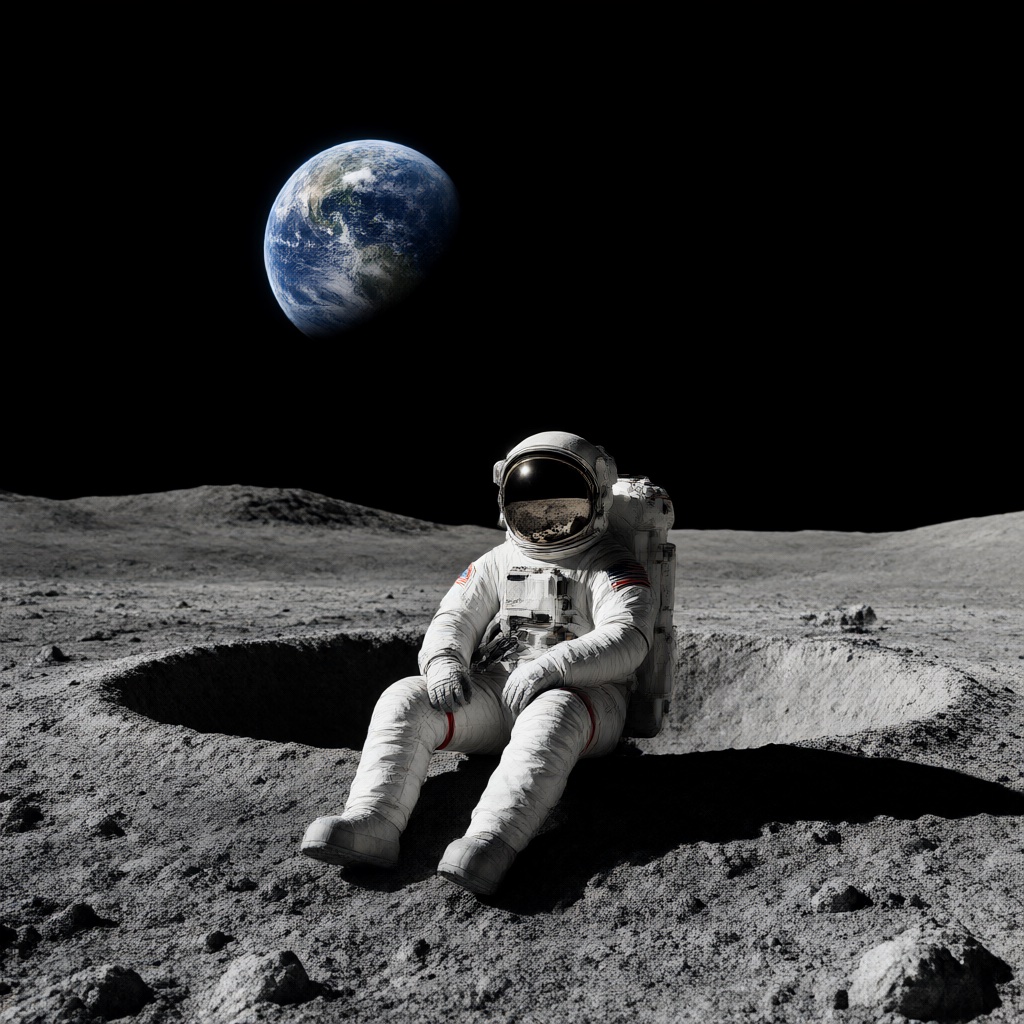
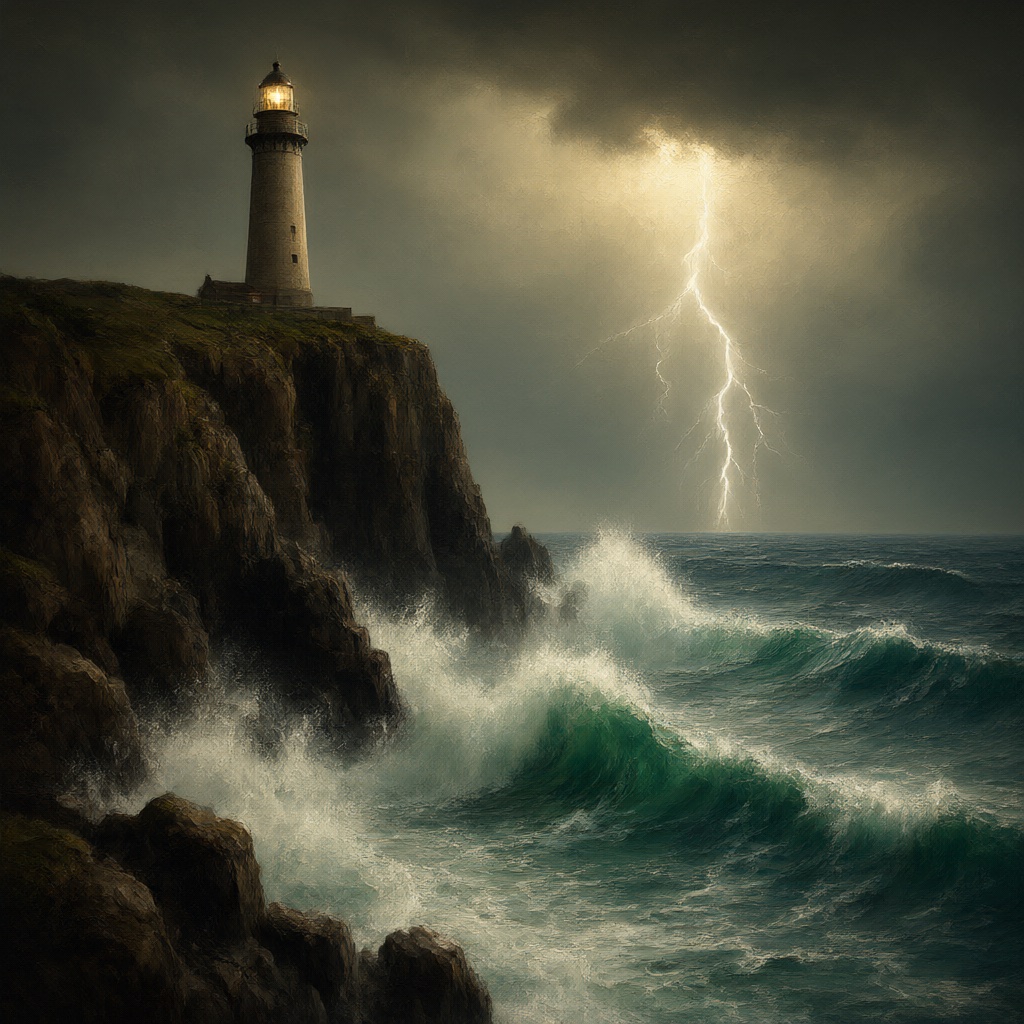
Real outputs
How it was run
- Files: BennyDaBall/Qwen-Image-2.1-Turbo-NVFP4 at revision cb5a4e68 (NVFP4 transformer 5.69 GB, NVFP4 text encoder 9.33 GB, bf16 VAE 0.68 GB); sha256 of all three files equals the Hugging Face API values on every device
- Engine: ComfyUI 0.39.0, commit 46493d82, official NGC PyTorch 26.07 container, comfy-kitchen 0.2.37; NVFP4 runs natively, no fallback message in the log
- Flags: --disable-api-nodes --disable-all-custom-nodes; no SageAttention, no --cache-none
- Workflow: 1024×1024, 8 steps, Euler, the saved Turbo sigma plan, CFG 1; one image per job
- Method: 1 warm-up image (seed 999) dropped, then 20 prompts queued at once with seeds 1001 to 1020; time per image = difference of consecutive server completion timestamps, median of the 19 intervals after image 1; includes text encoding, VAE decode and PNG save
- Each run started from a freshly started container (no cache hits: each log shows exactly 21 prompts); two runs per device
What to keep in mind
Measured on this device only, not ranked.
One GB10 was measured. The two runs show the spread between runs on this machine, not between two GB10 boxes.
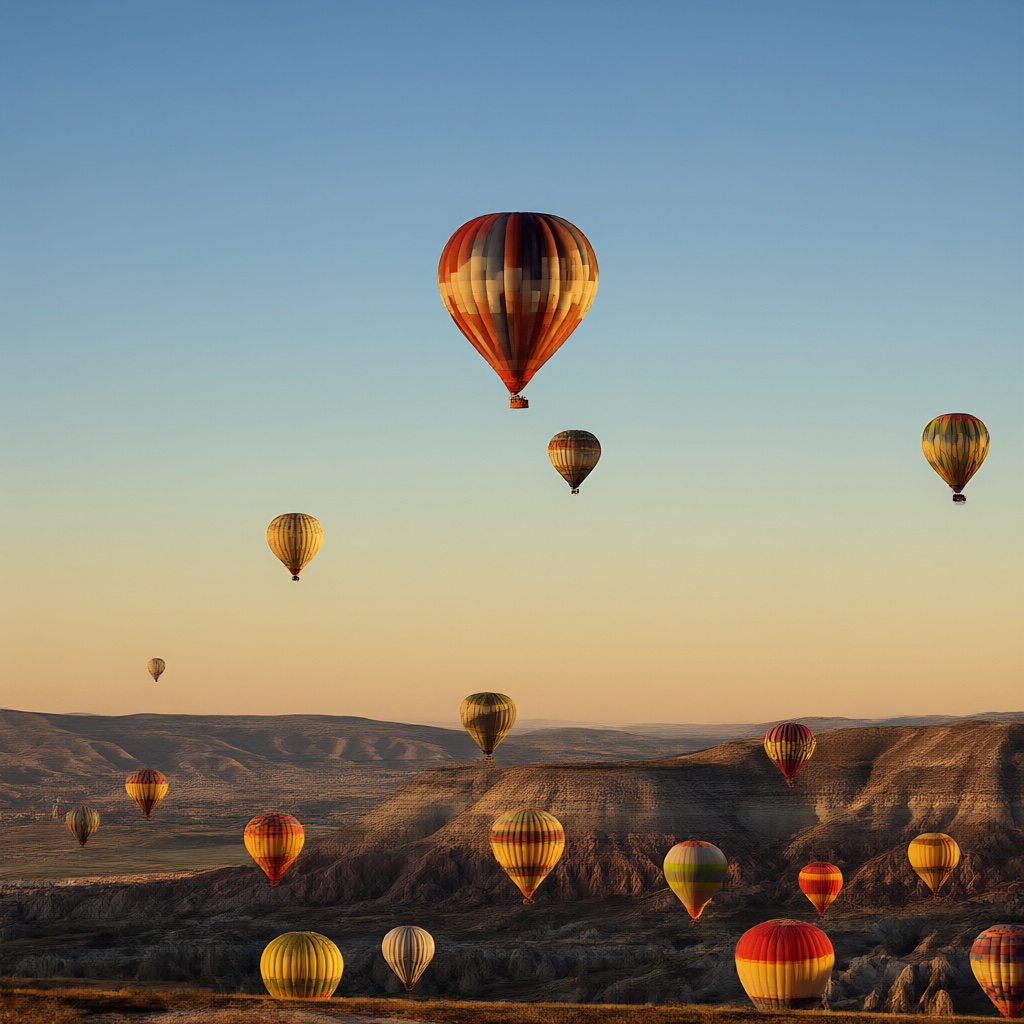
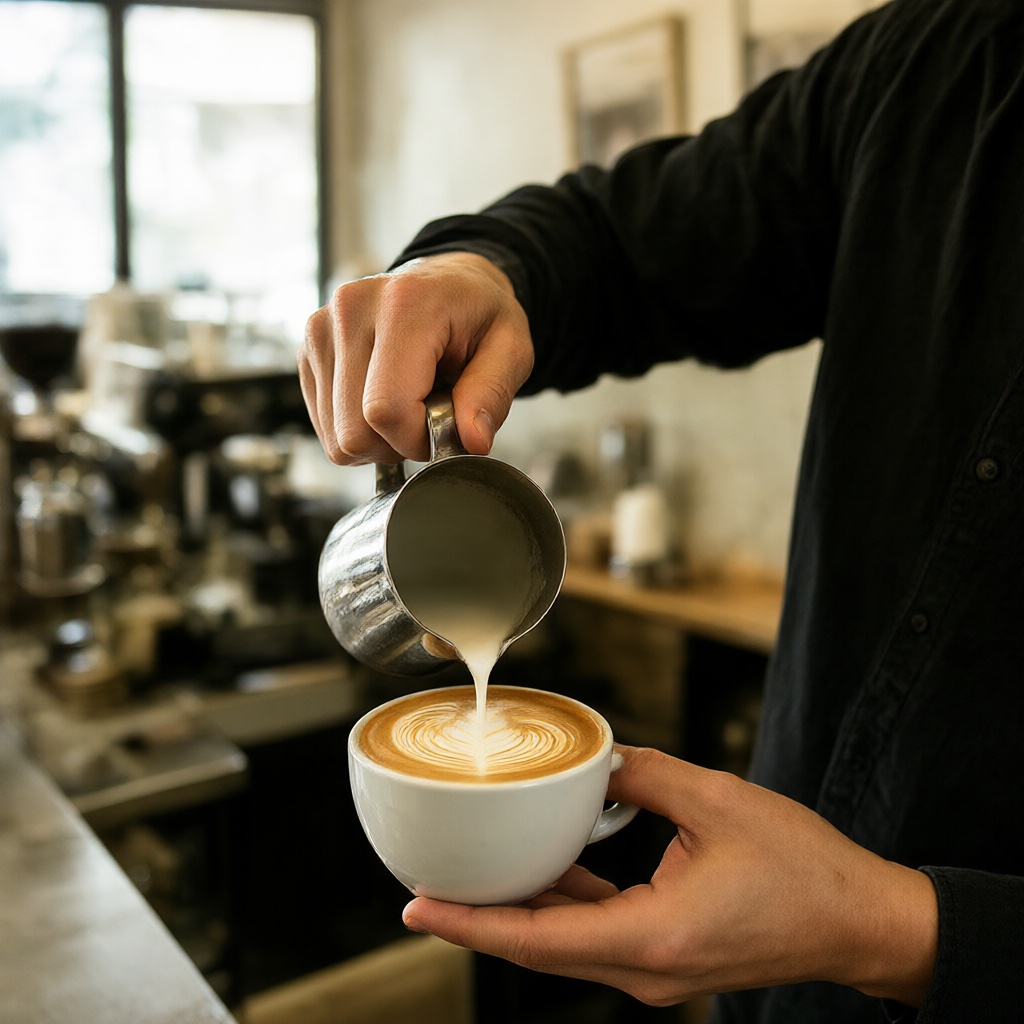
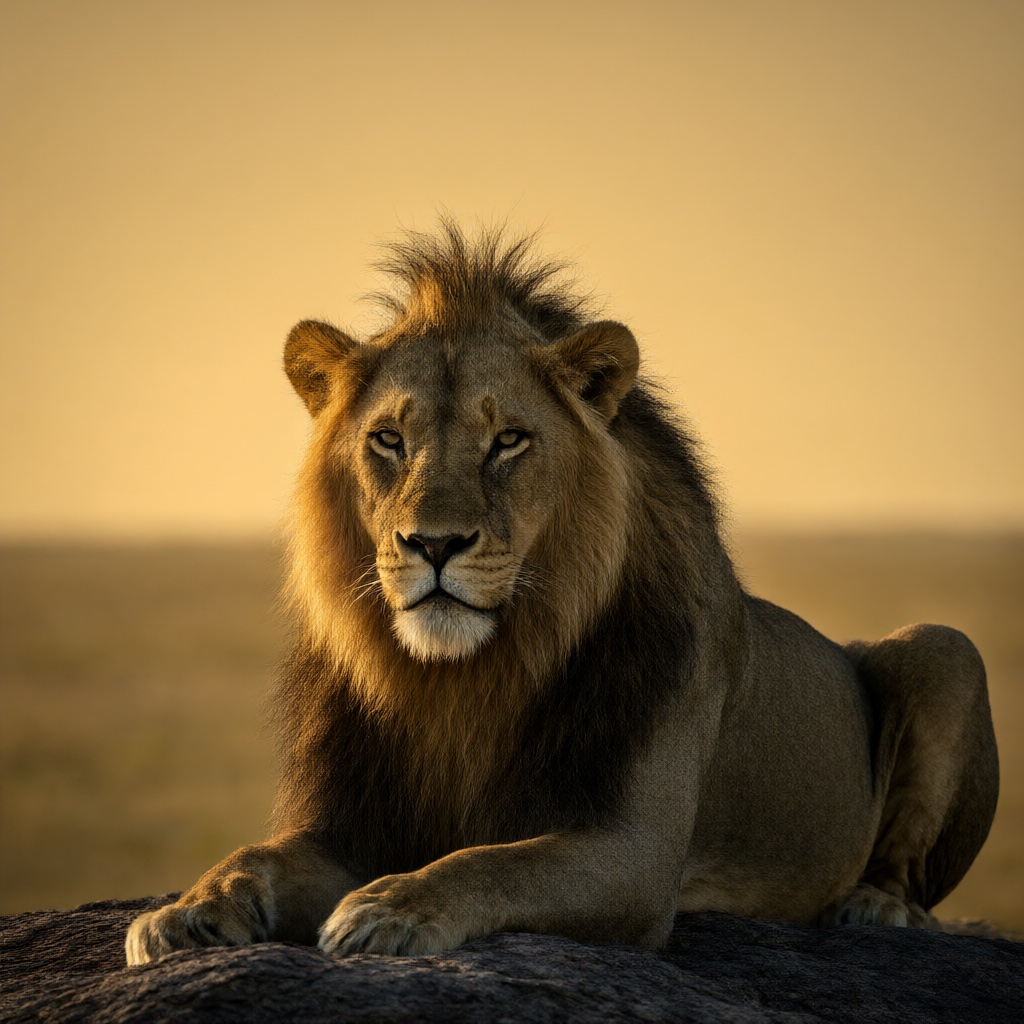
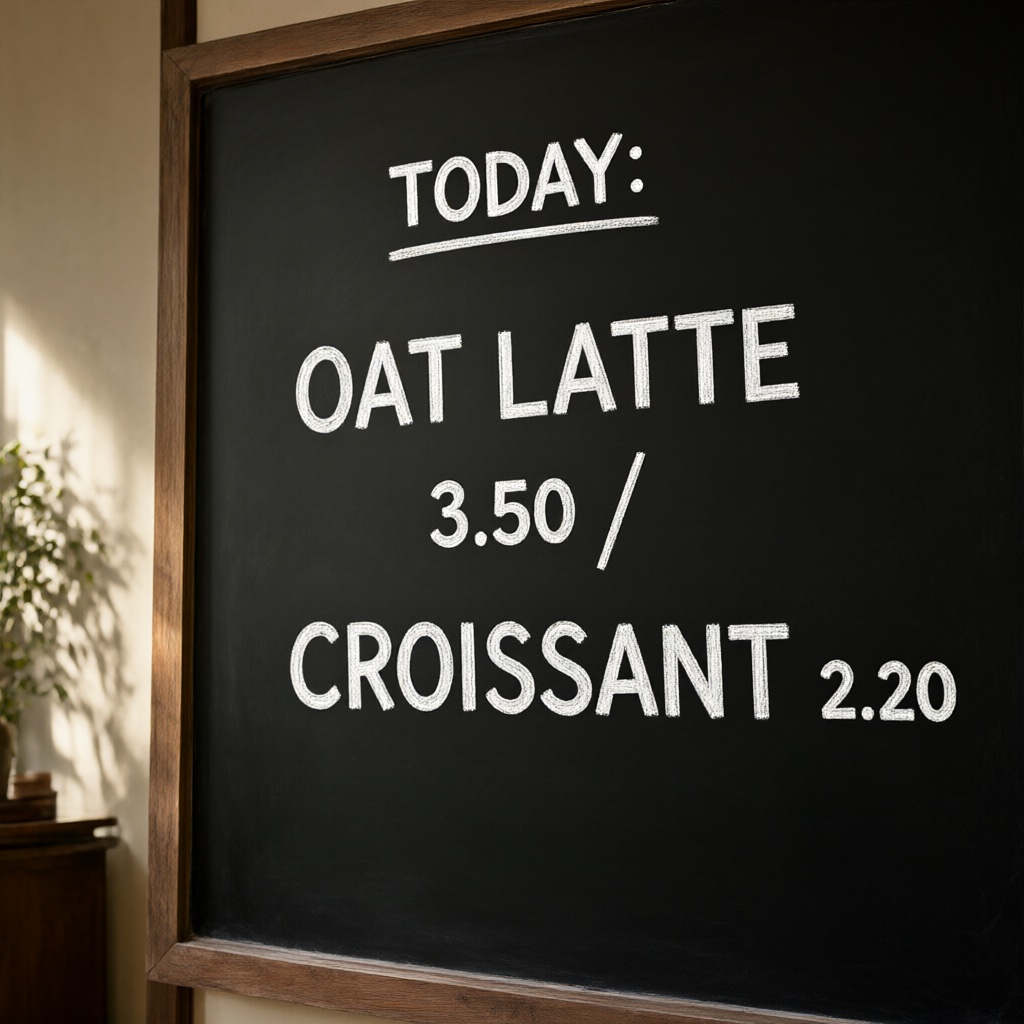
The images come from run 1. Run 2 produced pixel-identical images. Images are the model's raw output, no retouching. Image 1 (fire breather, not shown) has a cropped dark figure at the right edge on this device; image 10 (balloons) shows slightly blocky patterns, probably a quantization trait that was not isolated. Visual impression only, no quality metric.
The machine ran with its standard GPU clock cap (value not published here). A dashboard container was running idle on the machine, without GPU use.
Only the transformer uses NVFP4 matrix multiplication; the text encoder runs on the full-precision path.
The ComfyUI log shows a harmless error block at start (the GUI workflow templates package is not installed) and a deprecation warning for --disable-api-nodes; neither affects the run.
The model weights come under the Qwen research license (Hugging Face license field "other", name qwen-research); read the model page before commercial use.