 niklaslenz
Qwen-Image-2.1 on Mac Studio M5 Ultra 256 GB
Mac Studio M5 Ultra 256 GB

2 of 2 · overall 40 of 100, as of 20 Oct 2026
Speed 32.5 of 100 (25 %) · my ratings 42.5 of 100 (75 %). Speed is the mean of the two medians: up to 10 s per image it counts 100, above that 1000 divided by the seconds; my ratings are the mean of my 8 ratings, minus 5, times 20. All image setups on 256 GB Mac.
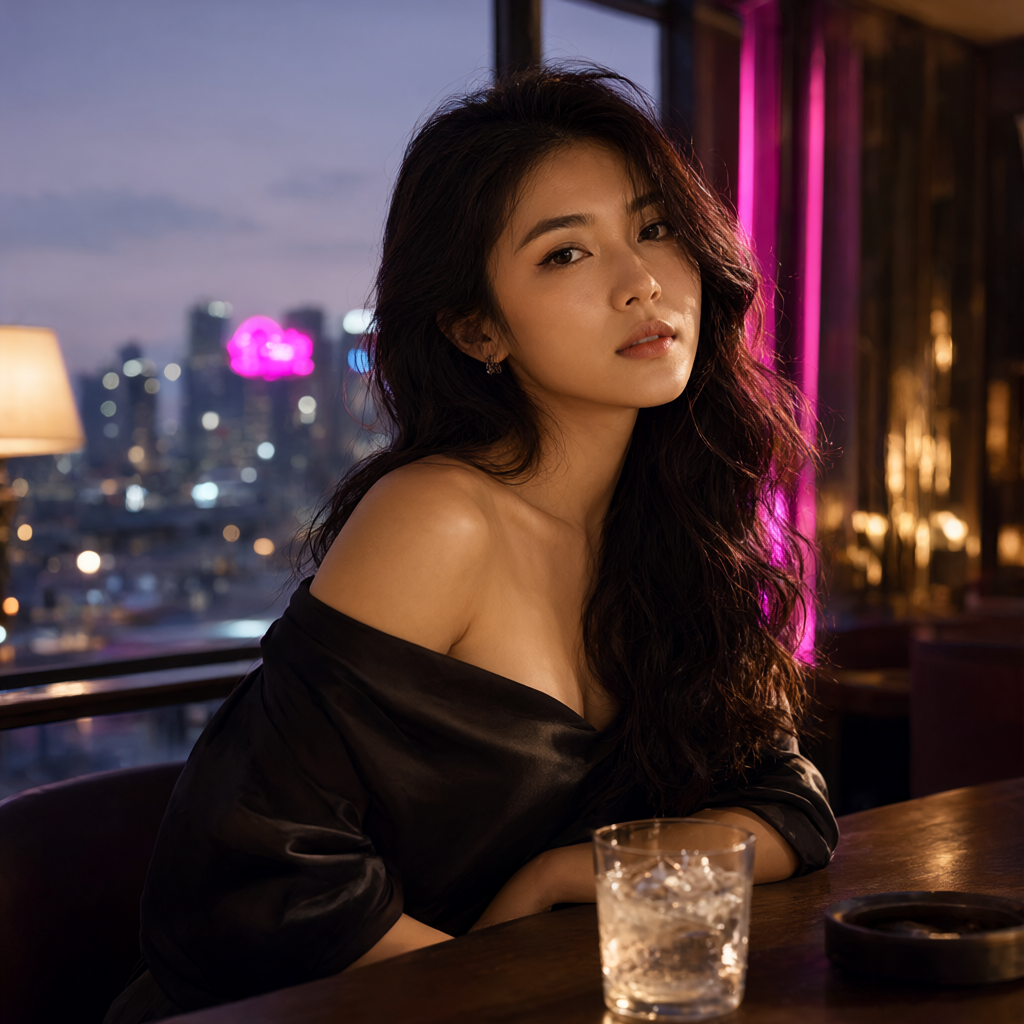
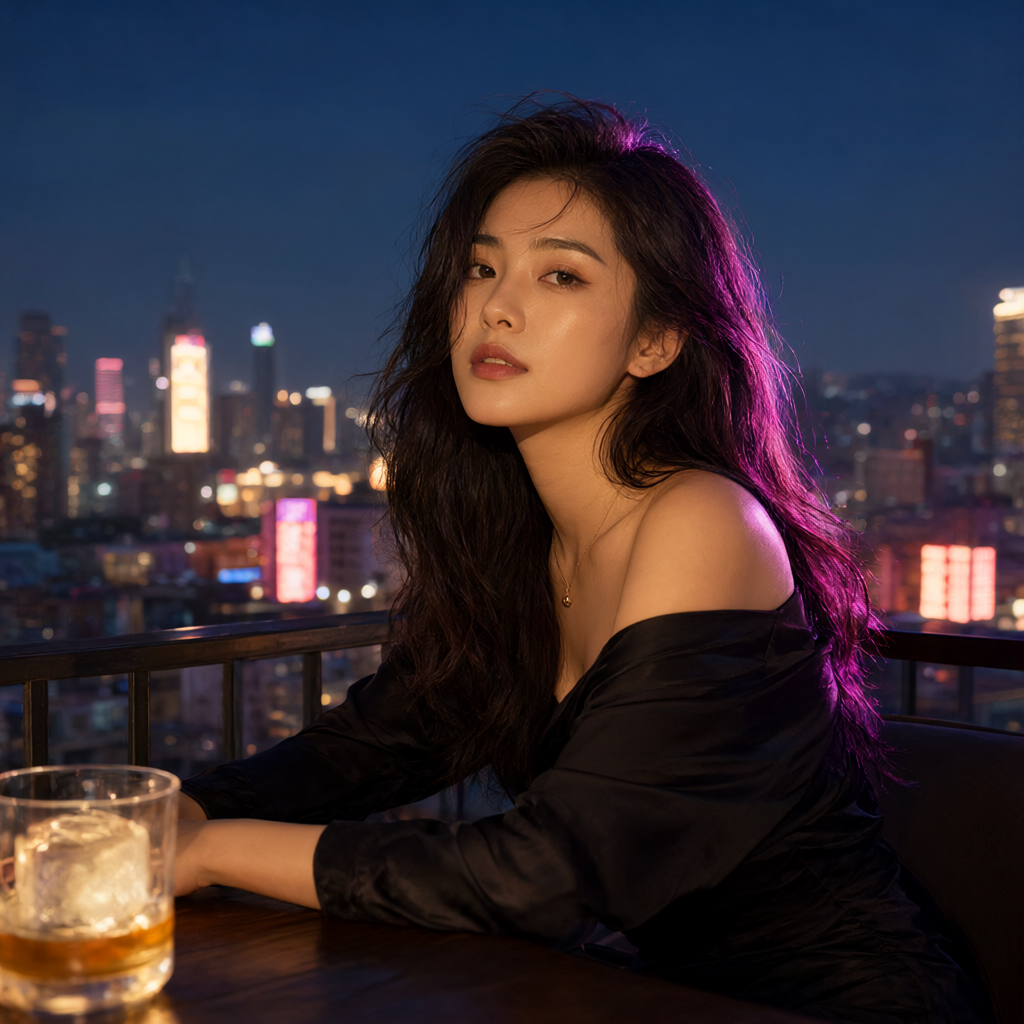
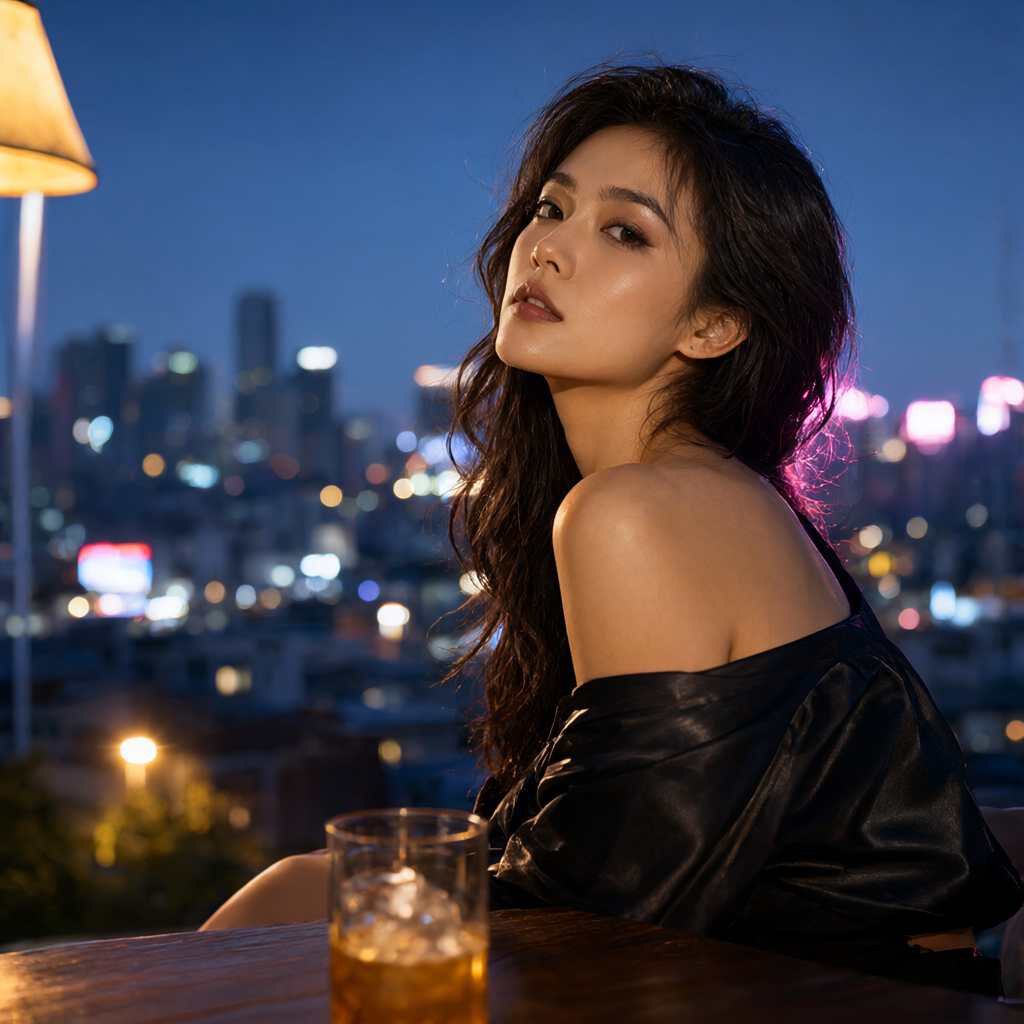
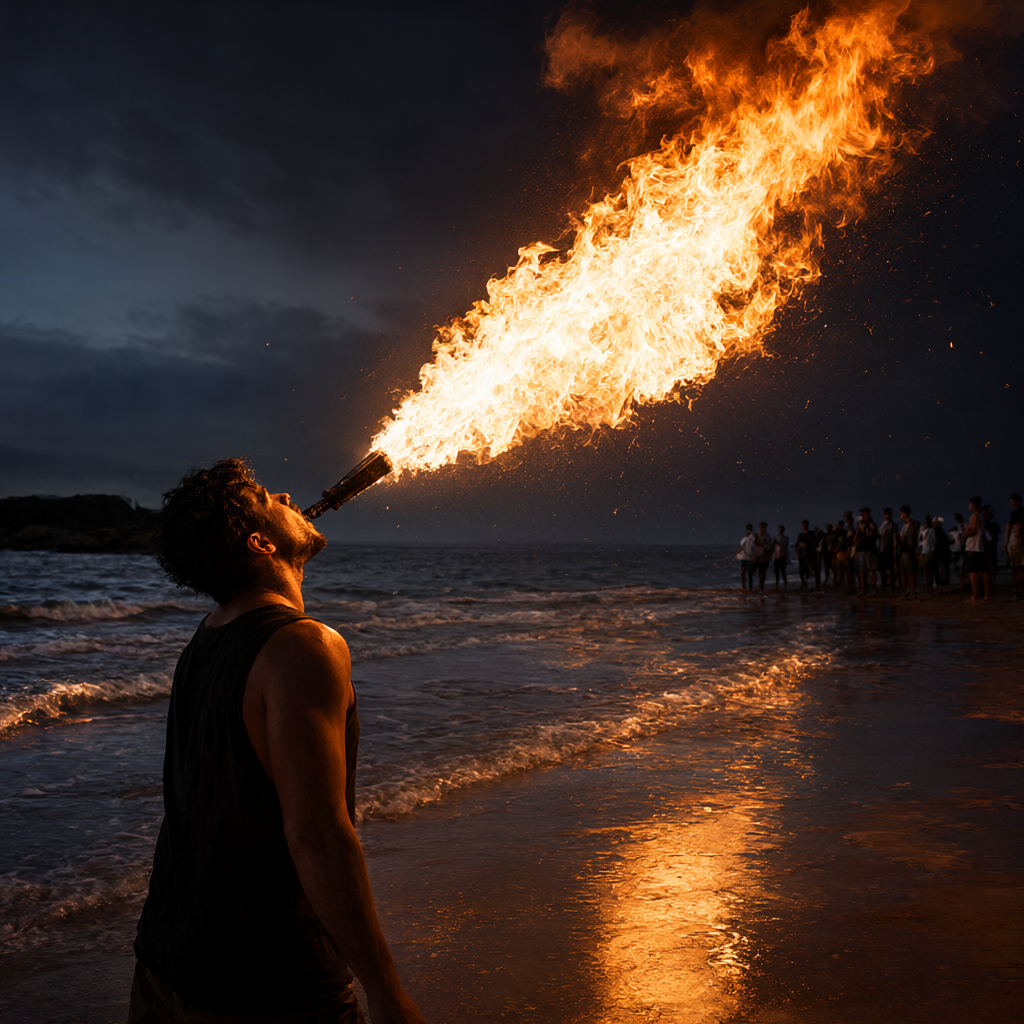
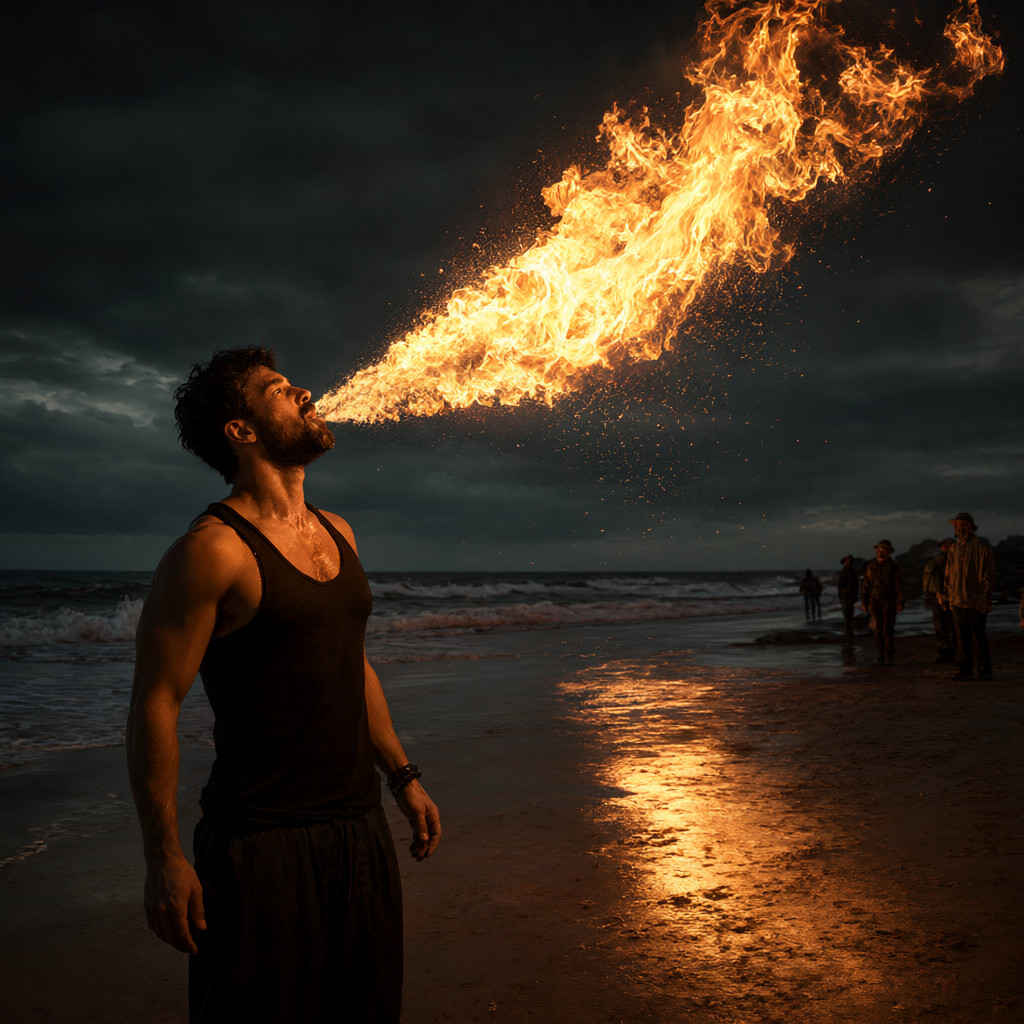
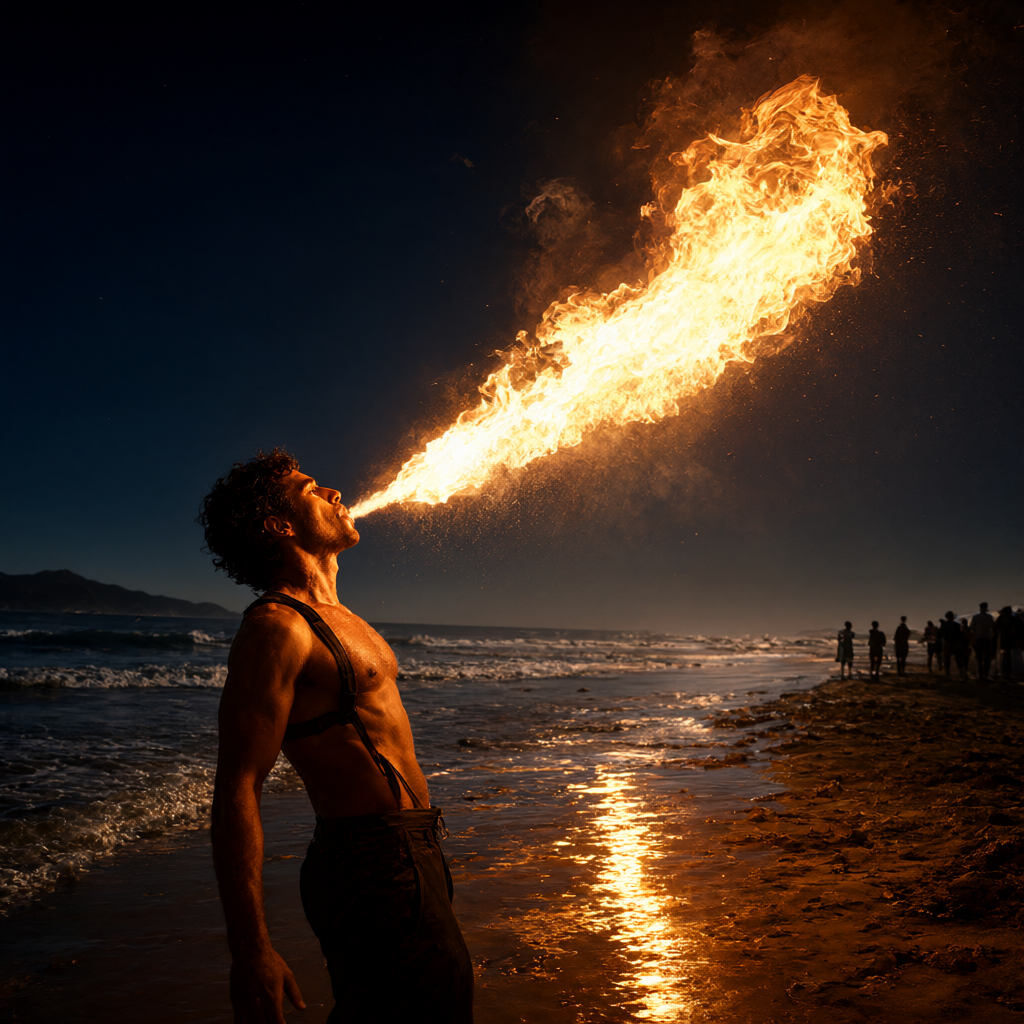
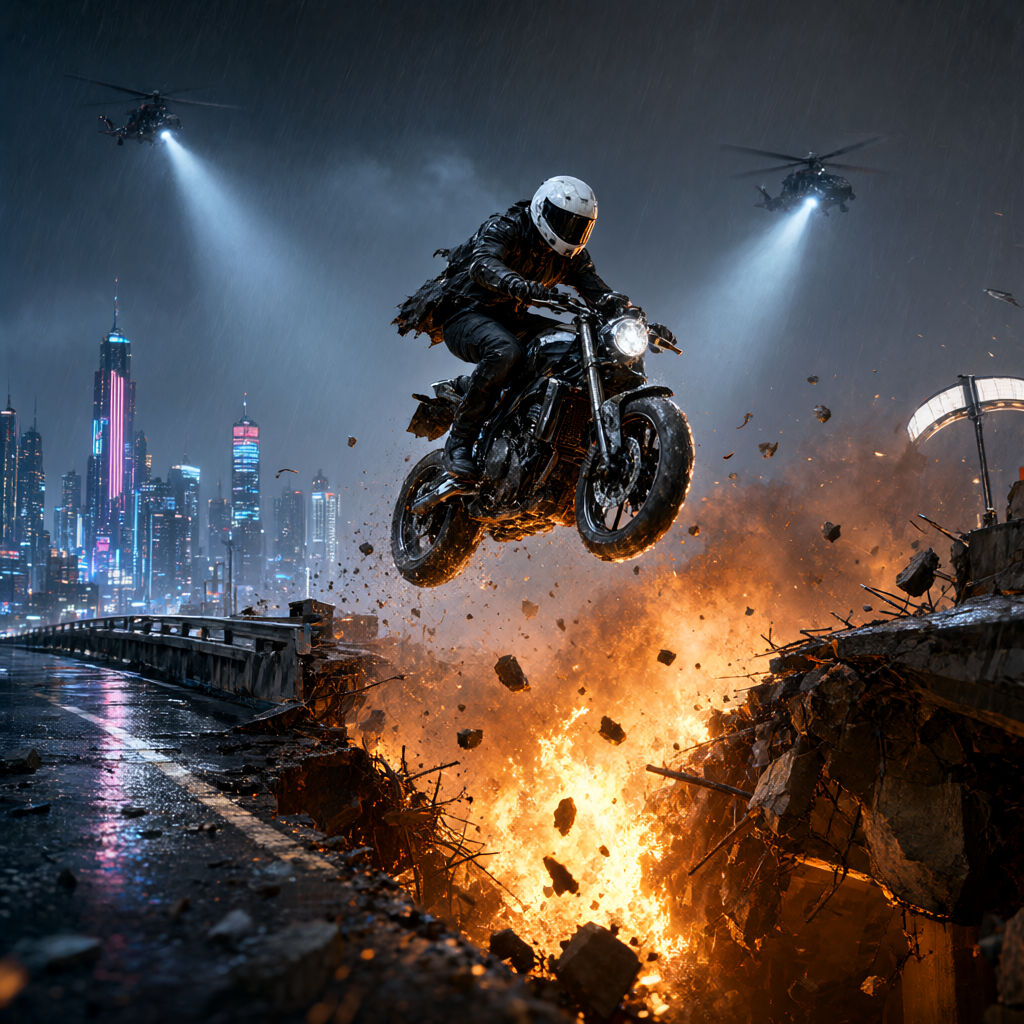
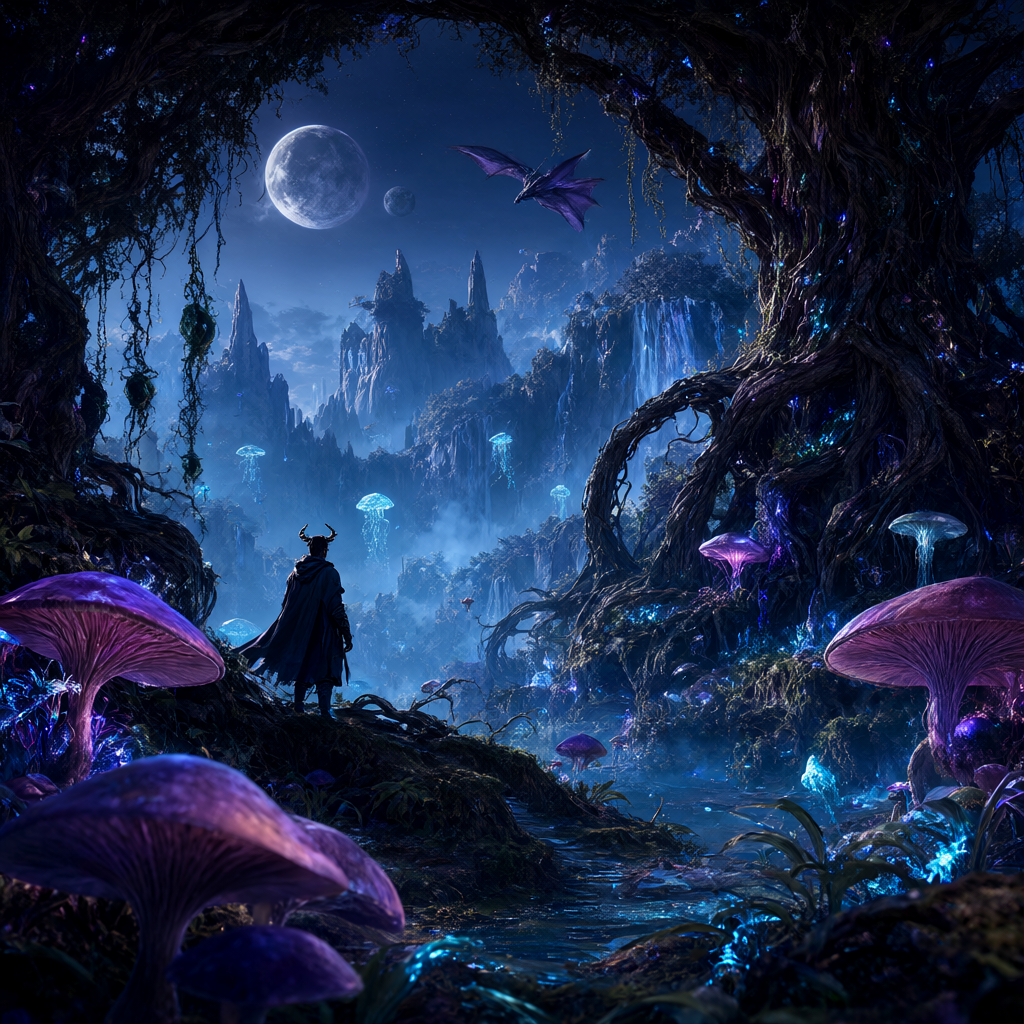
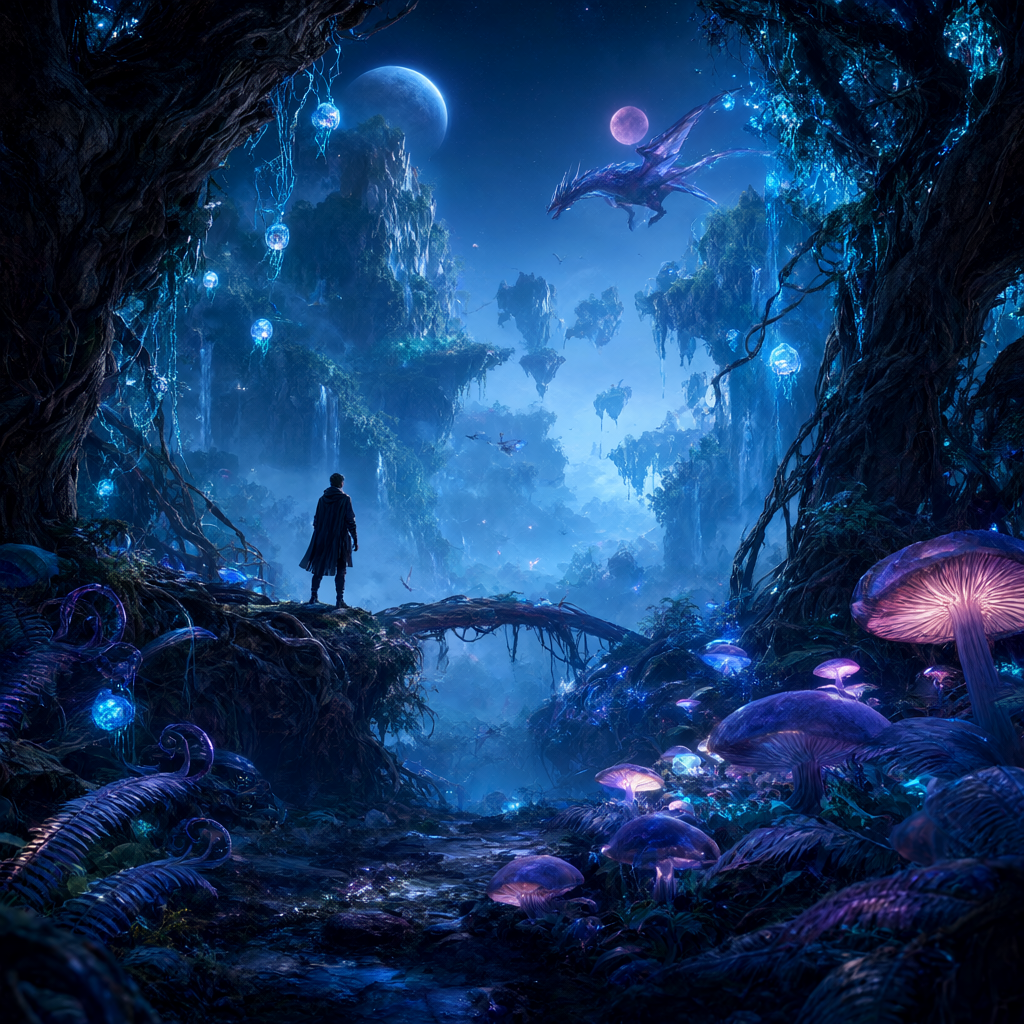
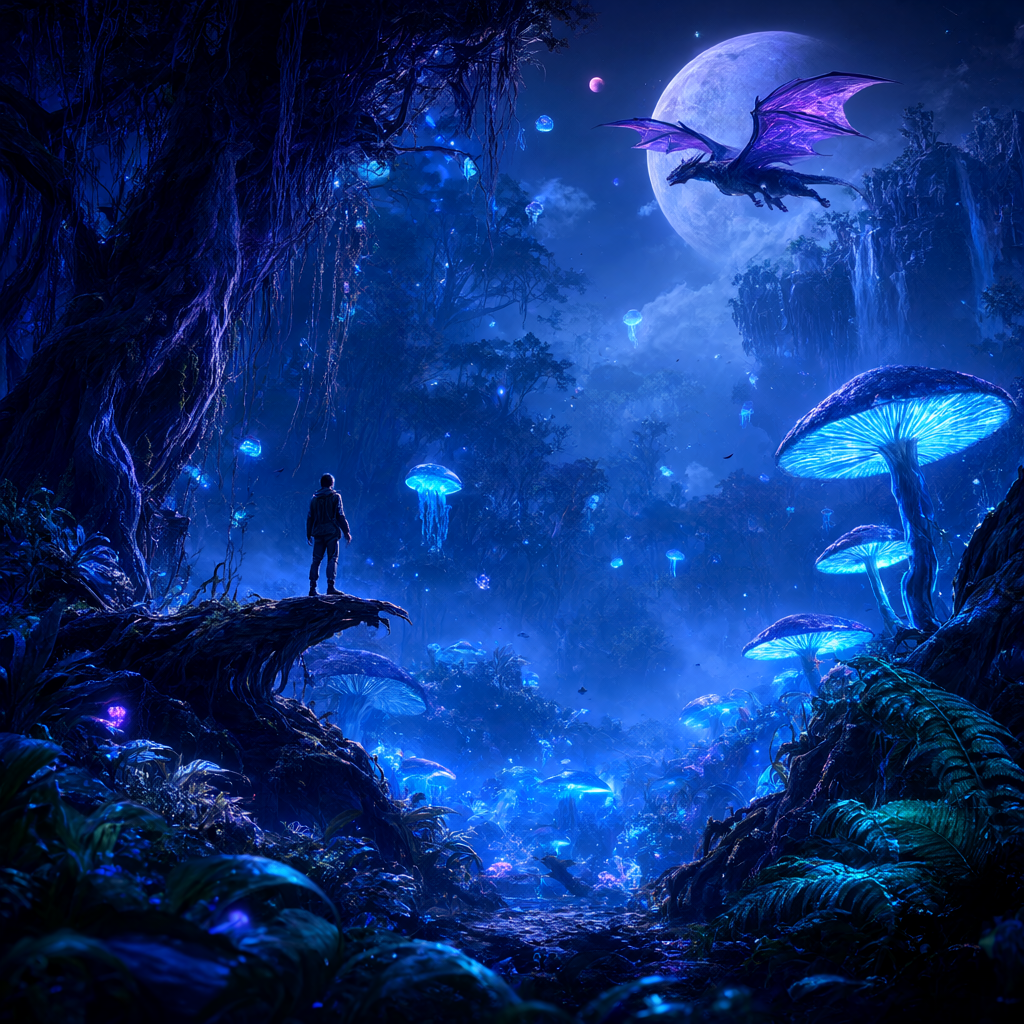
12 images, enhancer off
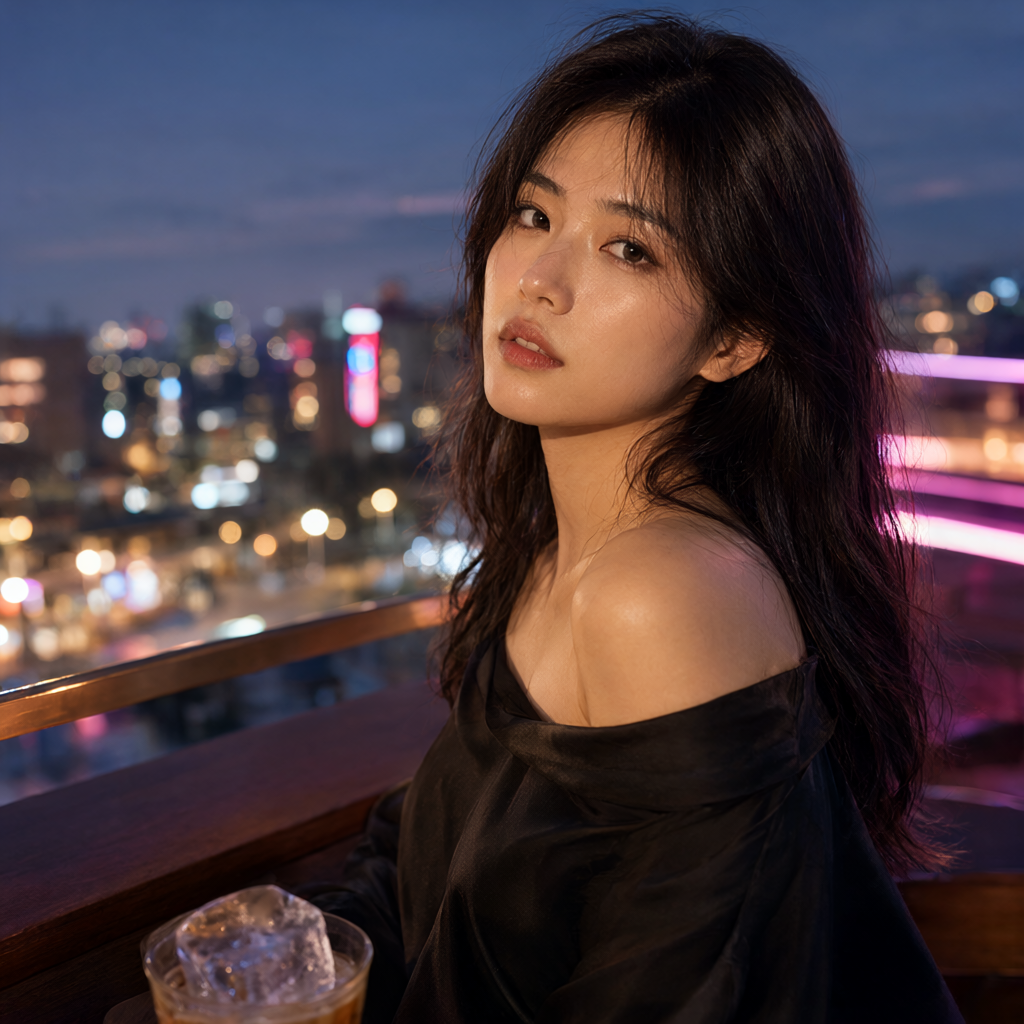
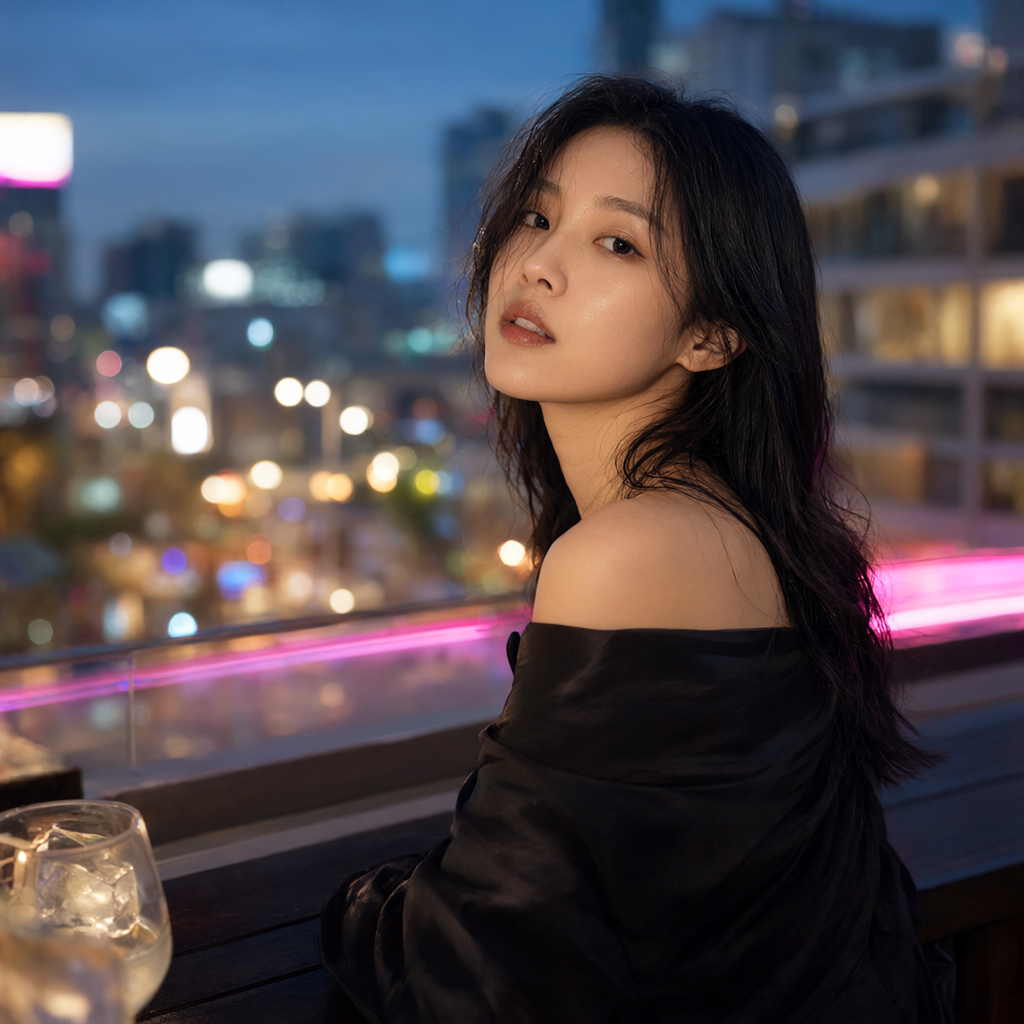
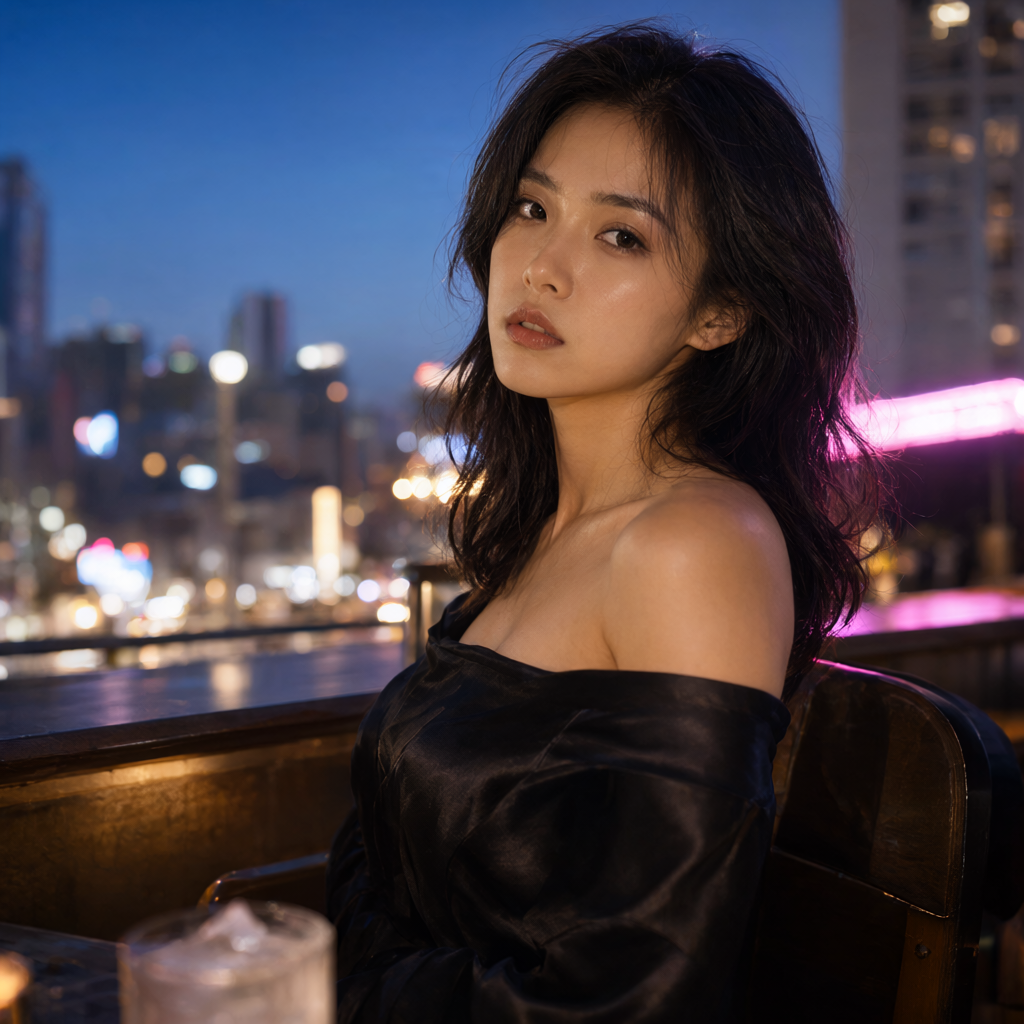
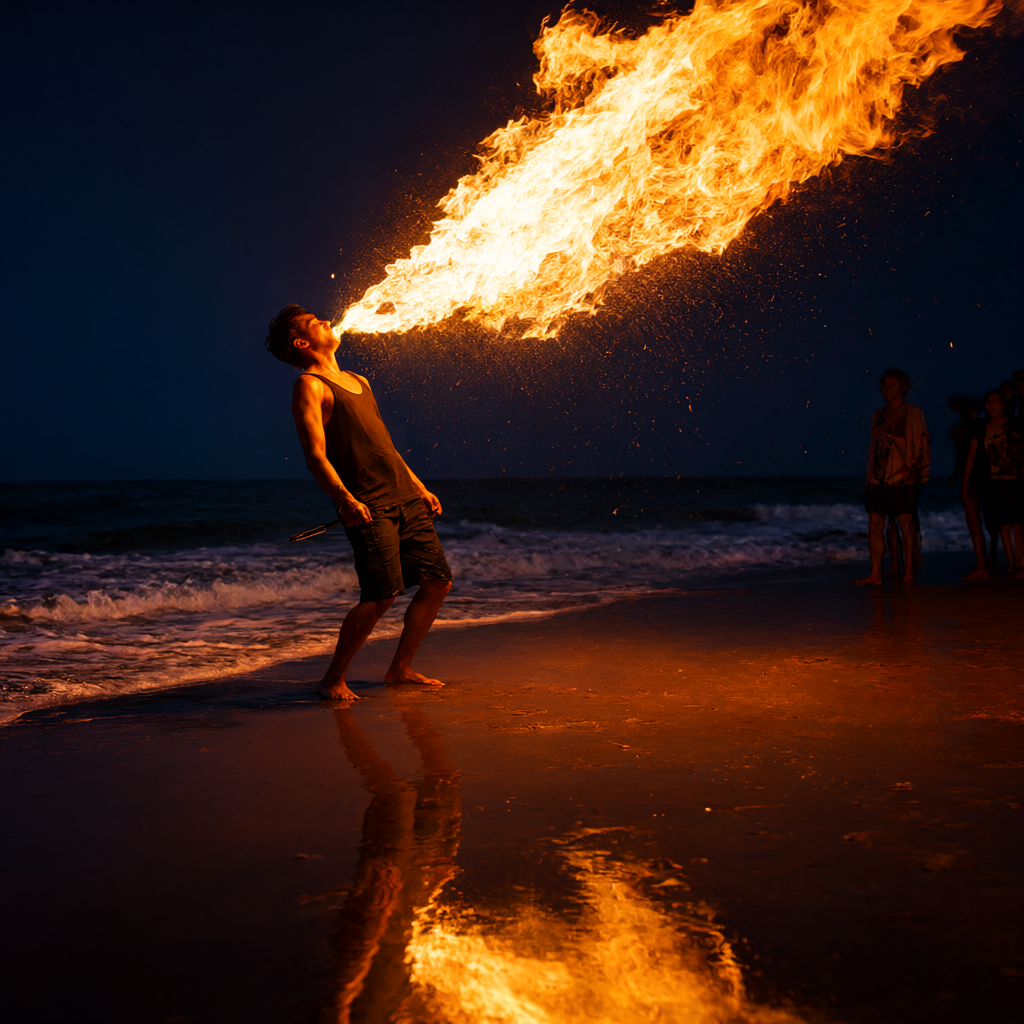
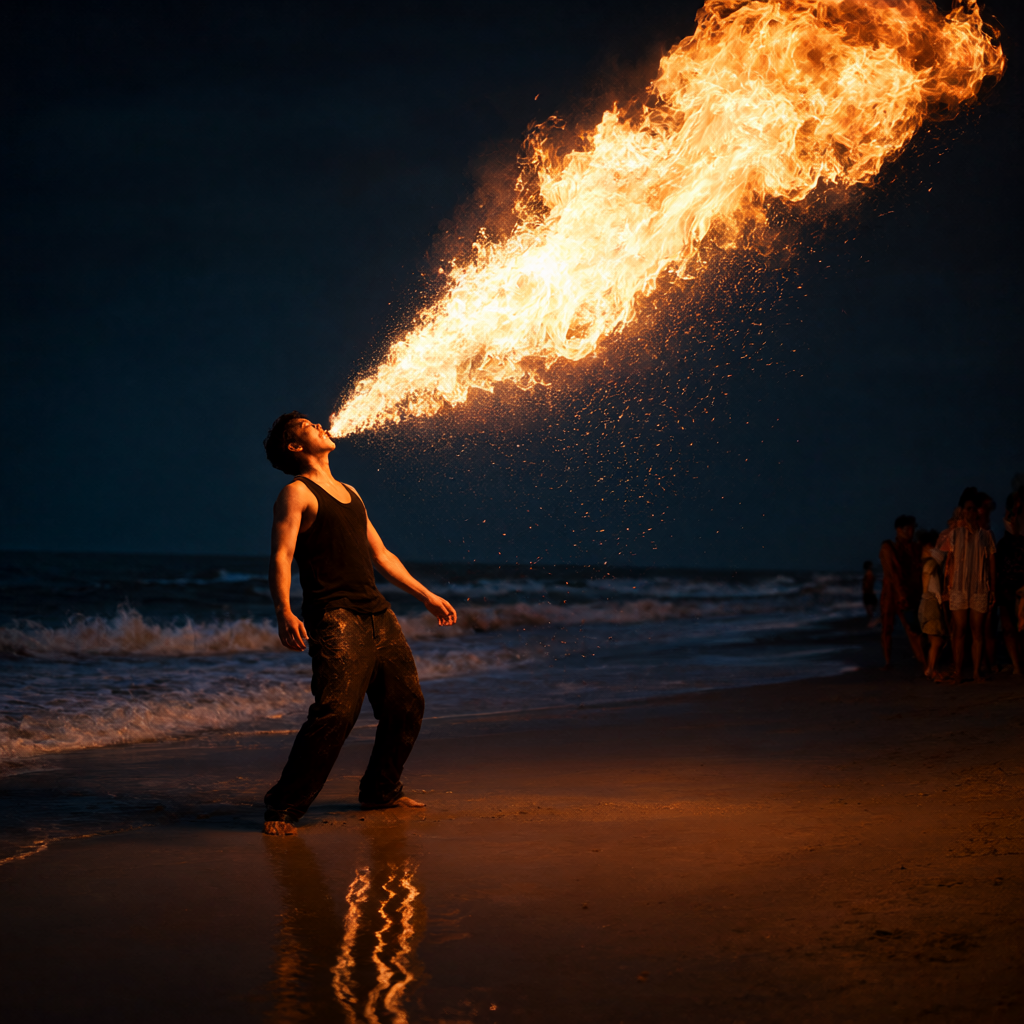
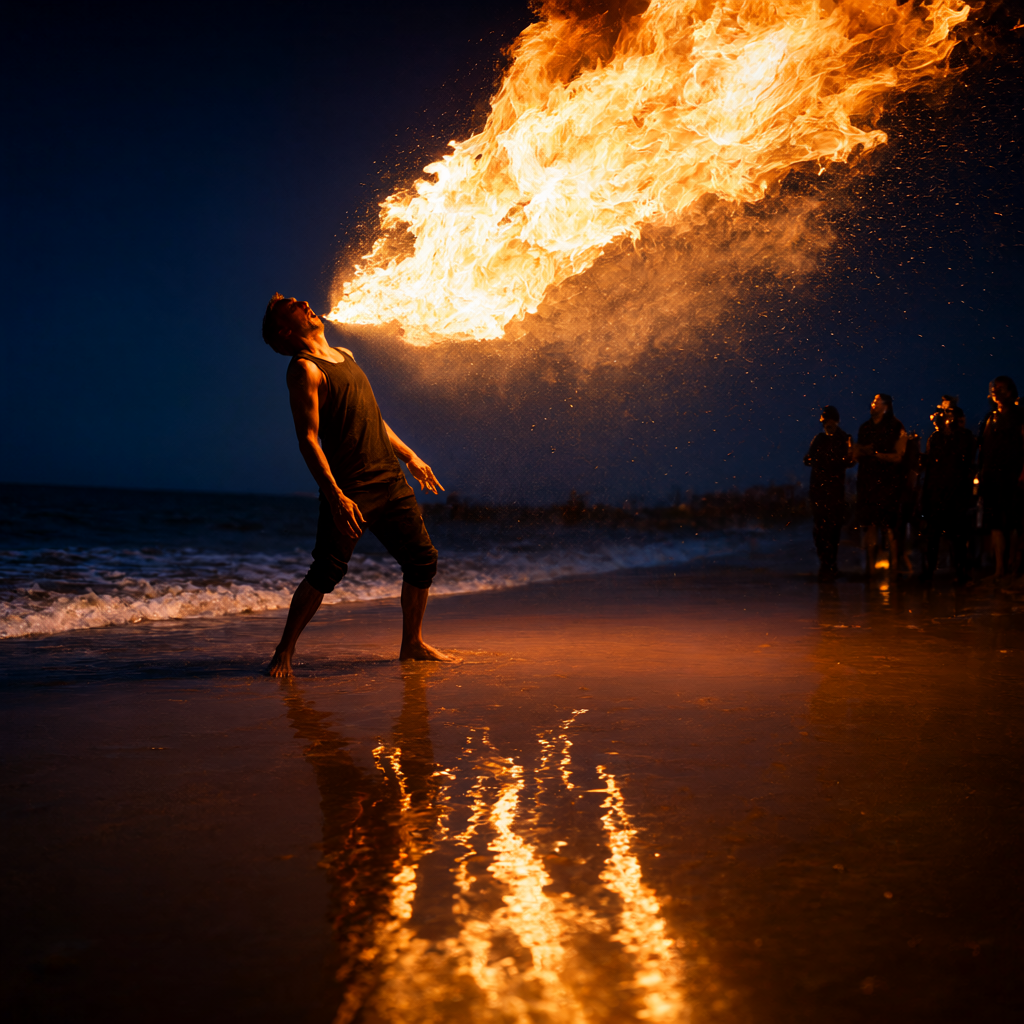
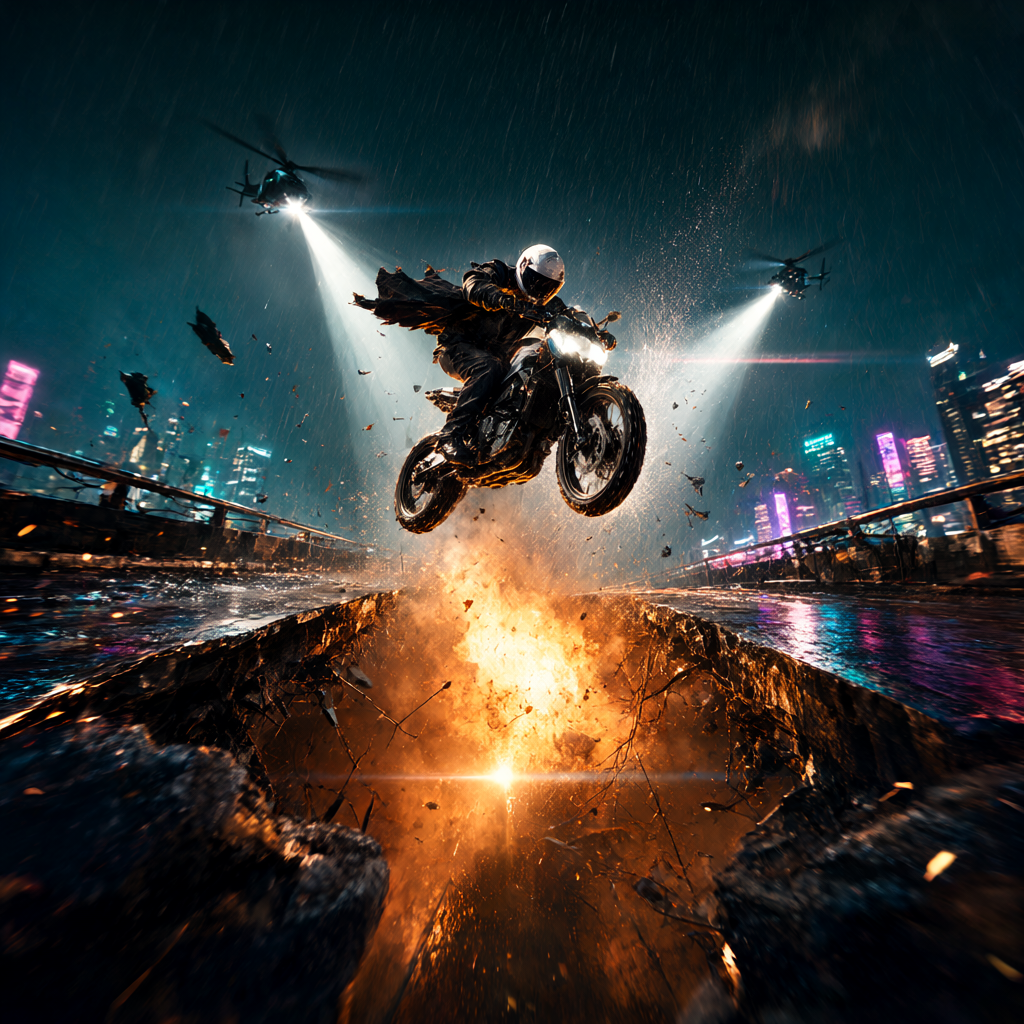
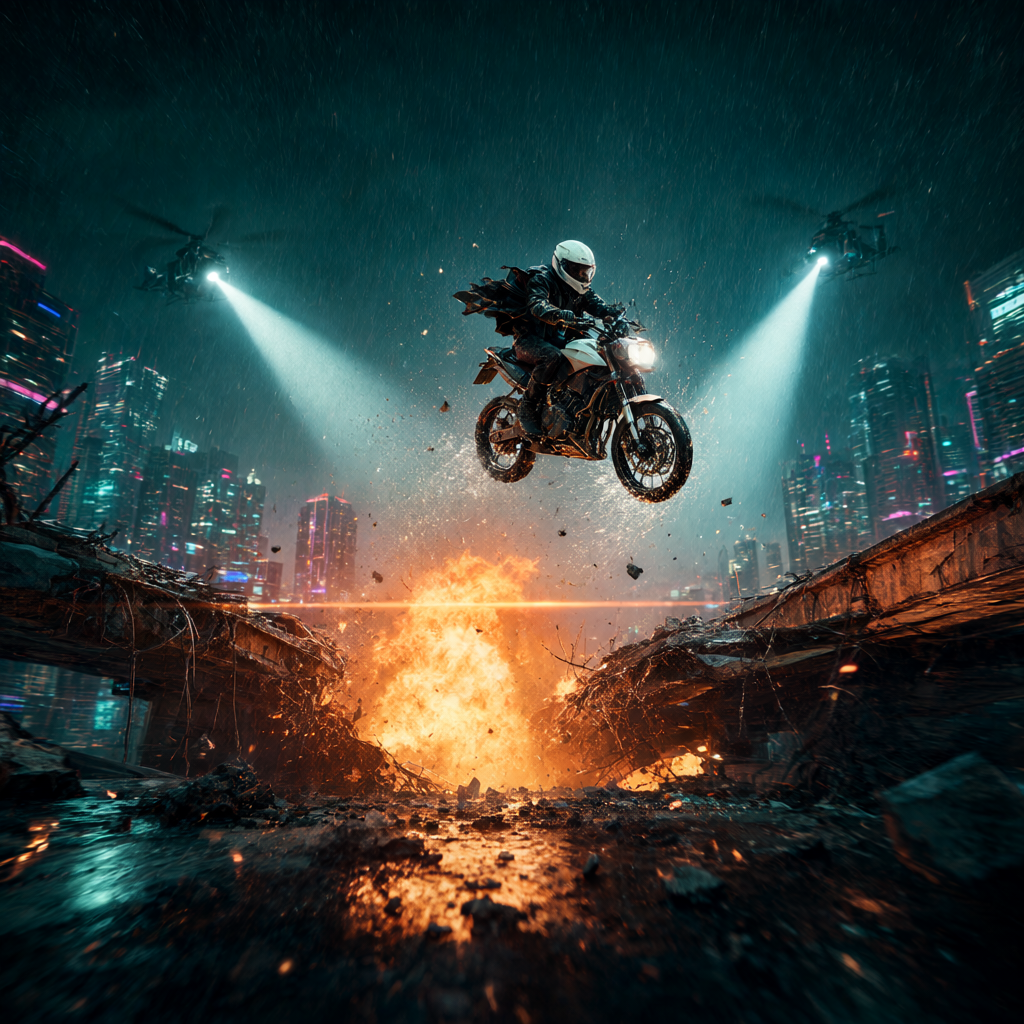
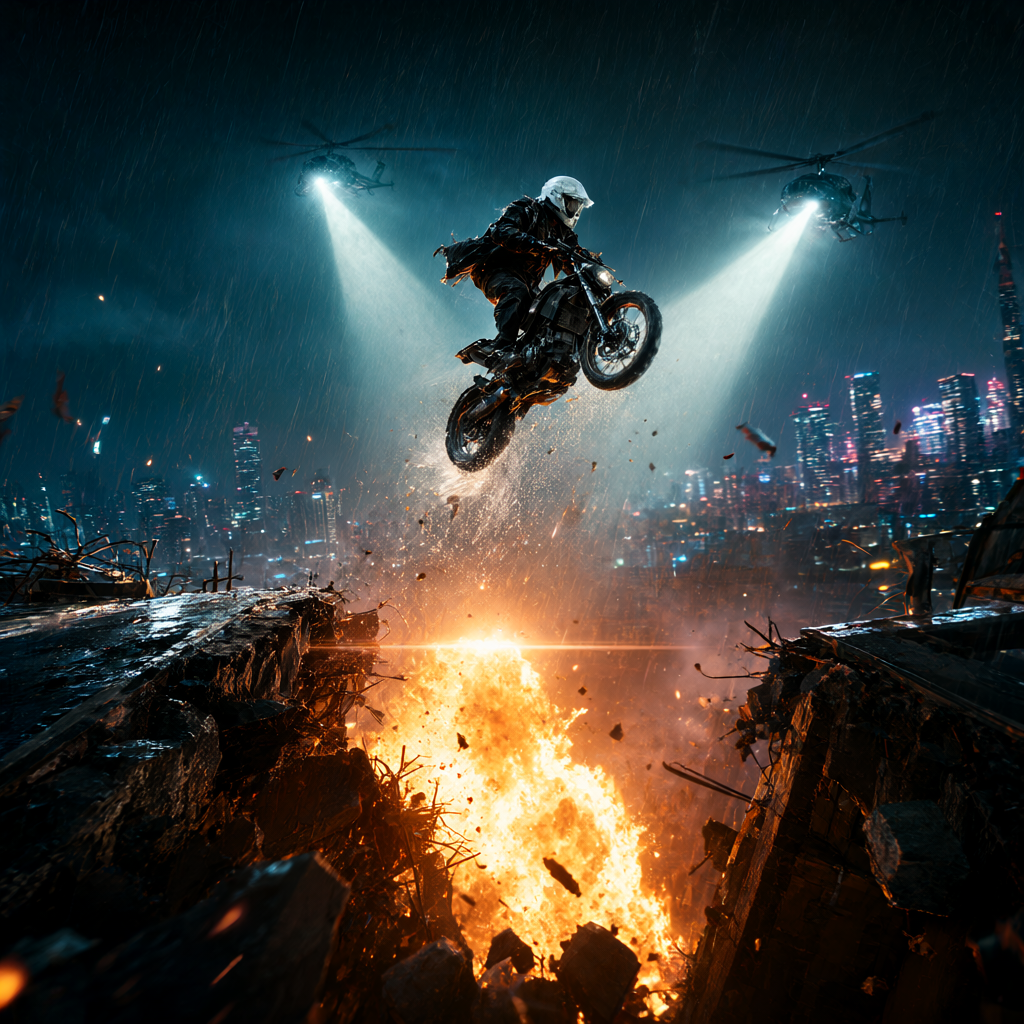
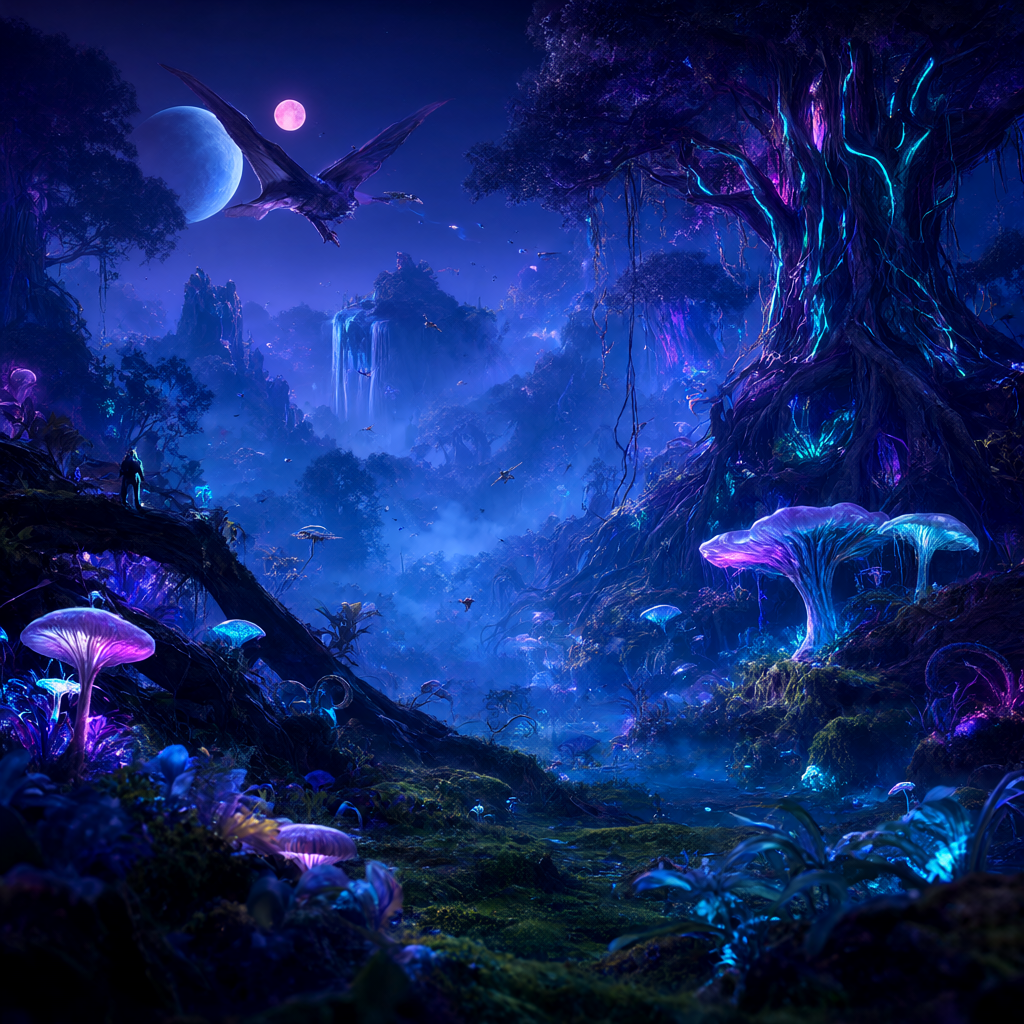
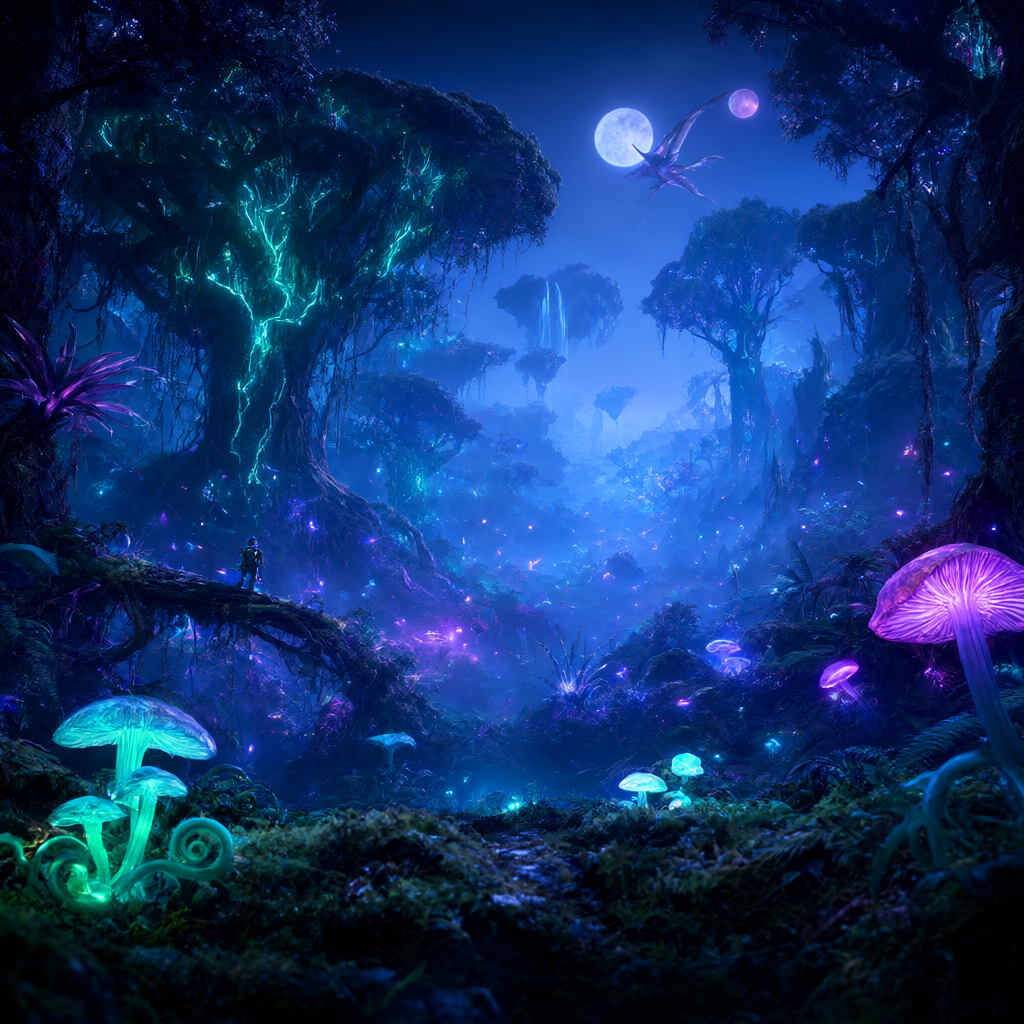
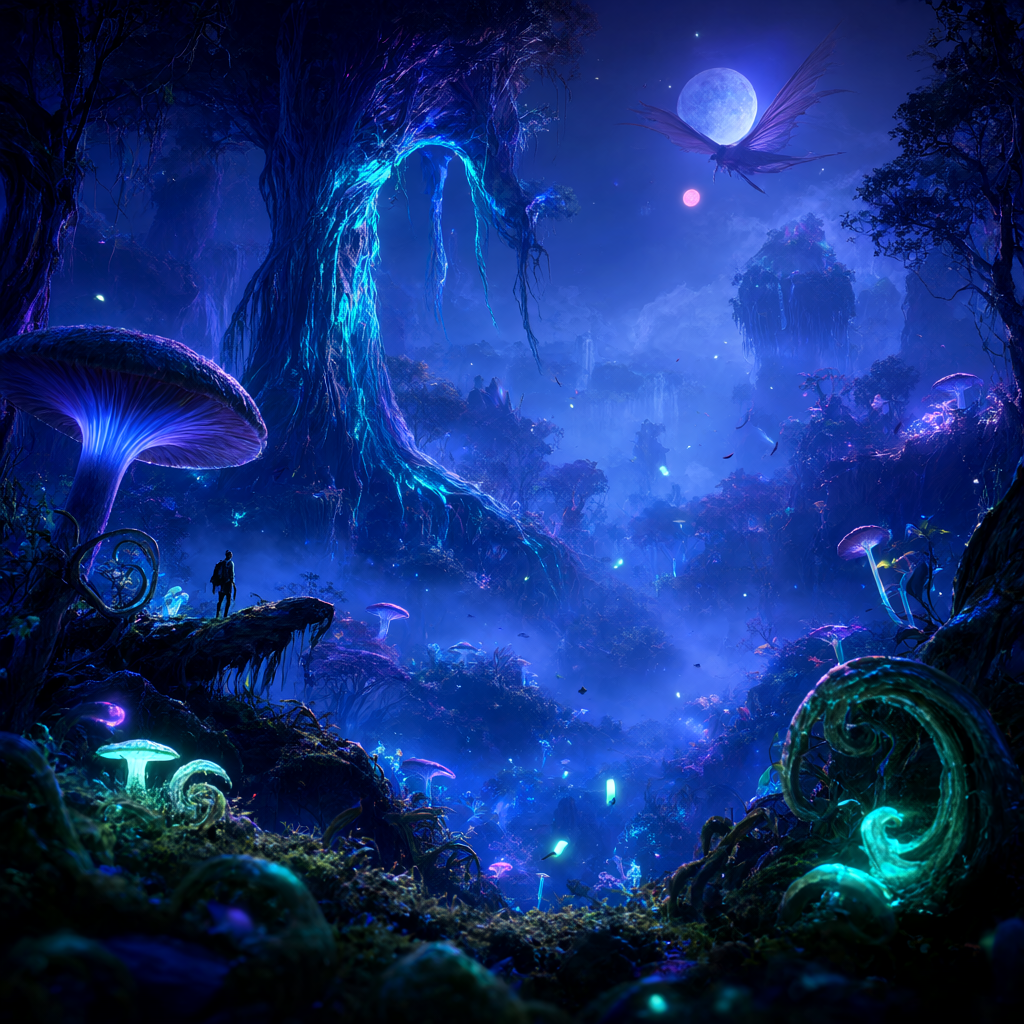
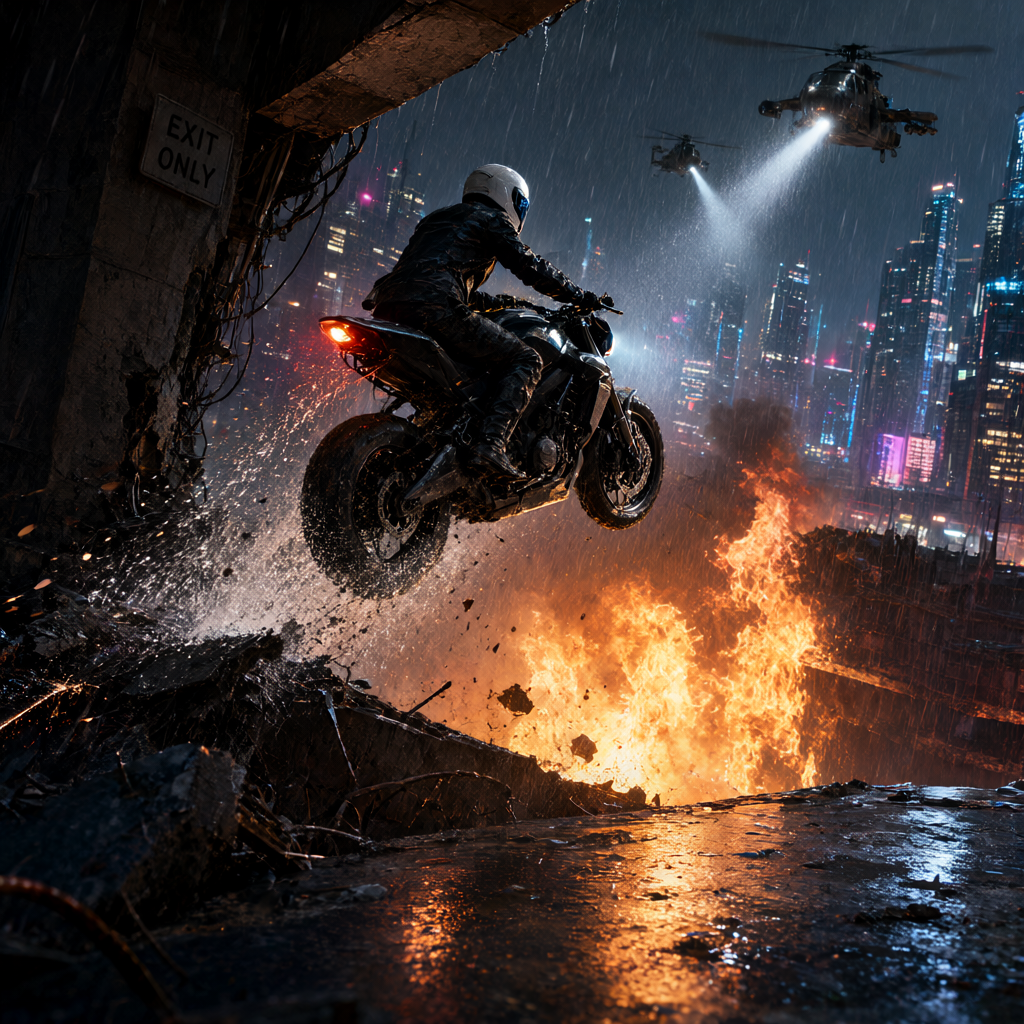
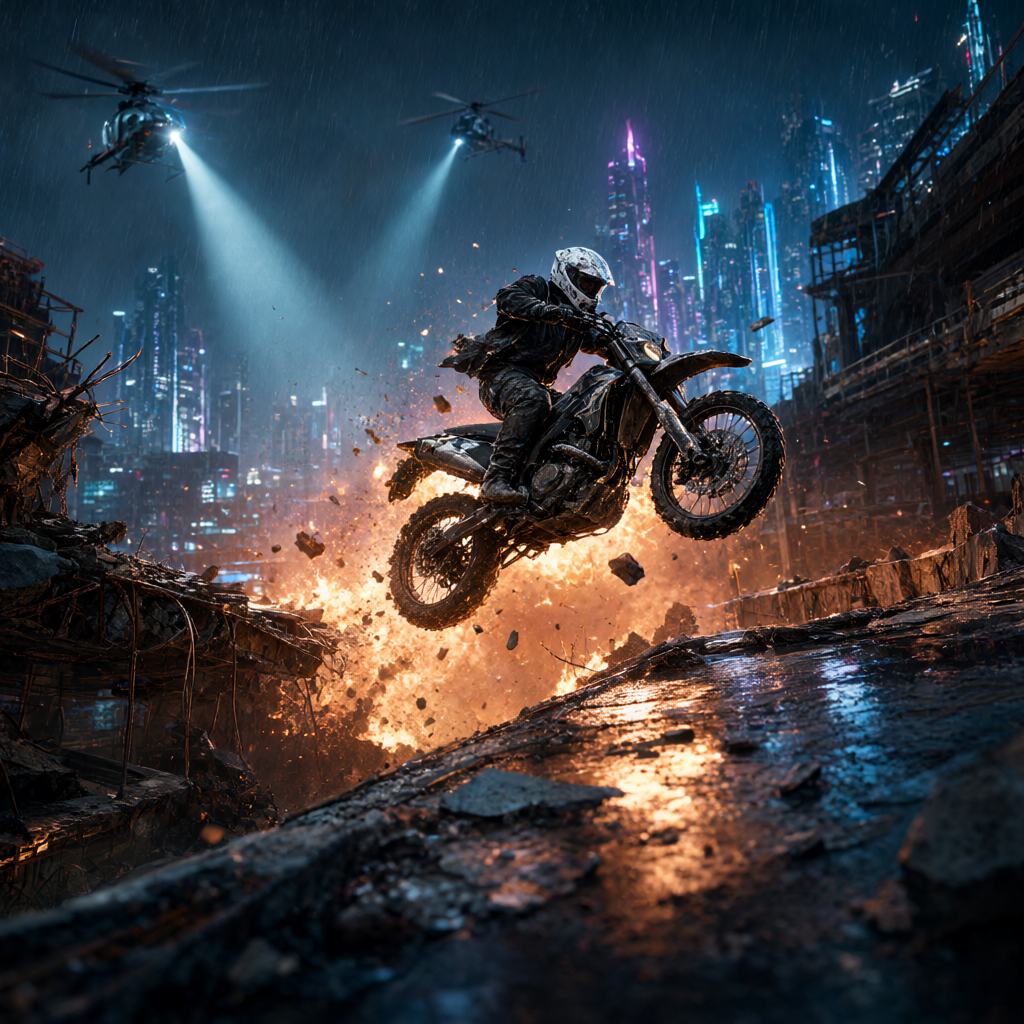
12 images, enhancer on
What to keep in mind
- mflux uses its own 8-bit quantization (-q 8, the test plan), not the ComfyUI INT8 ConvRot file of the other boxes. The mflux README names bf16 as the fastest way on Apple Silicon; I did not measure bf16. That is a different recipe, not an error.
- No enhancer ran on the Mac. The enhancer-on images use the enhancer texts written on the RTX 5090 box; the enhancer time is not measured.
- mflux uses the scheduler "linear" (its default), not euler / simple, and other noise: the same seed gives other pixels than on the CUDA boxes.
- Memory is the MLX peak of the unified memory in GiB, not comparable with the VRAM numbers of the other cards.
- A background service of macOS (mediaanalysisd) used about 130 % CPU at the start of this run and times rose over the run (28.3 s to 30.5 s with enhancer off). The run was not repeated.
Setup
- Model: Qwen-Image-2.1 Base
- Weights: huggingface.co/Qwen/Qwen-Image-2.1 @d26bb61231c3
- Quantization: mflux 8-bit (-q 8)
- Runner: mflux 0.23.0
- Software: mflux 0.23.0, mlx 0.32.4, Python 3.13.15, macOS
- Settings: 40 steps, guidance 1.0, scheduler linear (mflux default), no negative prompt, 1024x1024, batch 1, seeds 42 / 123 / 456
- Enhancer on: No enhancer on the Mac: the enhancer-on images use the texts written on the RTX 5090 box
- Hardware: Apple M5 Ultra, 256 GB unified memory
Exact command and run record
# mflux 0.23.0, 8-bit weights (-q 8), weights from the model repo, offline
HF_HUB_OFFLINE=1 python bench_bild_mac.py qwen --model-path <local copy of the model repo>
# Python API used by the script: QwenImage21(quantize=8, ...).generate_image(seed, prompt, num_inference_steps=40, width=1024, height=1024, guidance=1.0), no negative prompt
command.txt · all 4 prompts · times, enhancer off · times, enhancer on · All raw files
The four house prompts
I1 · Portrait, I2 · Fire breather, I3 · Action shot, I4 · Alien forest. The full text of the four prompts is in prompts.json.
What is like for like here
Every setup made the same 24 images: 4 house prompts (portrait, fire breather, action shot, alien forest; the full text is in prompts.json on each recipe page) × 3 seeds (42, 123, 456) × the prompt enhancer off and on, at 1024×1024, one warm-up image thrown away. The speed numbers are the medians of the 12 images of a mode. With the enhancer on, the model's own prompt rewriter wrote the text first; those texts were written once on the RTX 5090 box and reused on every box, so the enhancer-on images all start from the same text. The enhancer time is measured in its own run and is not in the image time.
The ComfyUI setups use INT8 ConvRot weights (Comfy Org format); the Mac uses mflux with its own 8-bit quantization, so the Mac recipe differs. The same seed gives other pixels on other hardware. I rate pictures I like to look at; it is one person's taste, so read the ratings as my ratings, not as a quality measurement. Image files are published with the metadata chunk removed, pixels identical; the hashes in the time files are those of the published files (png_sha256_original is the hash of the original). All images on this page are AI-generated.