Home / Other

32 GB · RTX 5090 32 GB

SUPRA-Tex (image to textured 3D) on an RTX 5090

SUPRA-Tex turns one image into a textured PBR 3D model (GLB). On one RTX 5090 32 GB it took a median of 105.85 s per image over 10 images (88 s to 211 s), with 4096 px textures and up to 500,000 triangles per model.

Image to 3DSUPRA-Texmeasured 3 Nov 2026not rankedAI-generated outputs

Not ranked. Measured on the devices shown here only. No rating and no rank: this result has no rating by me yet.

32 GB

RTX 5090 32 GB · all 10 images · 4096 px textures

one RTX 5090 32 GB

Median time per image (10 images)105.85 seach image: median of its warm runs (9 images: 1 warm run, README example: median of 3)
Fastest image87.95 srobot watering a plant, 1 warm run
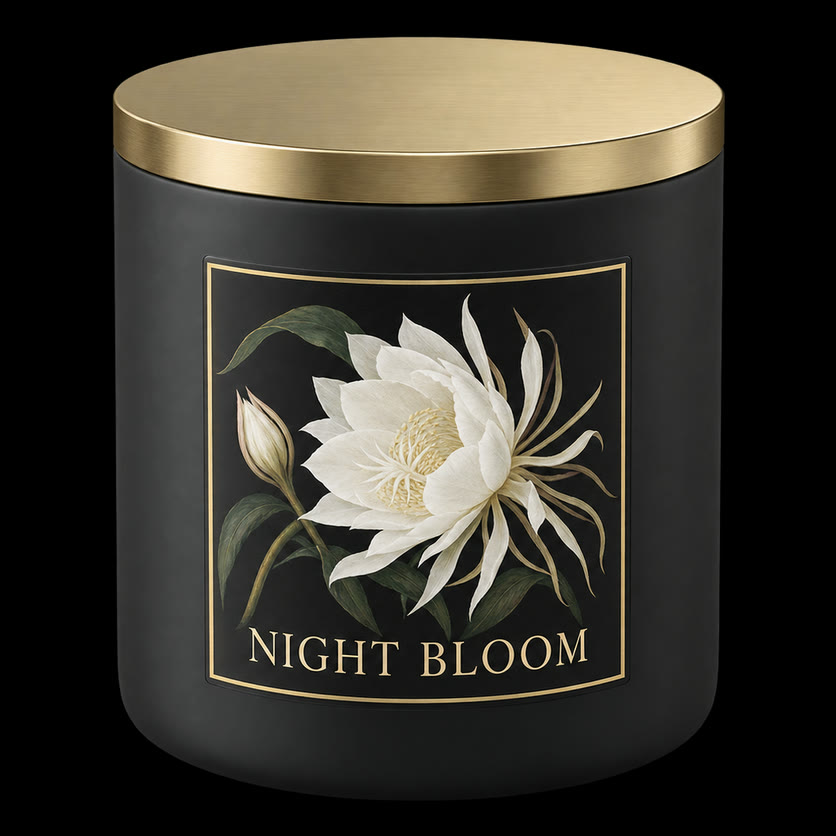
Slowest image210.58 smetalwork candle jar, 1 warm run
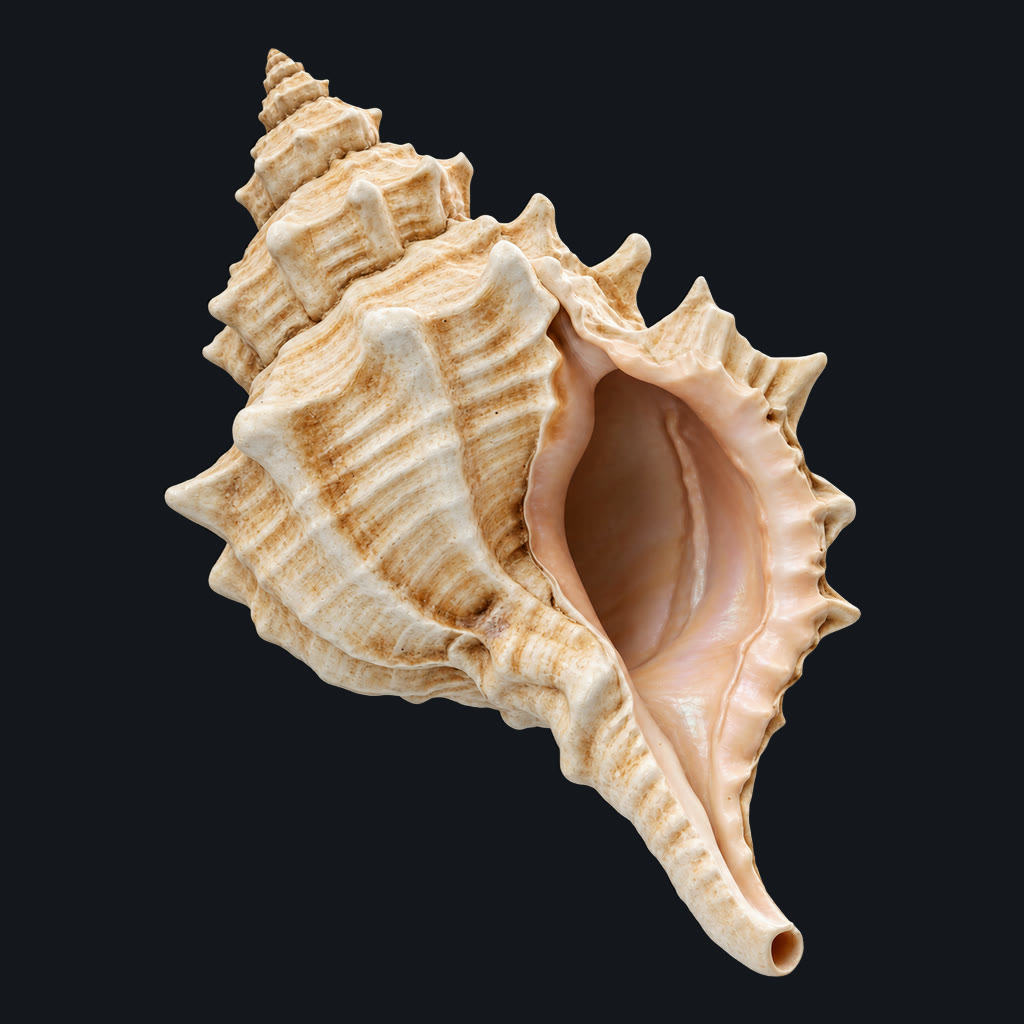
README example, median of 3 warm runs96.24 sspiny whelk shell: 106.02 s, 96.24 s, 93.16 s (runs/w1-whelk.json, w2-whelk.json, w3-whelk.json)
First run, empty compile caches238.74 sREADME example, first run after creating empty compile caches; counted separately, not in the median
Peak VRAM, all 13 runs20,923 MiB (20.4 GiB)nvidia-smi sample every second, highest value over the 13 runs (summary.json)
32 GB

RTX 5090 32 GB · output of all 13 GLB files

one RTX 5090 32 GB

Triangles per GLB465,640 to 499,934author default: decimation target 500,000
Vertices per GLB310,884 to 417,417read from the output files with trimesh
GLB file size41.5 to 54.7 MB41,505,424 to 54,745,112 bytes (MB = 10^6 bytes)
Texture size4096 × 4096base color and metallic-roughness, in all 13 GLB files
Peak system RAM (process tree)28.99 GiBhighest value over the 13 runs
32 GB

Spiny whelk shell · RTX 5090 32 GB · 4096 px textures

one RTX 5090 32 GB

Median time per image96.24 smedian of 3 warm runs (106.02, 96.24, 93.16 s)
Triangles493,898GLB of run w2-whelk
Vertices310,884GLB of run w2-whelk
GLB file size44.8 MB44,810,808 bytes
Peak VRAM20,921 MiBnvidia-smi, 1 s samples
Texture size4096 × 4096base color and metallic-roughness
32 GB

Pitcher plant · RTX 5090 32 GB · 4096 px textures

one RTX 5090 32 GB

Median time per image161.51 s1 warm run
Triangles485,518GLB of run p1-pitcher
Vertices374,214GLB of run p1-pitcher
GLB file size46.4 MB46,431,072 bytes
Peak VRAM20,921 MiBnvidia-smi, 1 s samples
Texture size4096 × 4096base color and metallic-roughness
32 GB

Metalwork candle jar · RTX 5090 32 GB · 4096 px textures

one RTX 5090 32 GB

Median time per image210.58 s1 warm run
Triangles496,743GLB of run m1-candle
Vertices345,032GLB of run m1-candle
GLB file size41.5 MB41,505,424 bytes
Peak VRAM20,923 MiBnvidia-smi, 1 s samples
Texture size4096 × 4096base color and metallic-roughness
32 GB

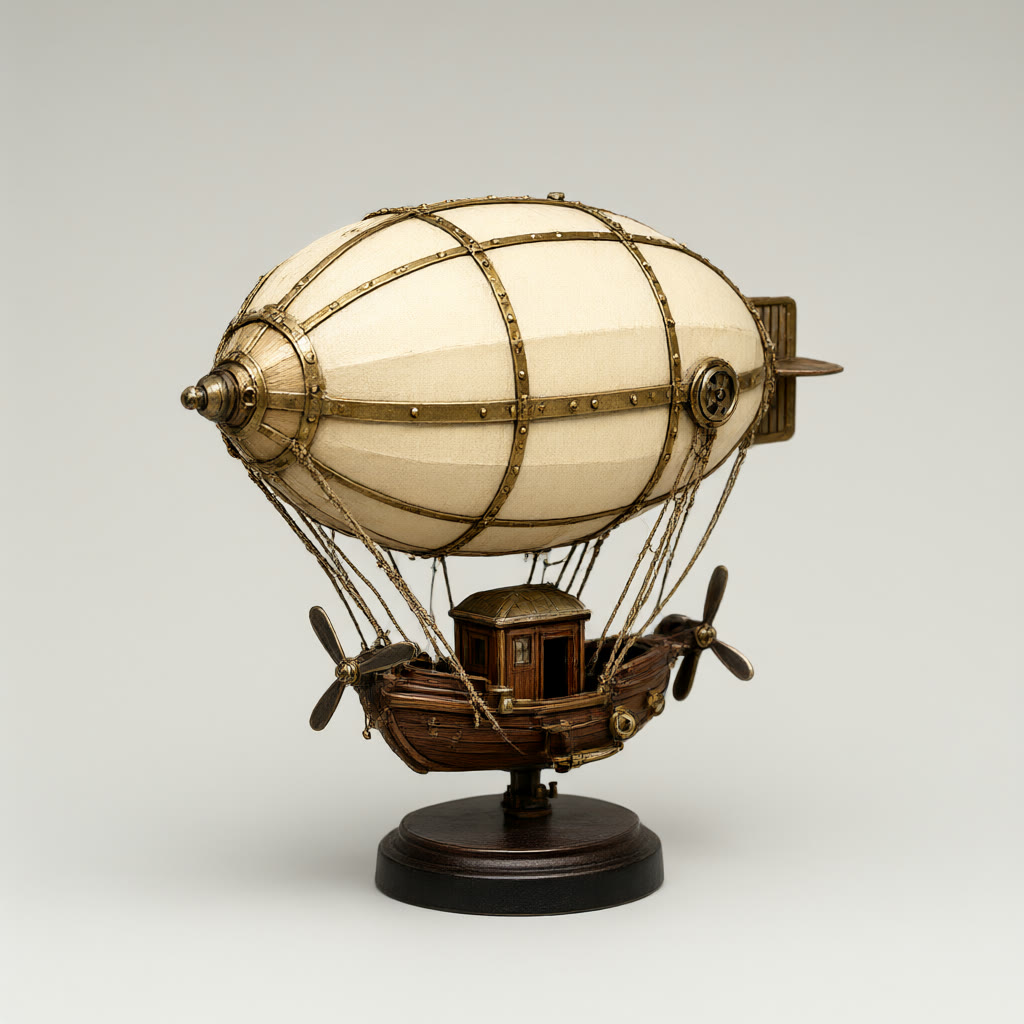
Steampunk airship · RTX 5090 32 GB · 4096 px textures

one RTX 5090 32 GB

Median time per image118.70 s1 warm run
Triangles475,529GLB of run r-airship-1
Vertices417,417GLB of run r-airship-1
GLB file size54.7 MB54,745,112 bytes
Peak VRAM20,923 MiBnvidia-smi, 1 s samples
Texture size4096 × 4096base color and metallic-roughness
32 GB

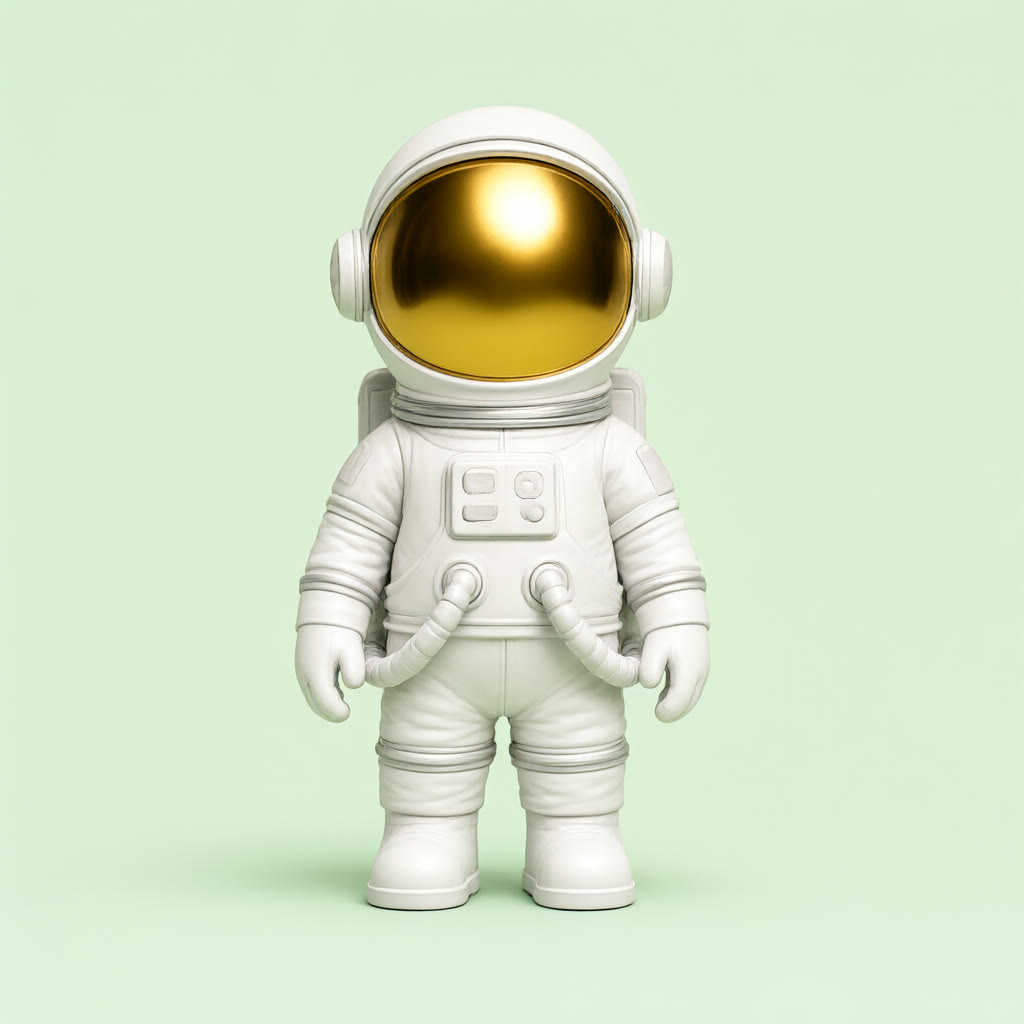
Vinyl astronaut toy · RTX 5090 32 GB · 4096 px textures

one RTX 5090 32 GB

Median time per image97.14 s1 warm run
Triangles465,640GLB of run r-astronaut-1
Vertices335,550GLB of run r-astronaut-1
GLB file size45.9 MB45,918,268 bytes
Peak VRAM20,923 MiBnvidia-smi, 1 s samples
Texture size4096 × 4096base color and metallic-roughness
32 GB

Dragon figurine · RTX 5090 32 GB · 4096 px textures

one RTX 5090 32 GB

Median time per image114.56 s1 warm run
Triangles476,041GLB of run r-dragon-1
Vertices332,589GLB of run r-dragon-1
GLB file size46.4 MB46,427,720 bytes
Peak VRAM20,923 MiBnvidia-smi, 1 s samples
Texture size4096 × 4096base color and metallic-roughness
32 GB

Toy locomotive · RTX 5090 32 GB · 4096 px textures

one RTX 5090 32 GB

Median time per image93.50 s1 warm run
Triangles494,099GLB of run r-locomotive-1
Vertices362,517GLB of run r-locomotive-1
GLB file size51.8 MB51,758,908 bytes
Peak VRAM20,923 MiBnvidia-smi, 1 s samples
Texture size4096 × 4096base color and metallic-roughness
32 GB

Robot holding a graphics card · RTX 5090 32 GB · 4096 px textures

one RTX 5090 32 GB

Median time per image145.42 s1 warm run
Triangles492,105GLB of run r-robot-1
Vertices387,399GLB of run r-robot-1
GLB file size52.8 MB52,780,568 bytes
Peak VRAM20,923 MiBnvidia-smi, 1 s samples
Texture size4096 × 4096base color and metallic-roughness
32 GB

Robot watering a plant · RTX 5090 32 GB · 4096 px textures

one RTX 5090 32 GB

Median time per image87.95 s1 warm run
Triangles490,424GLB of run r-robotplant-1
Vertices374,749GLB of run r-robotplant-1
GLB file size46.0 MB46,046,432 bytes
Peak VRAM20,923 MiBnvidia-smi, 1 s samples
Texture size4096 × 4096base color and metallic-roughness
32 GB

Teapot · RTX 5090 32 GB · 4096 px textures

one RTX 5090 32 GB

Median time per image92.64 s1 warm run
Triangles499,934GLB of run r-teapot-1
Vertices339,586GLB of run r-teapot-1
GLB file size46.6 MB46,622,108 bytes
Peak VRAM20,923 MiBnvidia-smi, 1 s samples
Texture size4096 × 4096base color and metallic-roughness
Outputs

Real outputs

Input image: Spiny whelk shell
AI-generated Input image: Spiny whelk shell. Author example (spiny_whelk_shell.png, transparent background, shown on dark grey; its own alpha channel is the mask). SUPRA-Tex time for this image: median of 3 warm runs, 96.24 s. · 96.24 s Prompt: Author example image from the SUPRA-Tex repository (no prompt given). full size
AI-generated video Turntable of the real output GLB of w2-whelk (spiny whelk shell): one full turn, rendered with Blender Cycles for display only, no edits to the model. SUPRA-Tex time for this image: 96.24 s.
Prompt

Image to 3D from the input image shown above, seed 42, author defaults.
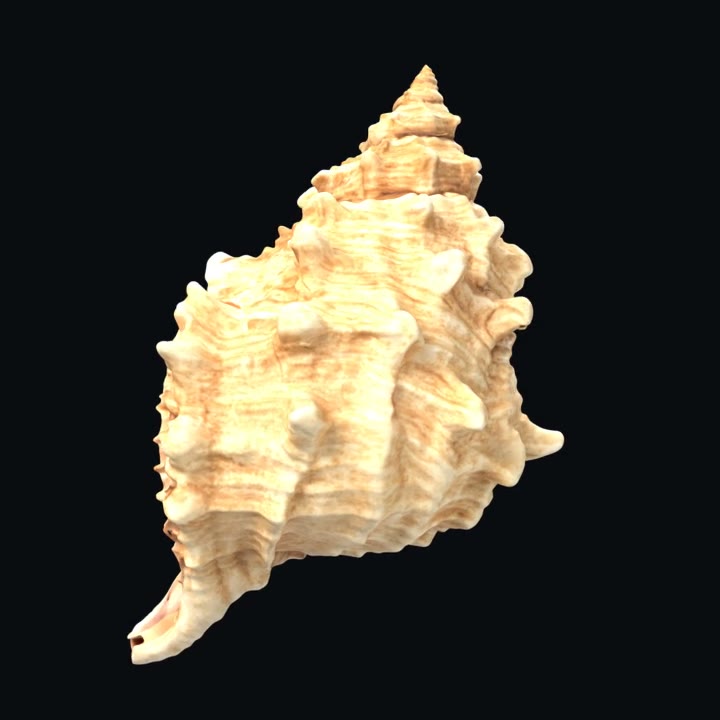
Rear view of the generated 3D model: spiny whelk shell
AI-generated Rear view of the generated GLB (w2-whelk, spiny whelk shell). The input image never shows this side, so the model invents it. · 96.24 s Prompt: Image to 3D from the input image shown above, seed 42, author defaults. full size
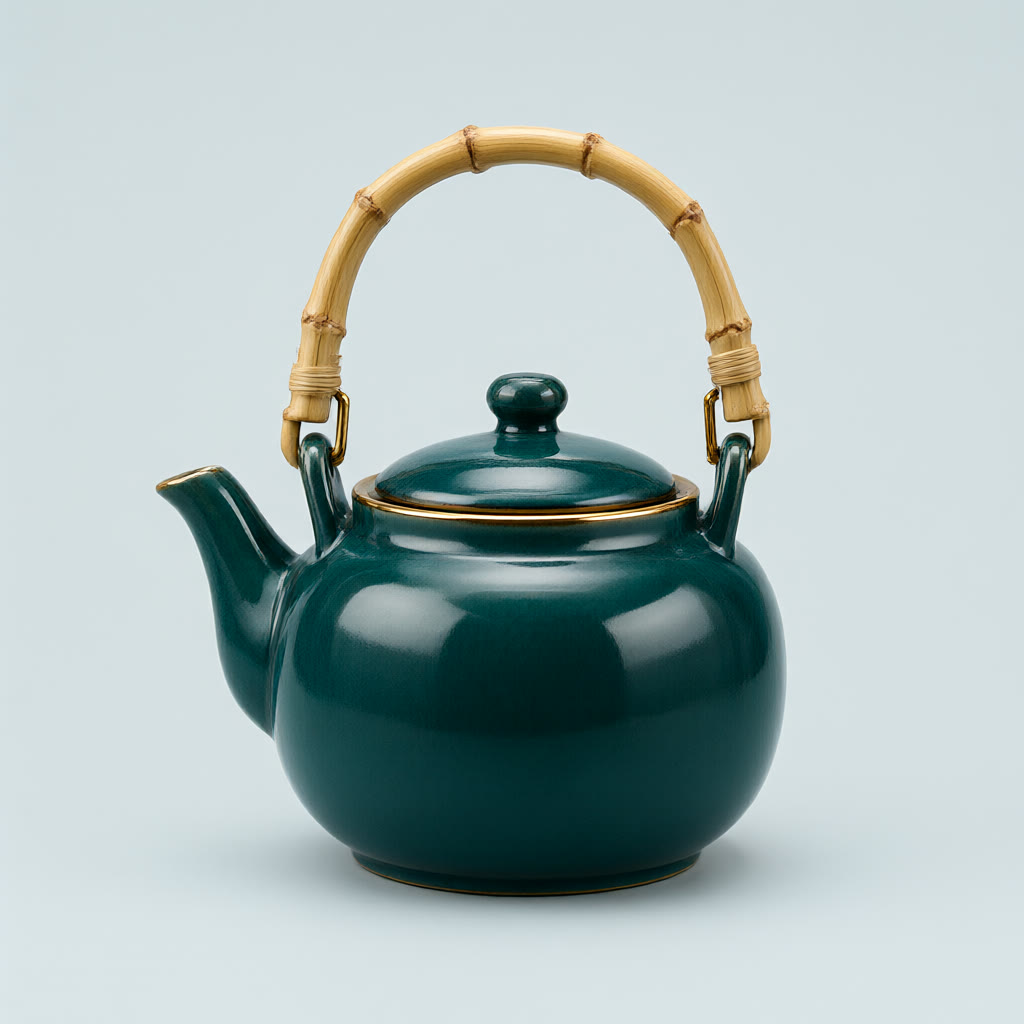
Input image: Teapot
AI-generated Input image: Teapot. Own input made with Qwen-Image 2.1 Turbo NVFP4 (seed 42, 1024×1024), opaque RGB copy as fed to SUPRA-Tex. SUPRA-Tex time for this image: 92.64 s. · 92.64 s Prompt: A glossy ceramic teapot in deep teal with gold trim, a round lid and a bamboo handle. Single object, centered and fully inside the frame with generous margin on all sides, plain seamless solid pale grey blue background, soft even studio lighting with a soft contact shadow, sharp focus, high detail, collectible figure product photograph, no text, no logo, no brand name, no people. full size
AI-generated video Turntable of the real output GLB of r-teapot-1 (teapot): one full turn, rendered with Blender Cycles for display only, no edits to the model. SUPRA-Tex time for this image: 92.64 s.
Prompt

Image to 3D from the input image shown above, seed 42, author defaults.
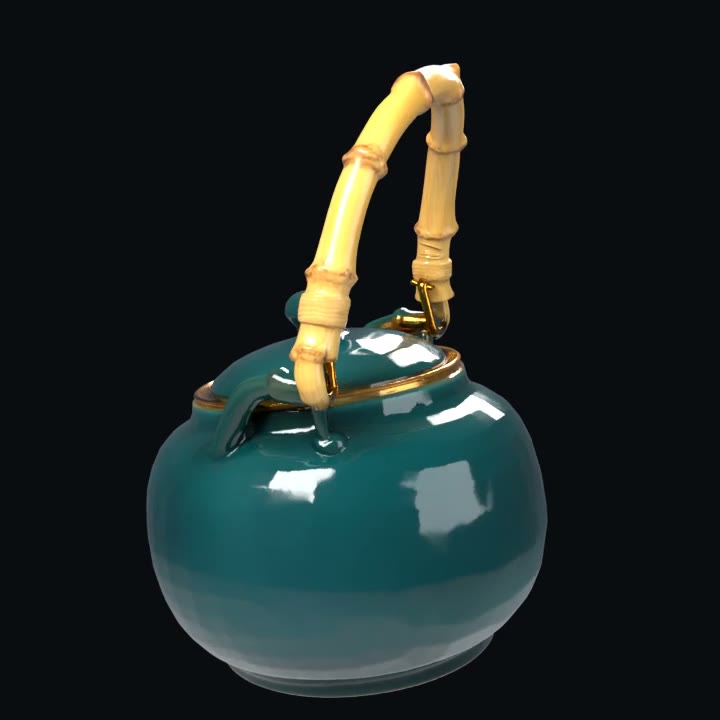
Rear view of the generated 3D model: teapot
AI-generated Rear view of the generated GLB (r-teapot-1, teapot). The input image never shows this side, so the model invents it. · 92.64 s Prompt: Image to 3D from the input image shown above, seed 42, author defaults. full size
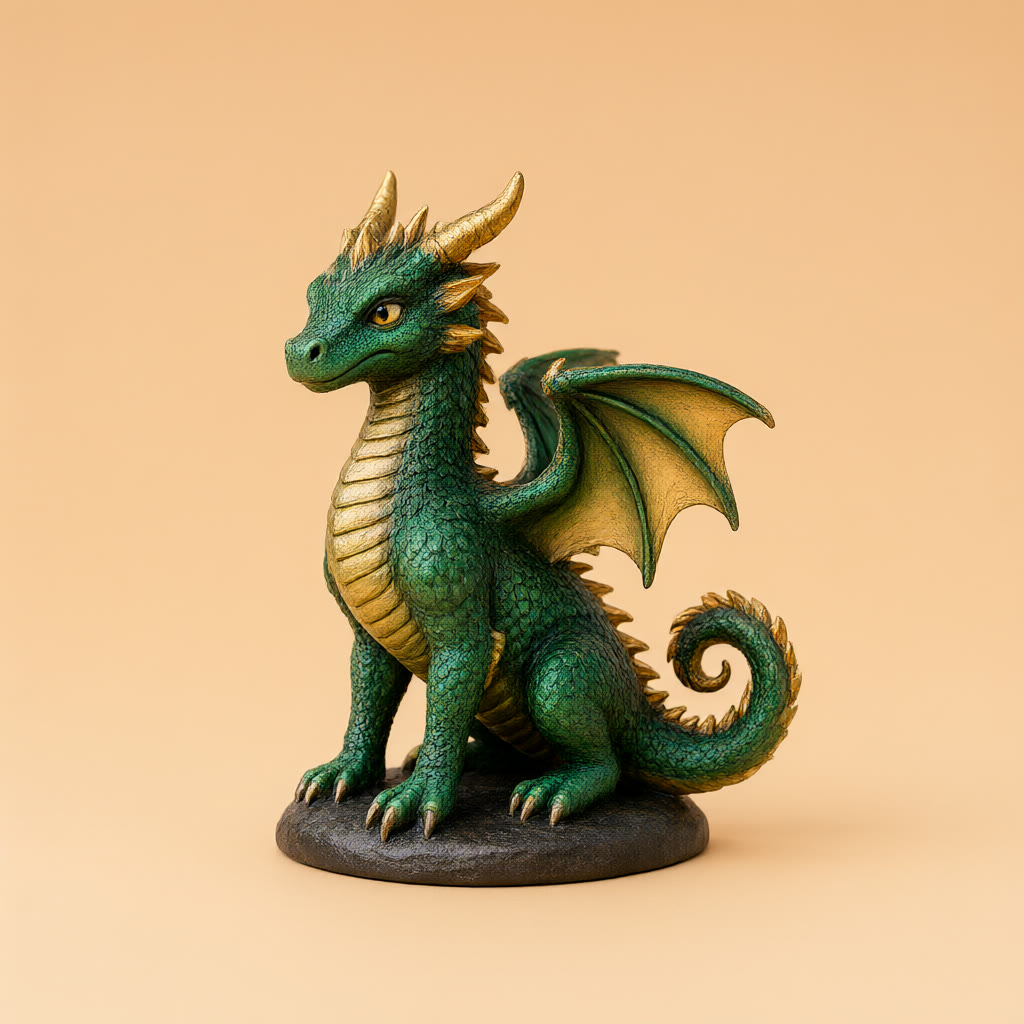
Input image: Dragon figurine
AI-generated Input image: Dragon figurine. Own input made with Qwen-Image 2.1 Turbo NVFP4 (seed 42, 1024×1024), opaque RGB copy as fed to SUPRA-Tex. SUPRA-Tex time for this image: 114.56 s. · 114.56 s Prompt: A hand-painted collectible dragon figurine with emerald green scales, golden horns, folded wings and a curled tail, resin statue on a small round base. Single object, centered and fully inside the frame with generous margin on all sides, plain seamless solid soft peach background, soft even studio lighting with a soft contact shadow, sharp focus, high detail, collectible figure product photograph, no text, no logo, no brand name, no people. full size
AI-generated video Turntable of the real output GLB of r-dragon-1 (dragon figurine): one full turn, rendered with Blender Cycles for display only, no edits to the model. SUPRA-Tex time for this image: 114.56 s.
Prompt

Image to 3D from the input image shown above, seed 42, author defaults.
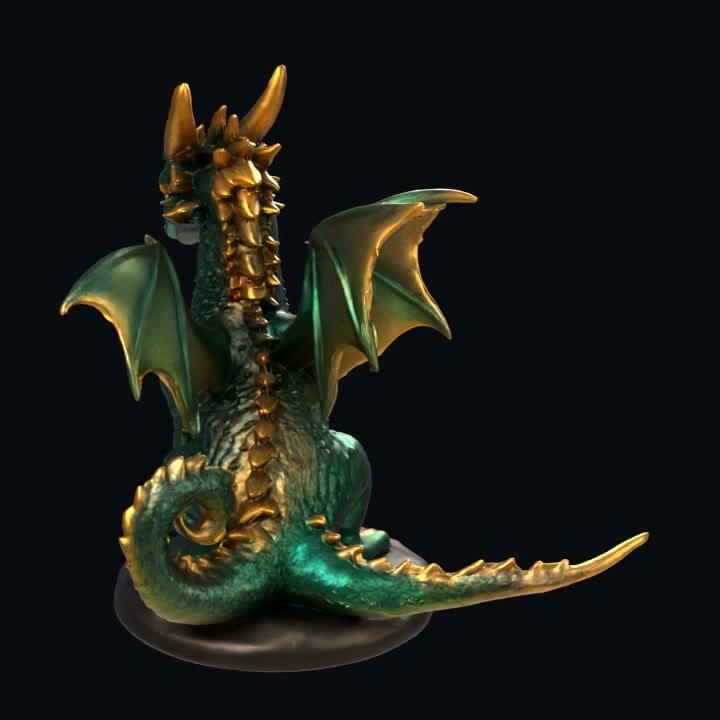
Rear view of the generated 3D model: dragon figurine
AI-generated Rear view of the generated GLB (r-dragon-1, dragon figurine). The input image never shows this side, so the model invents it. · 114.56 s Prompt: Image to 3D from the input image shown above, seed 42, author defaults. full size
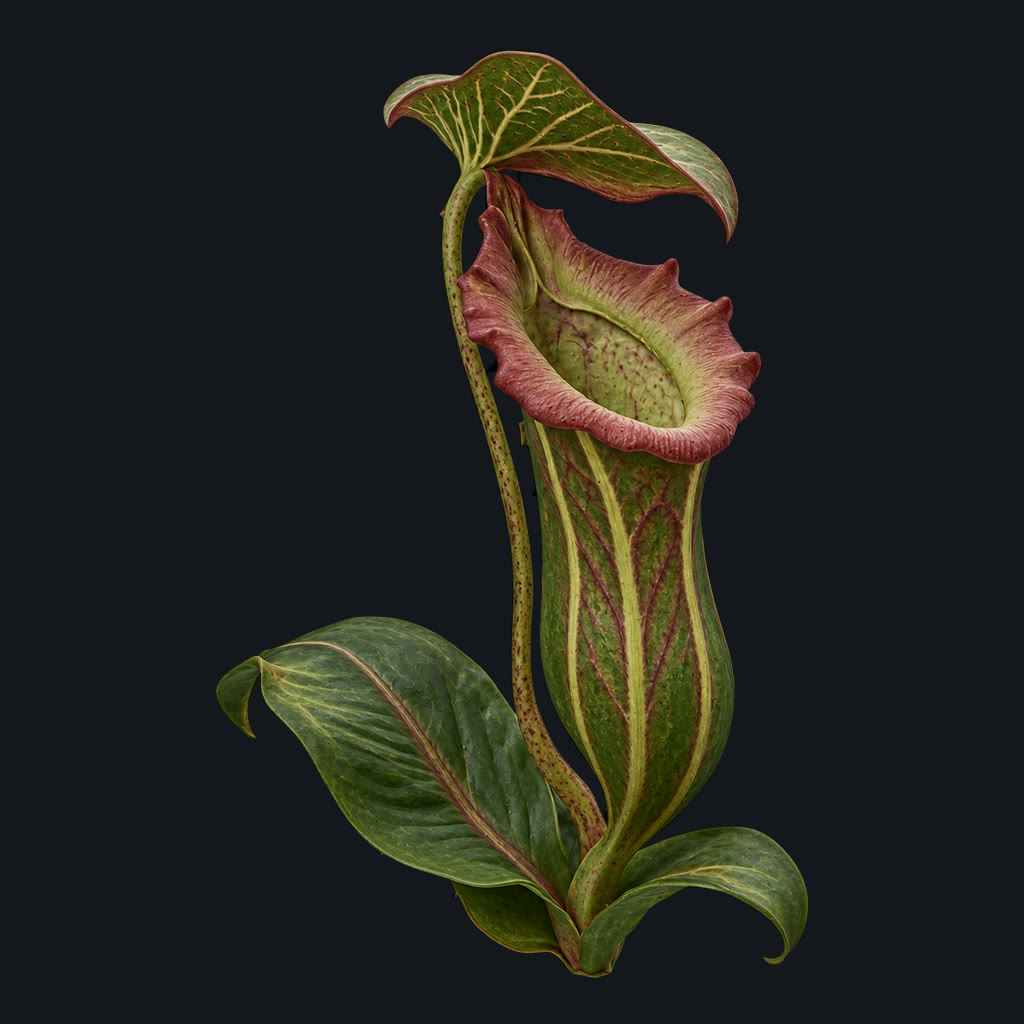
Input image: Pitcher plant
AI-generated Input image: Pitcher plant. Author example (pitcher_plant.png, transparent background, shown on dark grey; its own alpha channel is the mask). SUPRA-Tex time for this image: 1 warm run, 161.51 s. · 161.51 s Prompt: Author example image from the SUPRA-Tex repository (no prompt given). full size
Input image: Metalwork candle jar
AI-generated Input image: Metalwork candle jar. Author example (metalwork_candle_jar.png, RGB, mask by BiRefNet). SUPRA-Tex time for this image: 1 warm run, 210.58 s. · 210.58 s Prompt: Author example image from the SUPRA-Tex repository (no prompt given). full size
Input image: Steampunk airship
AI-generated Input image: Steampunk airship. Own input made with Qwen-Image 2.1 Turbo NVFP4 (seed 42, 1024×1024), opaque RGB copy as fed to SUPRA-Tex. SUPRA-Tex time for this image: 118.70 s. · 118.70 s Prompt: A detailed miniature model of a steampunk airship with a cream canvas balloon, brass bands and rivets, a small wooden gondola and two tiny propellers, standing on a small round display stand. Single object, centered and fully inside the frame with generous margin on all sides, plain seamless solid pale grey background, soft even studio lighting with a soft contact shadow, sharp focus, high detail, collectible figure product photograph, no text, no logo, no brand name, no people. full size
Input image: Vinyl astronaut toy
AI-generated Input image: Vinyl astronaut toy. Own input made with Qwen-Image 2.1 Turbo NVFP4 (seed 42, 1024×1024), opaque RGB copy as fed to SUPRA-Tex. SUPRA-Tex time for this image: 97.14 s. · 97.14 s Prompt: A vinyl designer toy astronaut figurine in a white spacesuit with a fully reflective gold visor that hides the face, small backpack, no patches and no flags. Single object, centered and fully inside the frame with generous margin on all sides, plain seamless solid pale mint background, soft even studio lighting with a soft contact shadow, sharp focus, high detail, collectible figure product photograph, no text, no logo, no brand name, no people. full size
Input image: Toy locomotive
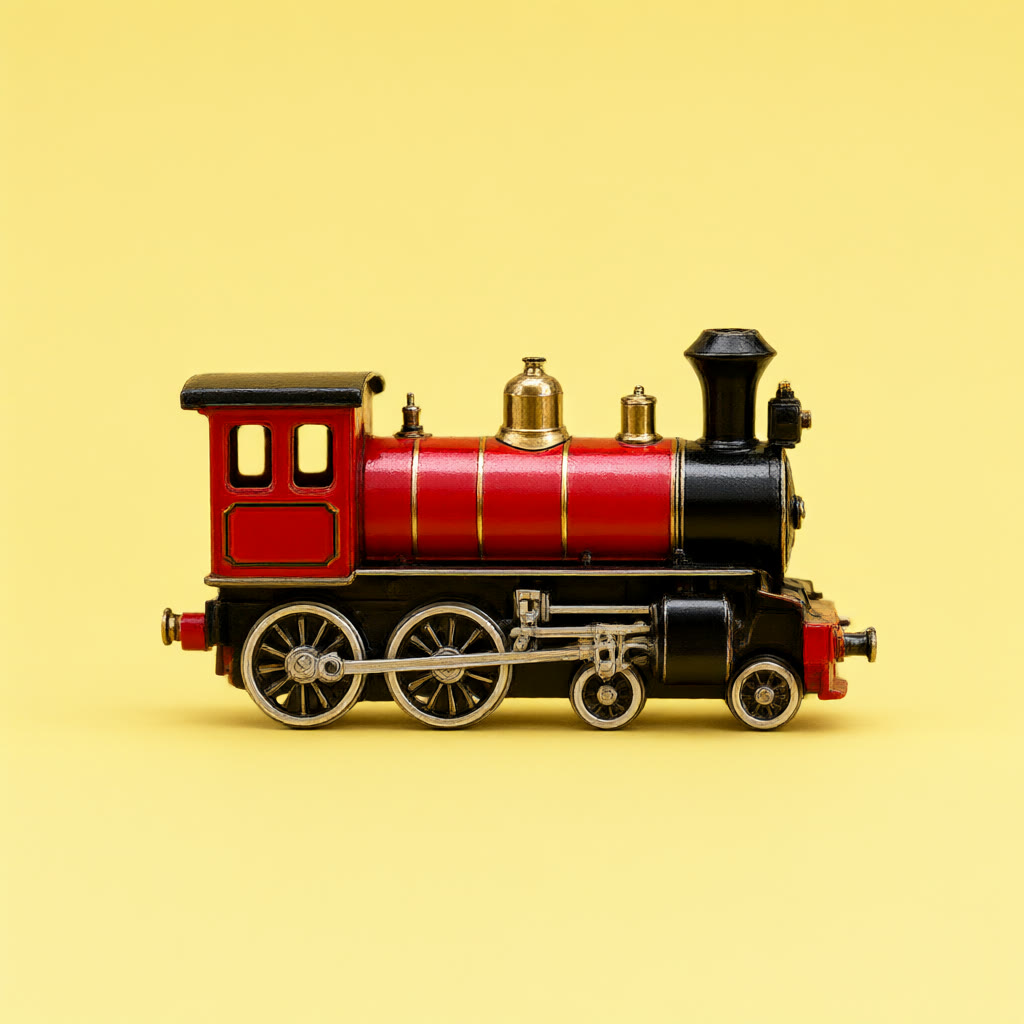
AI-generated Input image: Toy locomotive. Own input made with Qwen-Image 2.1 Turbo NVFP4 (seed 42, 1024×1024), opaque RGB copy as fed to SUPRA-Tex. SUPRA-Tex time for this image: 93.50 s. · 93.50 s Prompt: A toy steam locomotive made of painted tin, red and black with brass details, big wheels and a small chimney, side view. Single object, centered and fully inside the frame with generous margin on all sides, plain seamless solid pale yellow background, soft even studio lighting with a soft contact shadow, sharp focus, high detail, collectible figure product photograph, no text, no logo, no brand name, no people. full size
Input image: Robot holding a graphics card
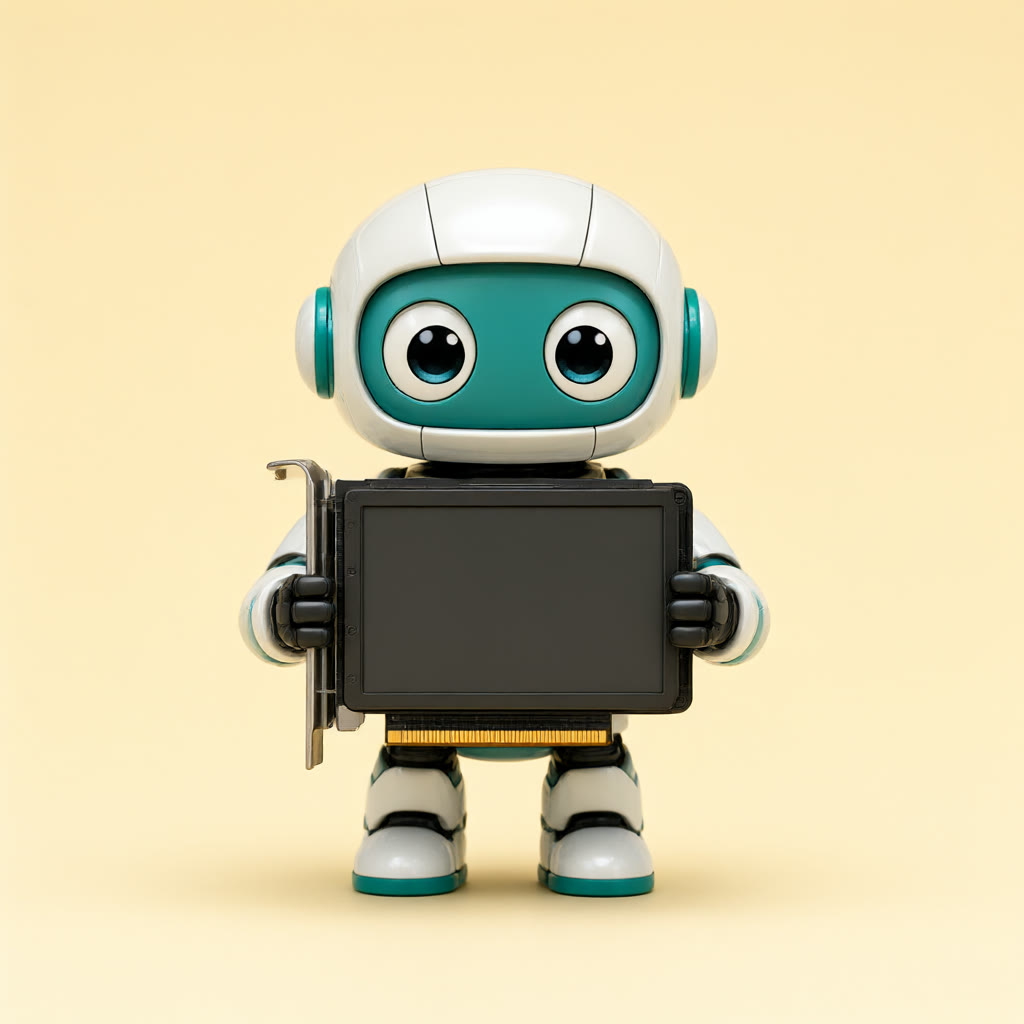
AI-generated Input image: Robot holding a graphics card. Own input made with Qwen-Image 2.1 Turbo NVFP4 (seed 42, 1024×1024), opaque RGB copy as fed to SUPRA-Tex. SUPRA-Tex time for this image: 145.42 s. · 145.42 s Prompt: A cute small round robot figure with big round eyes, glossy white and teal plastic, holding a blank graphics card in both hands, the card has no logo and no text, vinyl collectible toy. Single object, centered and fully inside the frame with generous margin on all sides, plain seamless solid warm cream background, soft even studio lighting with a soft contact shadow, sharp focus, high detail, collectible figure product photograph, no text, no logo, no brand name, no people. full size
Input image: Robot watering a plant
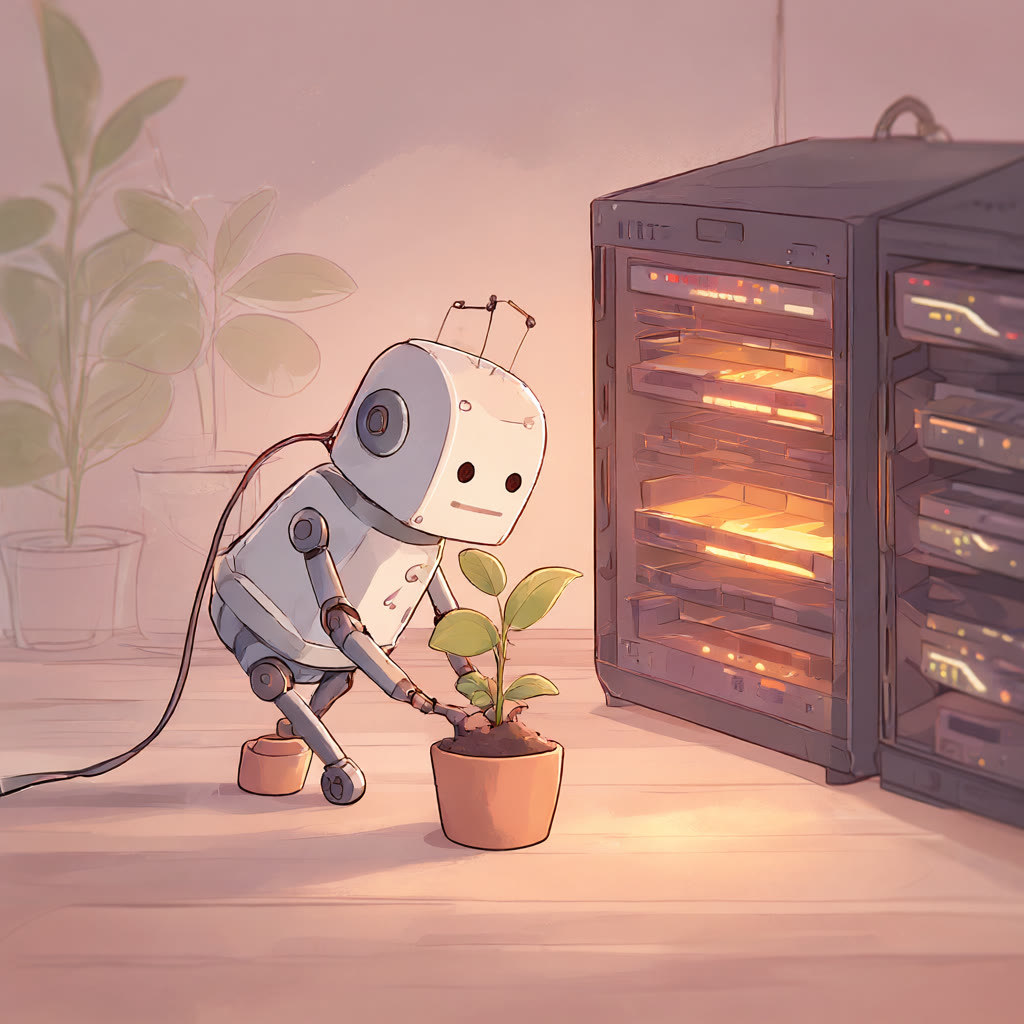
AI-generated Input image: Robot watering a plant. Own input from an earlier image test of 12 Oct 2026: Qwen-Image 2.1 NVFP4 on the RTX 5090, 1024×1024, 25 steps, opaque RGB copy as fed to SUPRA-Tex. SUPRA-Tex time for this image: 87.95 s. · 87.95 s Prompt: A tiny robot watering a plant next to a glowing GPU rack in a cozy home server room, warm pastel illustration. full size
Table

All 10 images: the three author examples first, then our own images in alphabetical order. This is not a ranking. Times are wall-clock seconds of the whole run_example.py call; the GLB figures are those of the median run (README example: run 2 of 3). MB = 10^6 bytes.

ImageSourceTime (s)Warm runsTrianglesVerticesGLB (MB)Peak VRAM (MiB)Silhouette IoU
Spiny whelk shellAuthor example96.243493,898310,88444.820,9210.993
Pitcher plantAuthor example161.511485,518374,21446.420,9210.950
Metalwork candle jarAuthor example210.581496,743345,03241.520,9230.984
Steampunk airshipOwn image118.701475,529417,41754.720,9230.947
Vinyl astronaut toyOwn image97.141465,640335,55045.920,9230.983
Dragon figurineOwn image114.561476,041332,58946.420,9230.962
Toy locomotiveOwn image93.501494,099362,51751.820,9230.961
Robot holding a graphics cardOwn image145.421492,105387,39952.820,9230.980
Robot watering a plantOwn image87.951490,424374,74946.020,9230.951
TeapotOwn image92.641499,934339,58646.620,9230.969

Raw file

Setup

How it was run

  • Pipeline: foreground mask, camera (MoGe-2), Pixal3D geometry, material maps with Qwen-Image-2.1 plus the SUPRA-Tex adapter, 2.1B completion model, PBR GLB export. Author defaults: seed 42, 4096 px textures, decimation target 500,000 triangles, PNG textures, one request at a time.
  • Code: Supra-3D/SUPRA-Tex commit cee4435 (29 Oct 2026), unchanged, started with scripts/run_example.py exactly as in the README. Weights as released (SUPRA-Tex revision 1bc02eb9 on Hugging Face, other models at the revisions in the author's configs/pipeline.json), no extra quantisation, sha256 checked.
  • Software: PyTorch 2.13.0 with CUDA 13.0, Python 3.12.13, Triton 3.7.1, PyTorch SDPA attention, FlexGEMM sparse-convolution backend. The author pins PyTorch 2.6.0 with CUDA 12.4 and Python 3.10 (see notes).
  • Memory: CPU offload off (low_vram=False in every run); the author's code keeps all models on a card above 24 GiB.
  • Method: time per image = wall clock of one complete run_example.py call (model loading, geometry, material, completion, GLB export). One warm run per image, the README example as median of 3 warm runs; the median over the 10 images is 105.85 s. The first run after creating empty compile caches (Triton, FlexGEMM autotune, torch extensions, numba, CUDA, Inductor) is counted separately.
  • Inputs: 3 author example images and 7 own images made with Qwen-Image 2.1 (opaque RGB). RGB inputs were masked with BiRefNet, the two RGBA author examples use their own alpha channel.
  • Peak VRAM: nvidia-smi sample every second during the call. Triangles, vertices, file size and texture size: read from the output GLB files with trimesh. Silhouette IoU: the 'Observation: silhouette IoU' line of the author's own log.
  • Box: no other process on the card, no download and no ffmpeg during a measurement; one RTX 5090 32 GB.
Notes

What to keep in mind

Measured on this device only (one RTX 5090 32 GB), not ranked. The author's own VRAM figure comes from an RTX 3090 with CPU offload and is not comparable to ours (offload off).

Forced deviation 1, PyTorch: the author pins PyTorch 2.6.0 (CUDA 12.4, Python 3.10, torchvision 0.21.0). Those builds contain no sm_120 kernels and nvcc 12.4 does not know sm_120, so the RTX 5090 (Blackwell) cannot run them. We used PyTorch 2.13.0 with CUDA 13.0, Python 3.12.13, Triton 3.7.1 and torchvision 0.28.0. The author's check_runtime.py refuses any other version, so only its import checks were run; the rest was checked by the real runs. The other Python packages are at the author's pinned versions.

Forced deviation 2, NATTEN: NATTEN 0.17.5 (the author's version) was rebuilt from the source package for sm_120, because the author only names a wheel for PyTorch 2.6 with CUDA 12.4. Two changes, see natten-patch-0311.diff: the architecture check 'arch < 100' in setup.py became 'arch < 130', and the type-only import torch.cuda._device_t, which PyTorch 2.13 no longer has, was replaced.

Forced deviation 3, BiRefNet: the author's default mask model RMBG-2 (BRIA) is gated and we have no access, so ZhengPeng7/BiRefNet was used, which the author's README names as the open alternative. It masked the 7 own images and the candle jar. The two RGBA author examples (whelk, pitcher plant) use their own alpha channel. The run receipts call the config key 'rmbg2'; that slot holds the BiRefNet files (foreground-model-config.json, foreground-source.txt).

Further differences to the author's build: FlexGEMM and CuMesh were built on this box for sm_120 from commits newer than the author's pins (FlexGEMM b1965ad, CuMesh ef40f3a); the newer CuMesh commit contains an upstream Blackwell fix. These commits are recorded in our build notes only, no build log was kept. Python 3.12, Triton 3.7.1 and torchvision 0.28.0 follow from PyTorch 2.13. numba 0.65.1 (the author's pin) needed llvmlite 0.47.0.

Weakness: the model invents the back of every object, because the input image never shows it. The rear views above are the model's guess; this test does not check whether they are right. The author's README also warns that the Pixal3D geometry is sometimes shifted or has extra parts.

What this test does not measure: no quality score for geometry or texture. The silhouette IoU column is the author's own log line (0.947 to 0.993, above its warning level of 0.9), not our rating. 3D output was not judged in a viewer.

Spread: the three warm README runs took 93.16 s to 106.02 s (about 13 % apart); 9 of 10 images have one warm run only. With the first warm whelk run alone (106.02 s) the median over 10 images would be 110.29 s. Time depends strongly on the image (88 s to 211 s): step 1 (mask, camera, geometry, material maps) ended after 39 to 97 s, step 2 (completion and export) took 46 to 112 s; we did not investigate why.

First run: 238.74 s with empty compile caches. The operating system file cache could not be emptied, so the model files were already in RAM; this is not a cold-disk time.

Turntable clips and rear views are Blender renders of the real GLB files (display only); 7 of the 10 GLB files have no preview render. The GLB files are 41.5 to 54.7 MB each and are not published here.

Inputs: 6 own images were made with Qwen-Image 2.1 Turbo NVFP4 (Hugging Face BennyDaBall/Qwen-Image-2.1-Turbo-NVFP4, revision cb5a4e68cb74), the robot-plant image with Qwen-Image 2.1 NVFP4. The candle jar input contains printed text that comes from the author's example image.

License (info line, not blocking): SUPRA-Tex code and the completion weights are MIT; the material adapter and the Qwen-Image-2.1 base are under the Qwen Research License (non-commercial research and evaluation, 'Built with Qwen'); DINOv3 has its own Meta license.